QuixiAI/SYN-1B
收藏资源简介:
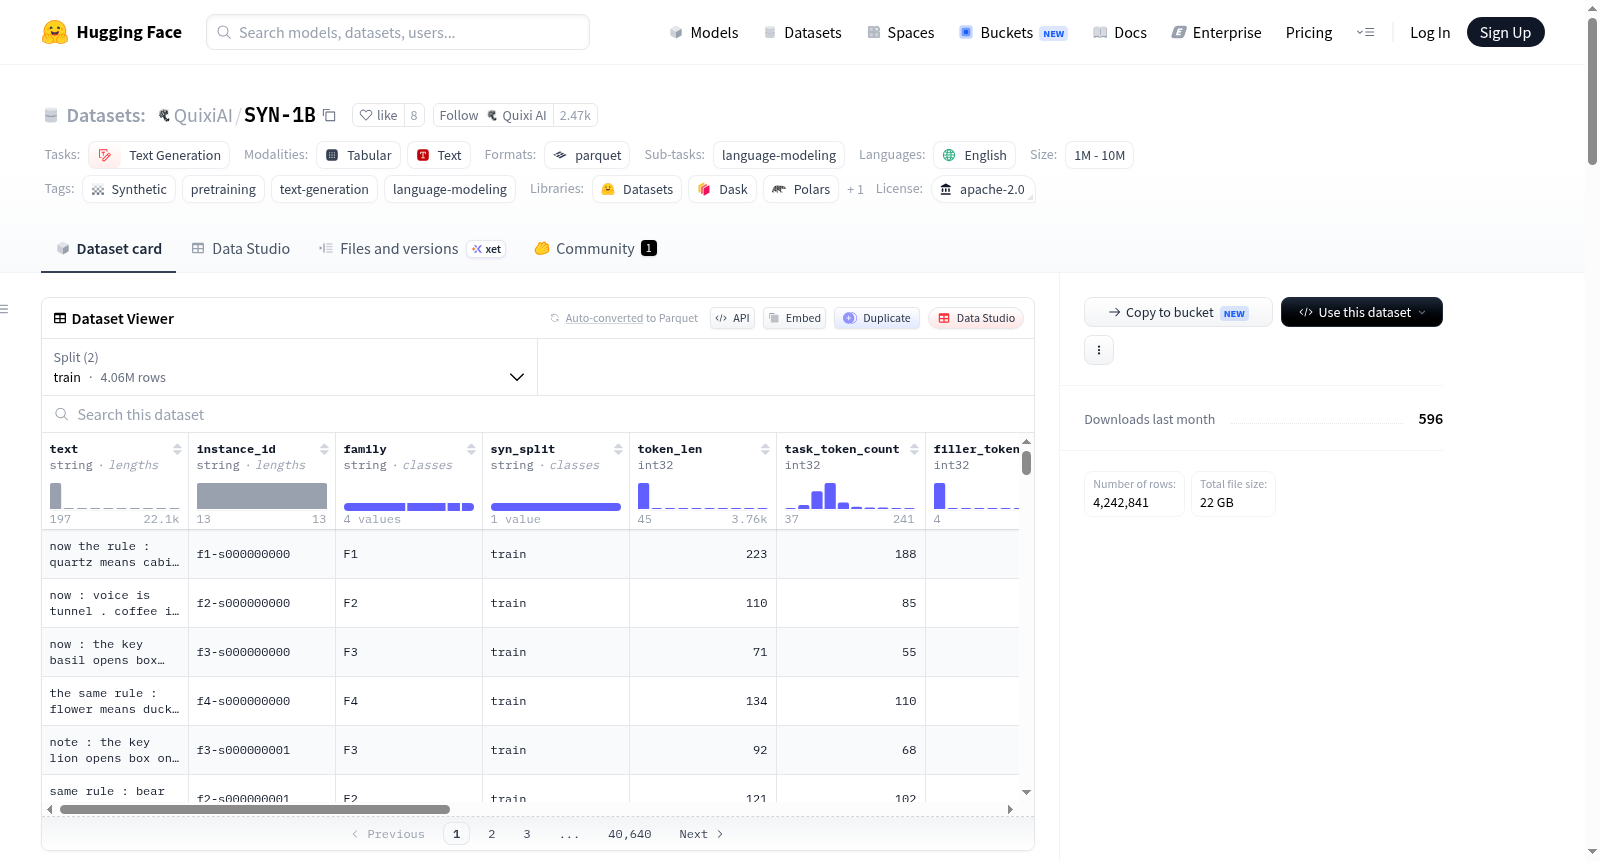
--- language: - en license: apache-2.0 tags: - synthetic - pretraining - text-generation - language-modeling task_categories: - text-generation task_ids: - language-modeling size_categories: - 1M<n<10M pretty_name: SYN-1B configs: - config_name: default data_files: - split: train path: data/train-*.parquet - split: validation path: data/validation-*.parquet train-eval-index: - config: default task: text-generation task_id: language-modeling splits: train_split: train eval_split: validation col_mapping: text: text --- # SYN-1B <img src="https://cdn-uploads.huggingface.co/production/uploads/63111b2d88942700629f5771/CsFvFjDP27FD0M1AhlWA1.png" width="600" /> ## Dataset Summary SYN-1B is a 1.04B-token synthetic language-modeling corpus of rule-governed text streams. Each row is a decoded instance in which the text establishes facts, mappings, bindings, or simple generative rules; later spans may revise those rules, swap bindings, delay a query over long filler, or present a null control with event-like surface text that should not change the answer. The dataset is intended as structured pretraining data, not as a supervised instruction dataset. It uses ordinary next-token prediction, but the examples are generated from known latent state machines. That makes it useful when a researcher wants training data where long-context behavior, variable binding, belief revision, recency, distractor robustness, and held-out transfer can be measured exactly rather than inferred from natural text. The [data/](data/) Parquet files expose one decoded synthetic instance per row in the `text` column. The original packed `uint16` token shards, sidecars, and QA manifests are kept under [raw/](raw/) for exact token-level training and audit use. The Hugging Face `validation` split corresponds to the SYN generator's `eval` split. F5 appears only in that held-out eval/validation split. ## Why Pretrain With It? SYN-1B gives language models repeated practice on behaviors that are important in real use but sparse, ambiguous, or hard to label in web text: - Tracking a rule or binding across many intervening tokens. - Updating an answer after a correction instead of copying the most recent local surface pattern. - Preserving unchanged facts when only part of a rule changes. - Distinguishing real state-changing events from plausible-looking distractors. - Answering from evidence that may be hundreds or thousands of tokens old. - Transferring the same abstract update pattern to a held-out surface format. For general pretraining, SYN-1B can be mixed as a small synthetic fraction alongside web, education, code, or domain corpora to add dense, auditable examples of state tracking and revision. It is especially relevant for work on long-context models, recurrent or memory-augmented models, retrieval-free reasoning, continual belief updating, and curricula that target systematic generalization. ## Other Applications Beyond pretraining, SYN-1B can be used as: - A controlled benchmark for long-context recall and rule updating. - A source of probing data for whether hidden states encode active mappings, bindings, recency, and corrected values. - A stress test for distractor sensitivity and surface-marker shortcuts. - A data generator baseline for synthetic-curriculum, data-mixture, and scaling-law studies. - A reproducible corpus for mechanistic interpretability, because the raw sidecars under [raw/sidecars/](raw/sidecars/) identify events, writes, query positions, answer positions, evidence spans, composition depth, controlled gap lengths, and held-out families. ## Limitations SYN-1B is synthetic by design. It should not be treated as a substitute for natural-language pretraining data, an instruction-following dataset, or a factuality benchmark. The task families cover a controlled set of rule-updating and long-context patterns, so improvements on SYN-1B should be checked against naturalistic and out-of-distribution evaluations before making broad claims. The decoded Parquet view is convenient for Hugging Face tooling, while the packed token shards and sidecars in [raw/](raw/) are the reference artifacts for exact token-level audits and reproduction. Users who need full supervision metadata should read the sidecars rather than relying only on the compact Parquet columns. ## Task Families The task families isolate different forms of state tracking: | Family | Role | | --- | --- | | F1 branch reversal | A rule holds, then an event changes the active mapping. | | F2 binding swap | Entity-to-attribute bindings are corrected by swaps rather than a single surface marker. | | F3 delayed correction / recall | Old evidence and controlled evidence age test whether stored evidence survives and can be reinterpreted. | | F4 flat null | No interpretive event occurs; event-like distractors test false-positive rule updates. | | F5 modular-stream switch | Eval-only transfer task with no training exposure, used to test transfer beyond memorized surface formats. | ## Source and Reproducibility The generator, QA suite, and build specification are available in the [source repository](https://github.com/quixiai/aum). See [SYN-1B.md](https://github.com/quixiai/aum/blob/main/SYN-1B.md) for the corpus specification. ## How to Load ```python from datasets import load_dataset ds = load_dataset("QuixiAI/SYN-1B") ``` ## Dataset Stats | Split | Rows | Synthetic instance tokens in raw build | | --- | ---: | ---: | | `train` | 4,063,978 | 1,000,001,463 | | `validation` | 178,863 | 40,002,882 | | `total` | 4,242,841 | 1,040,004,345 | The Hugging Face dataset is decoded text. Consumers can tokenize the `text` column with any tokenizer. The token counts above refer to the reference raw build in [raw/](raw/), which was generated and QA-audited with the `HuggingFaceTB/SmolLM2-135M` tokenizer. ## Data Schema Columns: - `text`: decoded synthetic instance text. - `instance_id`, `family`, `syn_split`: stable identifiers and SYN family. - `token_len`, `task_token_count`, `filler_token_count`, `controlled_gap_tokens`, `composition_depth`, `num_queries`: compact per-instance metadata. - `shard`, `window_index`, `start_offset`, `token_hash`: join keys back to the packed raw token stream and sidecar records under [raw/](raw/). ## Licensing Information License: Apache-2.0
SYN-1B is a 1.04B-token synthetic language-modeling corpus of rule-governed text streams. Each row is a decoded instance in which the text establishes facts, mappings, bindings, or simple generative rules; later spans may revise those rules, swap bindings, delay a query over long filler, or present a null control with event-like surface text that should not change the answer. The dataset is intended as structured pretraining data, not as a supervised instruction dataset. It uses ordinary next-token prediction, but the examples are generated from known latent state machines. That makes it useful when a researcher wants training data where long-context behavior, variable binding, belief revision, recency, distractor robustness, and held-out transfer can be measured exactly rather than inferred from natural text.