Maktabati/shamela-vectors
收藏资源简介:
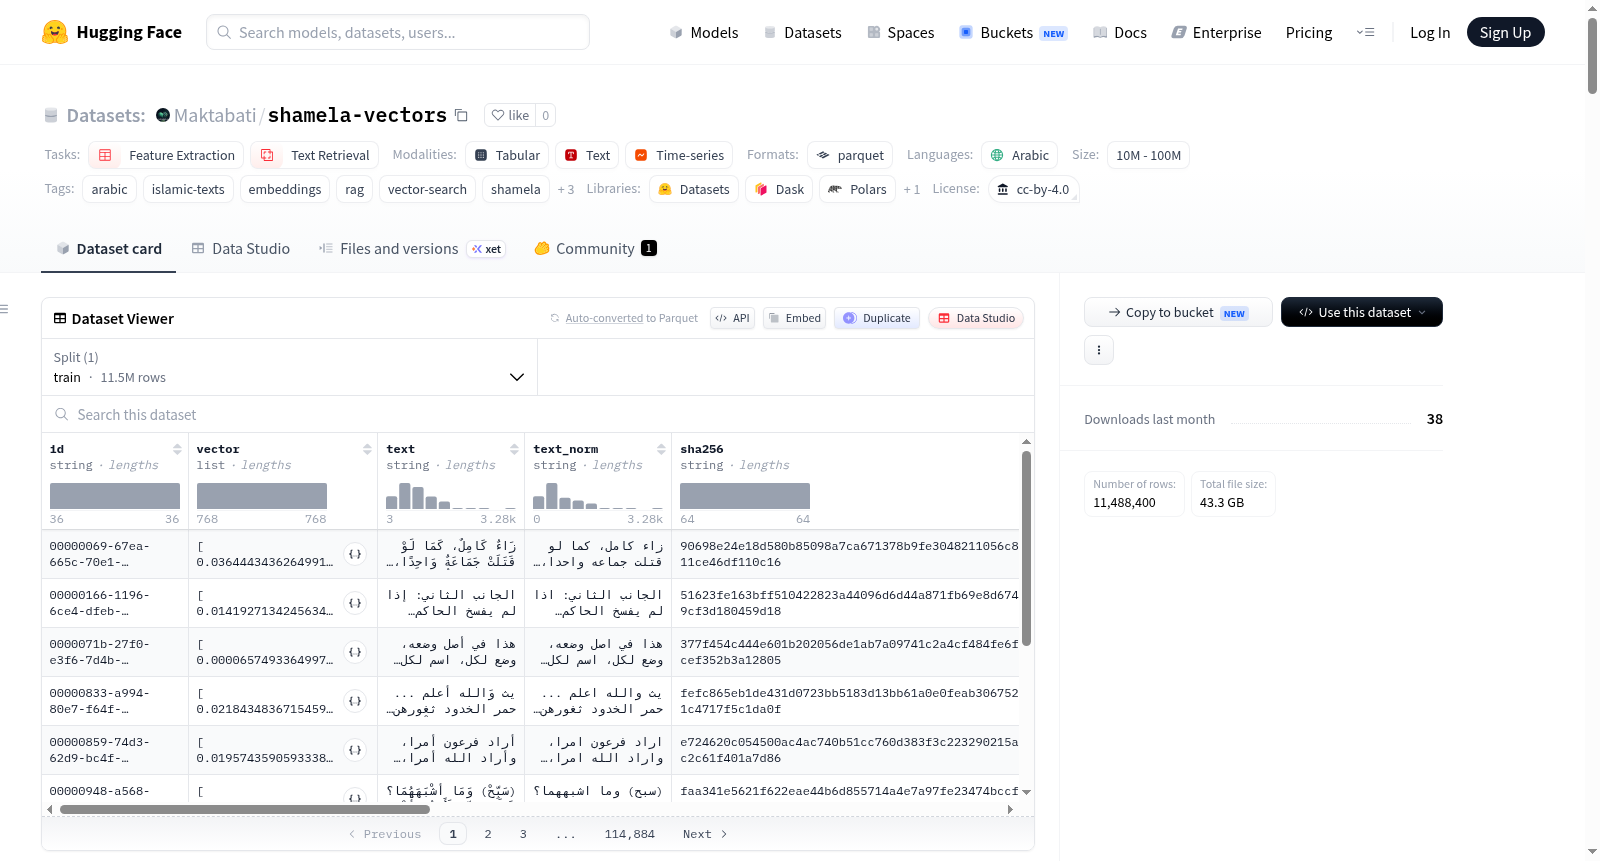
Shamela向量数据库是最大的开源向量数据库,基于完整的al-Maktaba al-Shamela伊斯兰文本语料库,专为语义搜索和检索增强生成(RAG)而设计。它包含约8至11百万个文本块,这些文本块源自8,589本经典伊斯兰书籍,以及完整的《古兰经》文本(6,236节经文,采用Hafs an Asim版本)。数据集涵盖40个伊斯兰学术类别,时间跨度从伊斯兰历1世纪到15世纪,主要语言为阿拉伯语。技术方面,使用intfloat/multilingual-e5-base模型生成768维向量,采用余弦距离度量,分块大小为512个标记,重叠50个标记。数据集字段包括原始文本、规范化文本、SHA-256哈希、作者、标题、死亡年份、语言、页面引用、字符偏移、分块索引、索引时间戳等,并包含Shamela特定字段(如来源、书籍ID、类别ID)和《古兰经》特定字段(如苏拉编号、经文编号)。数据集可用于导入Qdrant进行向量搜索,支持按来源、类别或作者过滤,适用于伊斯兰文本的语义检索和分析。
The largest open-source vector database of the complete al-Maktaba al-Shamela Islamic text corpus, prepared for semantic search and Retrieval-Augmented Generation (RAG). Includes the full Quran text (6,236 verses, Hafs an Asim). Statistics: ~8–11M chunks from 8,589 classical Islamic books, 6,236 Quran verses (one verse = one chunk), 40 categories covering the full breadth of Islamic scholarship, period: 1st century AH to 15th century AH, language: Arabic (primary). Technical details: Embedding model intfloat/multilingual-e5-base, vector dimension 768, distance metric cosine, chunk size 512 tokens, overlap 50 tokens. Dataset fields include text, text_norm, sha256, author, title, death_year, language, page, char_start, char_end, chunk_no, indexed_at, plus Shamela-specific fields (e.g., source, book_id, category_name_ar) and Quran-specific fields (e.g., surah_num, ayah_num). Usage includes import into Qdrant for semantic search with filtering by source, category, or author.