Emirhanmu/agent-workflow-dataset
收藏资源简介:
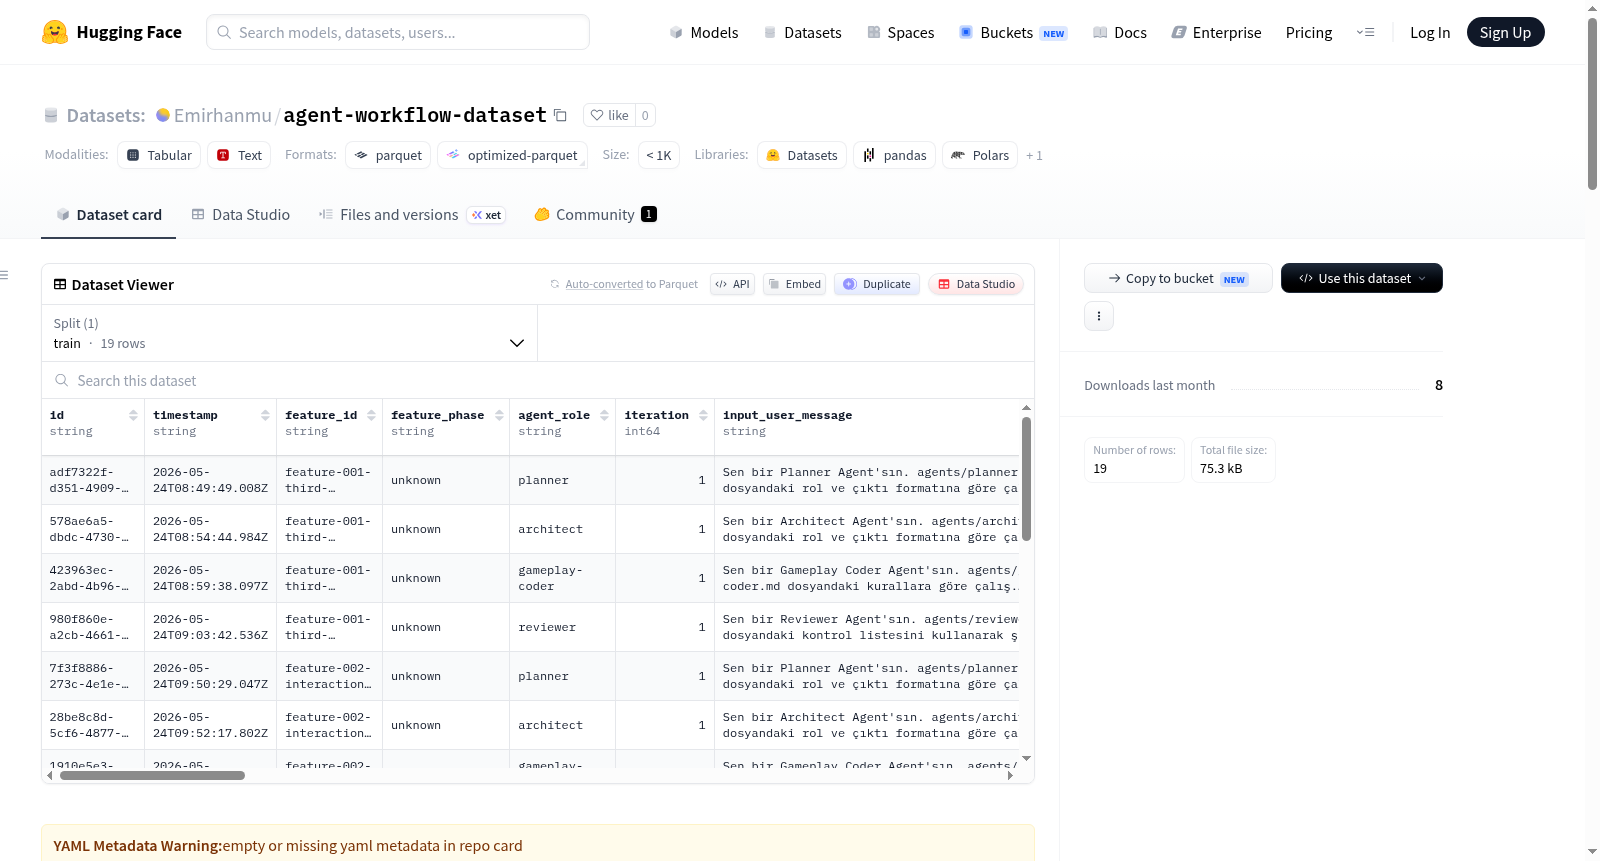
该数据集包含了在Unity游戏开发过程中捕获的真实世界AI智能体交互轨迹,使用基于Claude Code的结构化多智能体工作流。数据集记录了一个单人Unity开发者使用5智能体系统(包括规划师、架构师、游戏玩法程序员、评审员和测试工程师)进行游戏项目开发的工作流。数据自动从Claude Code(VS Code扩展)会话日志中捕获,每条记录代表一次智能体调用,包括发送给智能体的完整提示、包含所有工具调用的完整智能体响应、从工作流信号中提取的隐含人类批准标签、基于评分标准的Claude和GPT评估器的质量分数,以及置信度和标记注释。人类标签通过工作流进展推断(无需手动标记):如果下一个智能体在流水线中更靠后,则标记为“接受”;如果再次调用同一智能体,则标记为“修订”;如果工作流回退到更早的智能体,则标记为“拒绝”;如果会话结束或转移到新功能,则标记为“自动批准”。每条记录由两个独立评估器(Claude和GPT)使用角色特定评分标准进行评分,置信度级别分为高、中、低。标记记录(AI高分但人类拒绝)是高价值分歧案例。数据集版本0.1(2026年5月)包含19条总记录,覆盖5个智能体角色和4个功能,约80%为高置信度,2条标记记录,质量控制成本约0.11美元。目标是在2026年8月前达到500+条记录,覆盖多个功能。许可证为CC-BY 4.0,要求署名,允许商业使用。
This dataset contains agent workflow records from a solo Unity developer working on a game project with a 5-agent system: Planner, Architect, Gameplay Coder, Reviewer, and Test Engineer. Records are captured automatically from Claude Code (VS Code extension) session logs. Each record represents one agent invocation and includes: full prompt sent to the agent, complete agent response with all tool calls, implicit human approval label (extracted from workflow signals), quality scores from Claude and GPT evaluators (rubric-based), and confidence and flag annotations. Human labels are inferred from workflow progression — no manual labeling required: if the next agent is later in the pipeline, label is accepted; if the same agent is called again, label is revised; if workflow is rewound to an earlier agent, label is rejected; if session ended or moved to new feature, label is auto-approved. Each record is scored by two independent evaluators using role-specific rubrics. Confidence levels: high, medium, low. Flagged records (AI high score but human rejected) are high-value disagreement cases. Version 0.1 (May 2026) stats: total records 19, agent roles covered 5, features covered 4, high confidence ~80%, flagged records 2, QC cost ~$0.11. Target: 500+ records across multiple features by August 2026. License: CC-BY 4.0 — attribution required, commercial use allowed.