fdeantoni/max-babbelaar-corpus
收藏资源简介:
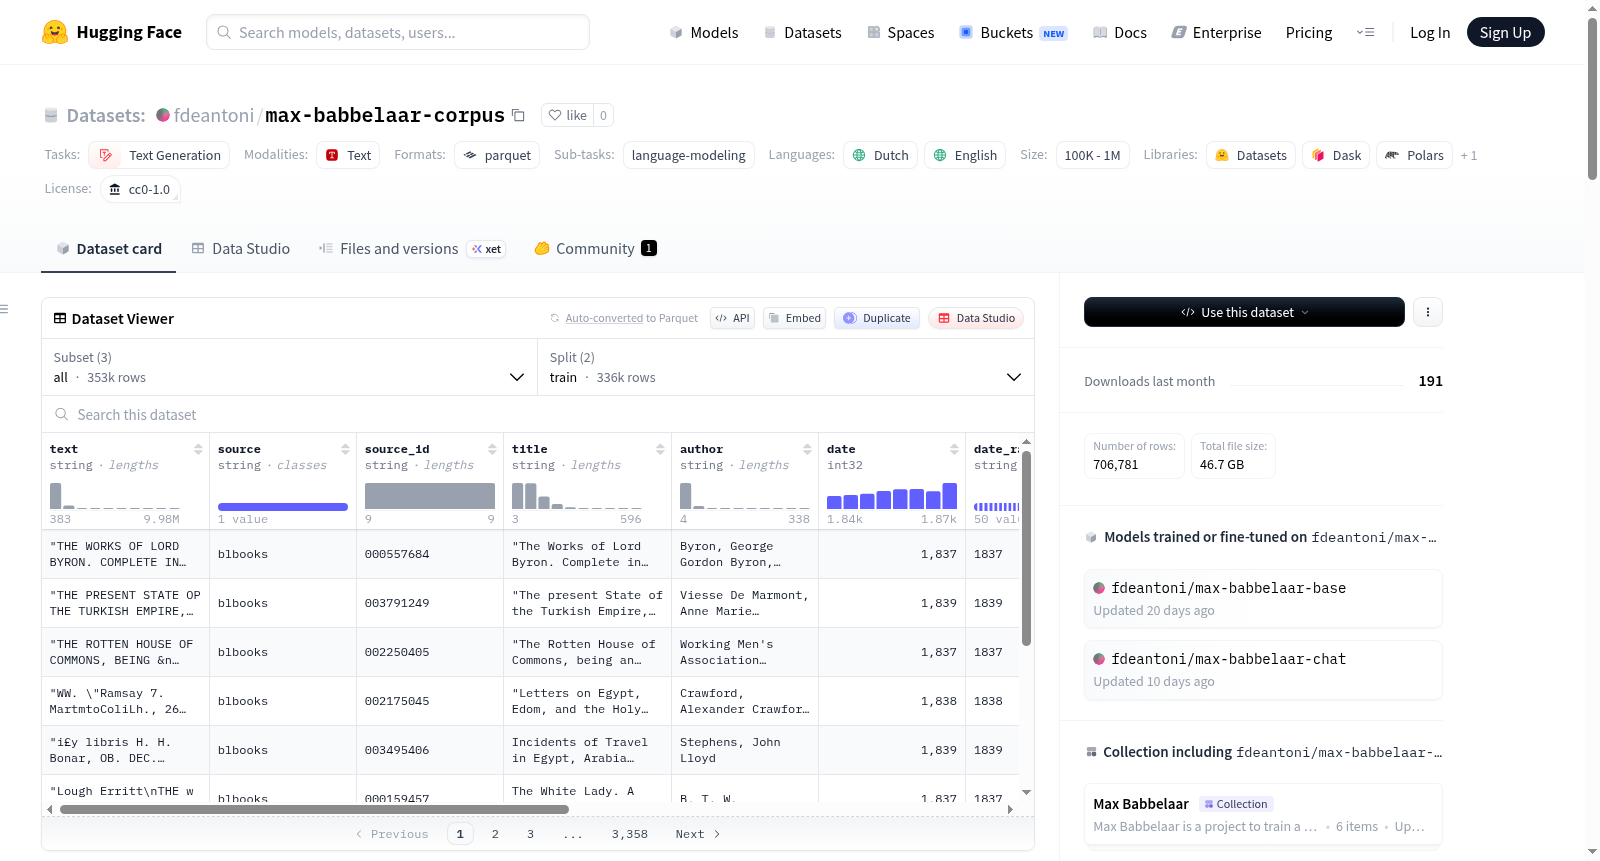
Max Babbelaar Corpus是一个双语(荷兰语和英语)预训练语料库,包含来自公共领域文本的9,077,536,083.0个标记,时间跨度为1753年至1899年。该数据集以Max Havelaar命名,是荷兰语的对应数据集,类似于Victorian British Library文本的Mr. Chatterbox数据集。数据集用于训练Max Babbelaar语言模型,这是一个双语19世纪荷兰绅士角色模型(约3.4亿参数)。数据集包含三个配置:nl(仅荷兰语记录)、en(仅英语记录)和all(两种语言的所有记录)。每个配置包含训练集(约95%)和验证集(约5%),按来源和年代分层。数据来源包括Delpher Kranten、BL Books、DBNL、Gutenberg NL和Dutch Drama Corpus等。所有源文本均为公共领域(1900年前)。数据字段包括文本、来源、来源ID、标题、作者、日期、语言、类型、URL、主题标签和摘要等。数据质量方面,所有记录都通过了最小长度过滤器,少数记录因字母字符比例低而被标记但保留。数据集使用CC0 1.0许可证发布。
The Max Babbelaar Corpus is a bilingual (Dutch + English) pretraining corpus of 9,077,536,083.0 tokens from public domain texts (1753–1899). Named after Max Havelaar, this corpus is the Dutch counterpart to the Mr. Chatterbox dataset of Victorian British Library texts. It is the training corpus for the Max Babbelaar language model — a bilingual 19th-century Dutch gentleman persona (~340M parameters). The dataset includes three configs: nl (Dutch-language records only), en (English-language records only), and all (all records across both languages). Each config contains a train split (~95%) and a validation split (~5%), stratified by source and decade. Data sources include delpher_kranten, blbooks, dbnl, gutenberg_nl, and dutchdracor. All source texts are in the public domain (pre-1900). Data fields include text, source, source_id, title, author, date, language, genre, url, topics, and summary. Data quality is ensured by a minimum length filter, with a small number of records flagged for low alphabetic-character ratio but retained. The dataset is released under CC0 1.0 license.