JOSIE-Zero-8B-Reasoning-Traces-N67
收藏资源简介:
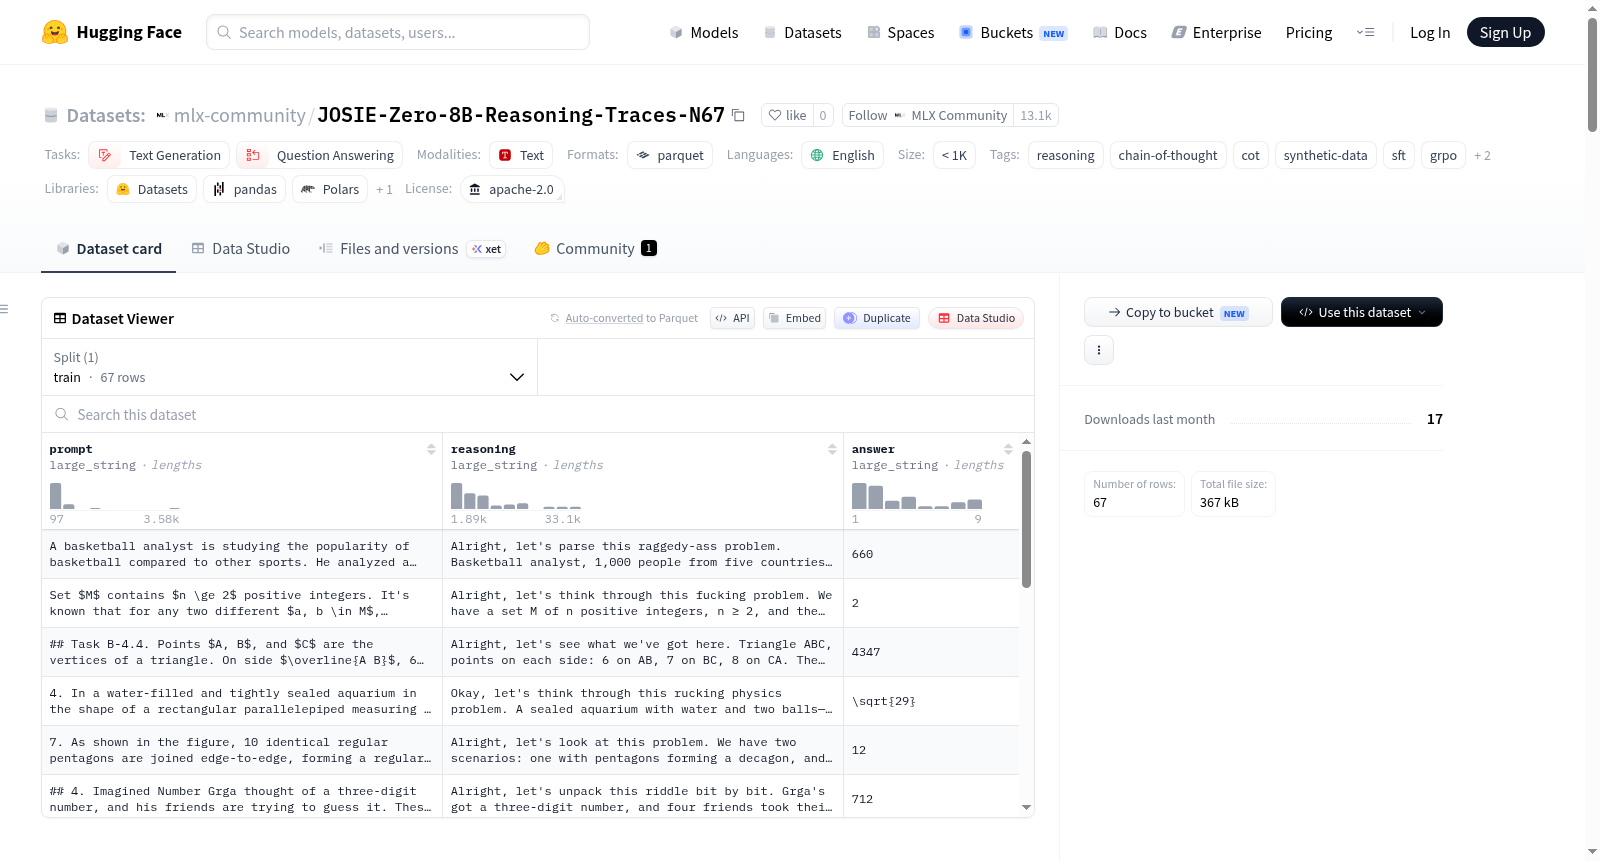
JOSIE-Zero-Reasoning-Traces-N67是一个高质量的合成推理轨迹数据集,专为训练具备推理能力的语言模型而设计。该数据集由JOSIE-ZERO-8B模型生成,该模型通过基于MLX-LM-LoRA框架的GRPO(组相对策略优化)训练流程进行优化,并使用了旨在鼓励显式推理、思维链式问题解决、自我纠正和结构化分析行为的自定义奖励函数。数据集包含67个样本,每个样本由提示(prompt)、推理过程(reasoning)和最终答案(answer)组成,以JSON格式存储。推理过程展示了模型在得出最终答案前的完整多步分析链条。数据规模方面,总推理令牌数为226,271,总令牌数为234,183,平均每个样本包含3,443个令牌,最长的推理链超过11,000个令牌,数据集整体偏向于长形式、详细的推理演示。该数据集主要适用于冷启动监督微调(SFT),为推理模型在进入强化学习阶段(如GRPO、PPO、DPO、RLHF)之前提供初始训练数据。其他推荐用途包括:推理行为蒸馏到较小模型、改进多步推理能力的长思维链训练、以及对涌现推理、长上下文行为、推理令牌效率和RL生成推理轨迹的研究。由于推理链较长,建议使用至少16k(推荐32k+)令牌的上下文窗口进行训练。需要注意的是,数据集中的推理轨迹是合成生成的,推理质量可能因样本而异,且不保证事实正确性。该数据集规模相对较小(67个样本),应被视为推理引导资源而非全面的指令数据集。
JOSIE-Zero-Reasoning-Traces-N67 is a high-quality synthetic reasoning traces dataset designed for training language models with reasoning capabilities. The dataset is generated by the JOSIE-ZERO-8B model, which is optimized through a GRPO (Group Relative Policy Optimization) training process based on the MLX-LM-LoRA framework, using custom reward functions that encourage explicit reasoning, chain-of-thought problem-solving, self-correction, and structured analysis behaviors. The dataset contains 67 samples, each consisting of a prompt, a reasoning process, and a final answer, stored in JSON format. The reasoning process demonstrates the complete multi-step analysis chain before arriving at the final answer. In terms of data scale, the total reasoning tokens are 226,271, total tokens are 234,183, with an average of 3,443 tokens per sample, and the longest reasoning chain exceeds 11,000 tokens, making the dataset overall biased towards long-form, detailed reasoning demonstrations. This dataset is primarily suitable for cold-start supervised fine-tuning (SFT), providing initial training data for reasoning models before entering reinforcement learning stages (such as GRPO, PPO, DPO, RLHF). Other recommended uses include: distilling reasoning behaviors into smaller models, long chain-of-thought training to improve multi-step reasoning capabilities, and research on emergent reasoning, long-context behavior, reasoning token efficiency, and RL-generated reasoning traces. Due to the long reasoning chains, it is recommended to use a context window of at least 16k (preferably 32k+) tokens for training. It should be noted that the reasoning traces in the dataset are synthetically generated, reasoning quality may vary by sample, and factual correctness is not guaranteed. The dataset is relatively small (67 samples) and should be considered as a reasoning guidance resource rather than a comprehensive instruction dataset.
数据集名称
JOSIE-Zero-Reasoning-Traces-N67
许可证
Apache-2.0
语言
英语
任务类别
- 文本生成
- 问答
数据集规模
少于 1,000 个样本(实际 67 个样本)
数据集概述
该数据集包含由 JOSIE-ZERO-8B 模型生成的推理轨迹,格式为“提示-推理-答案”三元组。推理过程包含模型在得出最终答案前的完整推理链,旨在为具备推理能力的语言模型提供冷启动监督微调 (Cold Start SFT) 数据。
生成管道
推理轨迹由 JOSIE-ZERO-8B 模型生成,该模型通过以下方式训练:
- GRPO (Group Relative Policy Optimization) 强化学习
- 自定义奖励函数,重点关注:
- 推理深度
- 自我验证与诚实性
- 多步问题求解
- 最终答案正确性
生成的轨迹比标准指令微调模型具有更长、更详细的推理链。
推荐用途
- 冷启动 SFT:在 RL 训练前,训练基础模型生成显式推理轨迹
- 推理蒸馏:将推理行为蒸馏到更小的模型中
- 长链思维训练:提升多步推理能力
- 研究:可用于研究涌现推理、长上下文行为、推理 token 效率以及 RL 生成的推理轨迹
数据集统计
| 指标 | 值 |
|---|---|
| 样本数量 | 67 |
| 原始推理 Token 总数 | 226,271 |
| 所有样本总 Token 数 | 234,183 |
| 最大 Token 数 | 11,033 |
| 最小 Token 数 | 659 |
| 每个样本平均 Token 数 | 3,443 |
数据分布有意偏向长文本推理,适合长上下文微调、推理 SFT 和思维链蒸馏。
数据格式
每个样本包含三个字段:
prompt:问题或指令reasoning:完整的推理过程链answer:最终答案
示例 schema (JSON): json { "prompt": "Solve the following problem...", "reasoning": "First, lets analyze...", "answer": "The final answer is ..." }
训练建议
- 训练阶段:冷启动 SFT、推理 SFT、蒸馏训练
- 上下文长度:推理轨迹可能超过 11,000 个 token,建议至少使用 16k 的上下文窗口,32k+ 更佳
- 适用场景:推理型 LLM、数学推理模型、智能体基础模型、RL 预热模型、长上下文助手
局限
- 推理轨迹由 AI 模型合成生成,质量因样本而异
- 数据集规模较小(仅 67 个样本)
- 生成的推理不保证事实正确性
- 应视为推理引导资源,而非全面的指令数据集
致谢
由 Gökdeniz Gülmez 创建,使用以下工具生成:
- JOSIE-ZERO-8B
- MLX-LM-LoRA
- GRPO 训练管道
- 自定义奖励函数
引用
bibtex @dataset{josie_zero_reasoning_traces_n67, title={JOSIE-Zero-Reasoning-Traces-N67}, author={Gülmez, Gökdeniz}, year={2026}, publisher={Hugging Face} }
许可证
请参考仓库许可证了解使用和重新分发的条款。