VERICODER fine-tuning dataset
收藏资源简介:
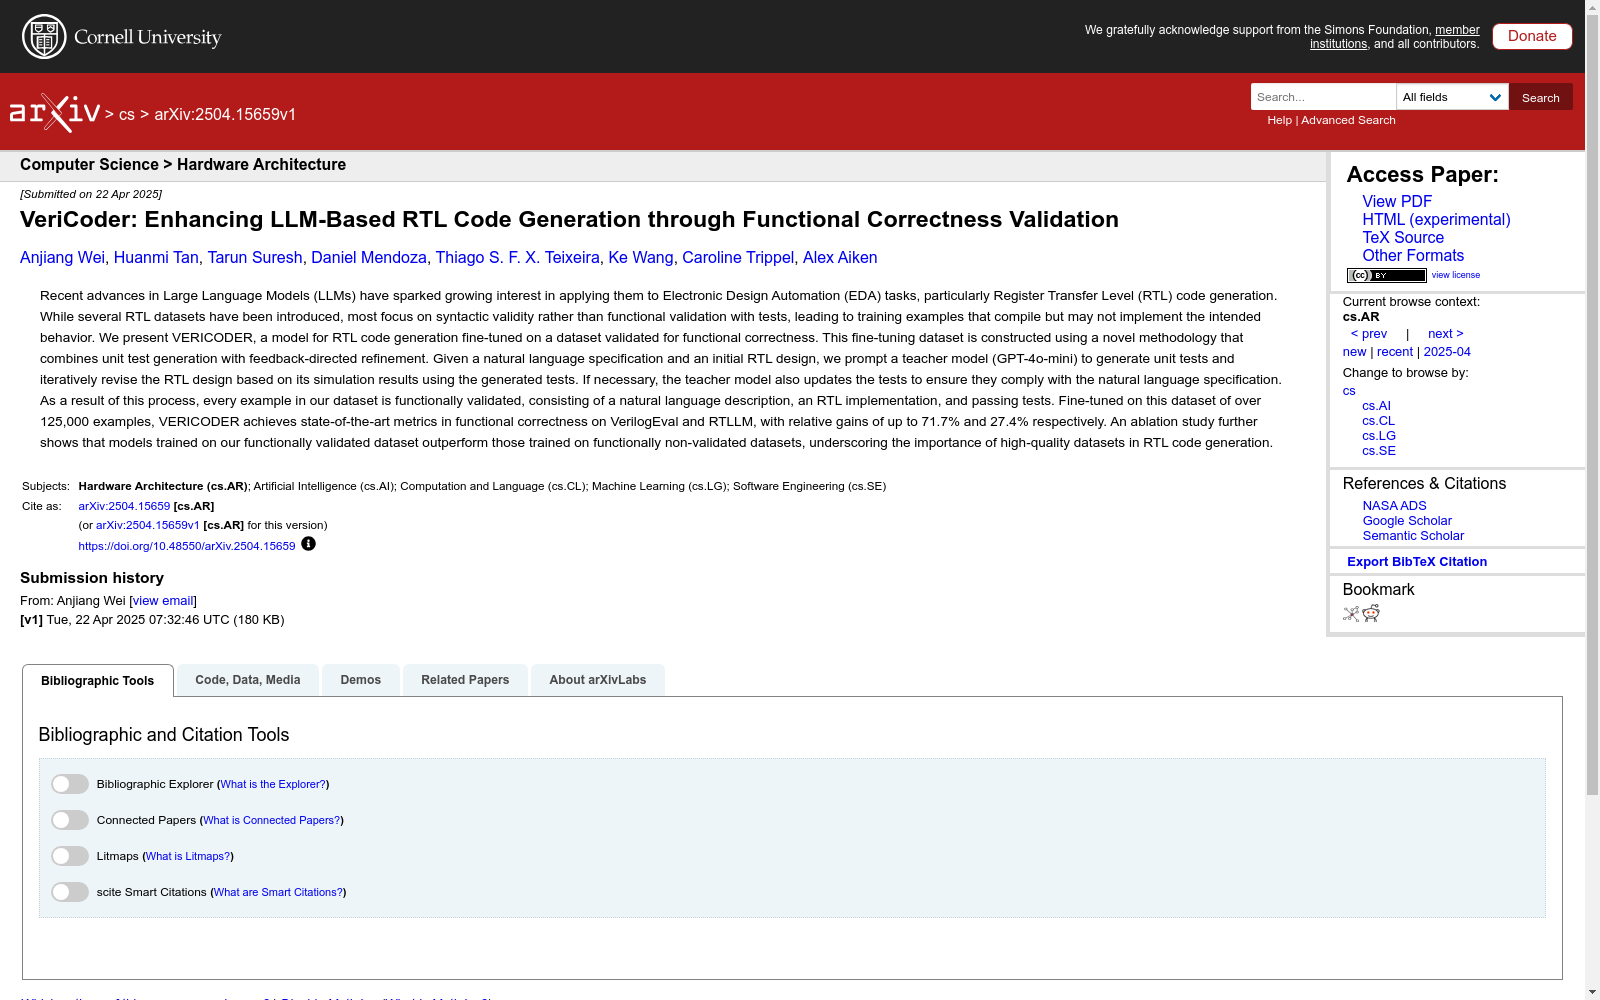
VERICODER fine-tuning dataset是一个包含超过125,777个示例的高质量数据集,每个示例都经过功能正确性验证,由自然语言规范、相应的RTL实现和通过的单元测试组成。该数据集由斯坦福大学的研究团队开发,通过单元测试生成和反馈指导的精炼流程,确保了数据集中的每个设计都能通过功能模拟测试,旨在提高RTL代码生成的功能正确性。
The VERICODER fine-tuning dataset is a high-quality dataset comprising over 125,777 validated examples. Each example has been verified for functional correctness, and is composed of natural language specifications, corresponding RTL implementations, and passing unit tests. Developed by a research team at Stanford University, this dataset employs a refinement workflow guided by unit test generation and feedback to ensure that every design included in the dataset can pass functional simulation tests, with the goal of enhancing the functional correctness of RTL code generation.