moss-va-trajectory-corpus
收藏资源简介:
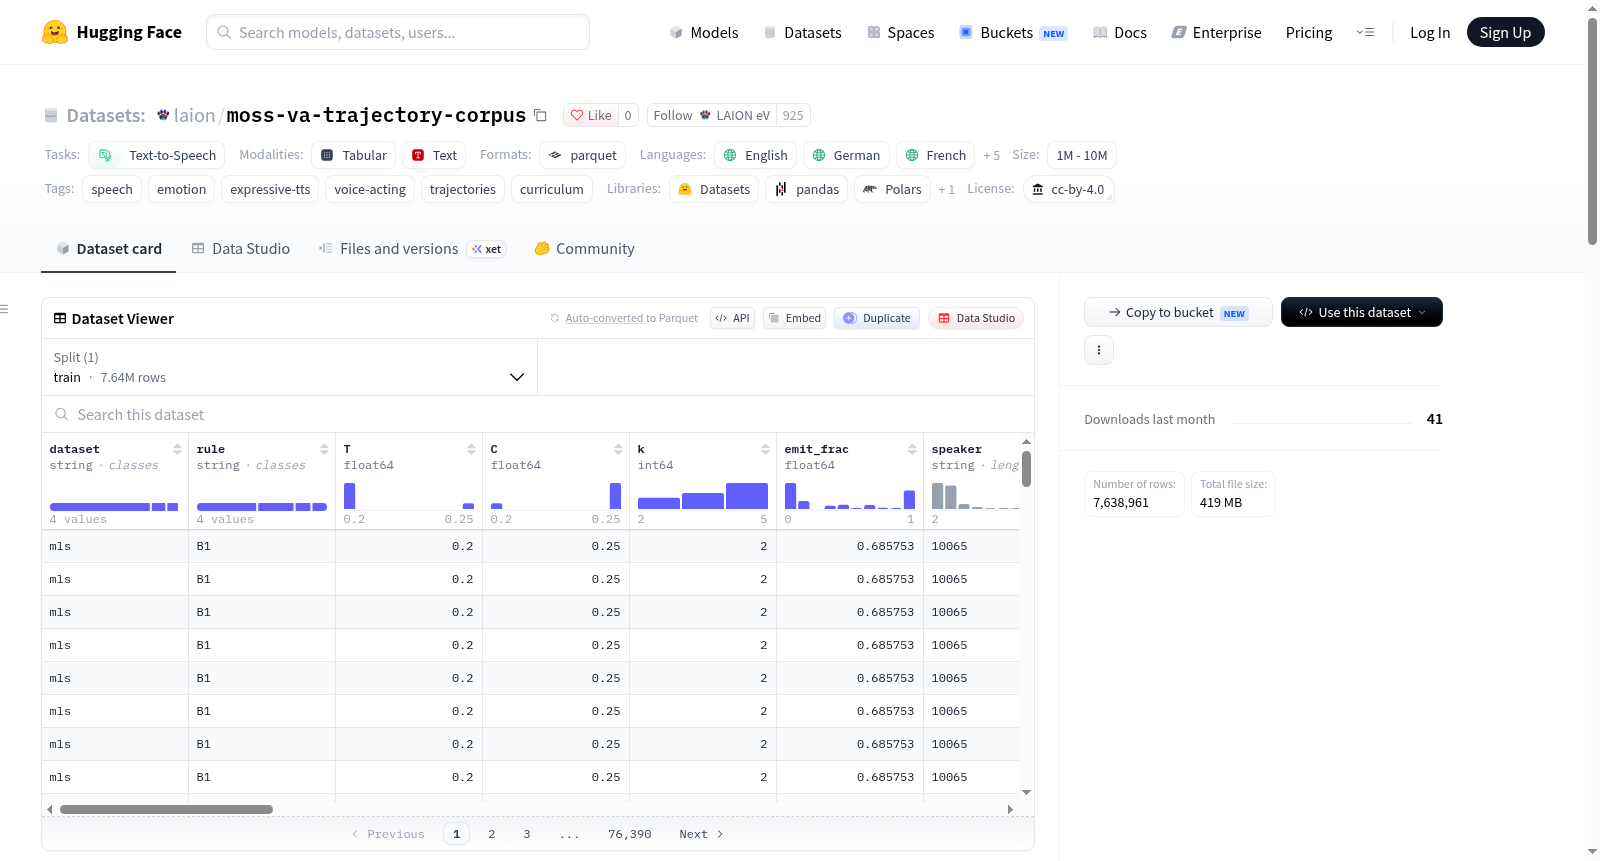
该数据集是 MOSS Voice-Acting 项目的情感轨迹语料库公开子集。它包含 7,638,961 条轨迹规格,覆盖 17,722,101 个不同的源剪辑。每条轨迹是一个有序列表,由同一说话人的多个剪辑组成,共同表示情感或 VoiceNet 维度上的逐步变化(例如从平静到愤怒,或从高到低效价)。数据集不包含音频,每行通过 uid 引用剪辑,并记录每一步在维度上的位置。数据来自四个来源:emolia(5,893,310 行)、kartoffelphon(897,830 行)、eurospeech(729,876 行)和 MLS(117,945 行)。轨迹分为四种类型:单情感单调变化(emotion, B1, 3,545,392 行)、单 VoiceNet 维度单调变化(voicenet, VN1, 2,160,000 行)、代理维度尾部变化(proxy_taillift, PXR, 977,981 行)和双情感反向同时变化(emotion_twosided, AB2, 955,588 行)。平均每条轨迹包含 3.51 个剪辑,总参考音频时长 74,858 小时,82.7% 的轨迹在源录音中连续。字段包括 uids、speaker、dataset、lang、lang_iso、family、rule、dim_a、dim_b、d_a、d_b、step_a、step_b、T、C、k、qmax、cmax、contiguous、total_dur、emit_frac、spk_basis、proxy_map 和 track。该数据集主要用于训练和评估随时间变化的情感或语音维度表达,而非单一话语属性的识别或生成。注意:本数据集是过滤后的公开子集,podcast、evasnippets 和 snippets 子集因隐私原因未包含在内。
This dataset is a public subset of the MOSS Voice-Acting projects emotional trajectory corpus. It contains 7,638,961 trajectory specifications covering 17,722,101 distinct source clips. Each trajectory is an ordered list of multiple clips from the same speaker, together representing gradual changes in emotion or VoiceNet dimensions (e.g., from calm to angry, or from high to low valence). The dataset does not contain audio; each line references clips by uid and records the position along each dimension at each step. Data comes from four sources: emolia (5,893,310 lines), kartoffelphon (897,830 lines), eurospeech (729,876 lines), and MLS (117,945 lines). Trajectories are divided into four types: single emotion monotonic change (emotion, B1, 3,545,392 lines), single VoiceNet dimension monotonic change (voicenet, VN1, 2,160,000 lines), proxy dimension tail lift (proxy_taillift, PXR, 977,981 lines), and two-sided emotion reverse simultaneous change (emotion_twosided, AB2, 955,588 lines). On average, each trajectory contains 3.51 clips, with a total reference audio duration of 74,858 hours, and 82.7% of trajectories are contiguous in the source recording. Fields include uids, speaker, dataset, lang, lang_iso, family, rule, dim_a, dim_b, d_a, d_b, step_a, step_b, T, C, k, qmax, cmax, contiguous, total_dur, emit_frac, spk_basis, proxy_map, and track. This dataset is primarily used for training and evaluating time-varying emotional or vocal dimension expressions, rather than single utterance attribute recognition or generation. Note: This dataset is a filtered public subset; the podcast, evasnippets, and snippets subsets are not included due to privacy reasons.
数据集概述
MOSS Voice-Acting — Emotional Trajectory Corpus(公开子集) 是一个用于语音情感表达建模的文本-语音(TTS)训练数据集,重点关注情感随时间变化的轨迹,而非单一话语的情感属性。
核心信息
- 数据集规模:包含 7,638,961 条轨迹规格,覆盖 17,722,101 个独立源音频片段。
- 内容形式:数据集中不包含任何音频,每行数据通过 UID 引用音频片段,并记录各片段在情感或 VoiceNet 维度上的位置。
- 用途:用于训练和评估模型在时间维度上对情感变化(如从平静逐渐过渡到愤怒)的建模能力。
- 许可协议:CC-BY-4.0。
- 语言:英语、德语、法语、西班牙语、意大利语、葡萄牙语、荷兰语、波兰语。
数据结构
每行数据包含以下关键字段:
| 字段 | 说明 |
|---|---|
uids |
按顺序排列的片段 ID(逗号分隔) |
speaker |
所有片段共用的说话人 |
dataset, lang, lang_iso |
来源、语言及语言代码 |
family, rule |
轨迹构建方式 |
dim_a, dim_b |
所步行的维度(如 emo_Contemplation) |
d_a, d_b |
各维度上的总距离 |
step_a, step_b |
每步距离 |
T, C, k |
单调性阈值、一致性阈值和步数 |
qmax, cmax |
轨迹满足的质量上界 |
contiguous |
片段在源录音中是否相邻 |
total_dur |
总时长(秒) |
emit_frac, spk_basis, proxy_map, track |
选择记录信息 |
数据构成
按来源划分:
| 来源 | 行数 |
|---|---|
| emolia | 5,893,310 |
| kartoffelphon | 897,830 |
| eurospeech | 729,876 |
| mls | 117,945 |
按轨迹类型划分:
| family | 规则 | 行数 | 步行的内容 |
|---|---|---|---|
emotion |
B1 |
3,545,392 | 单一情感头部,单调变化 |
voicenet |
VN1 |
2,160,000 | 单一 VoiceNet 维度 |
proxy_taillift |
PXR |
977,981 | 代理维度及其尾部 |
emotion_twosided |
AB2 |
955,588 | 两种情感同时反向变化 |
统计特征:
- 每条轨迹平均包含 3.51 个片段(2 片段:1,611,017 条;3 片段:2,303,104 条;4 片段:1,974,481 条;5 片段:1,750,359 条)。
- 引用的音频总时长约 74,858 小时。
- 82.7% 的轨迹在源录音中是连续的。
筛选说明
这是一个经过筛选的发布版本。从 podcast、evasnippets 和 snippets 来源生成的轨迹被保留(未公开),因为这些来源的转录文本不属于开放的真实语音发布内容,且轨迹行会明确指出使用了哪些片段。未筛选的完整语料库(10,653,713 行)保持私有。
相关资源
- 基础模型:MOSS TTS 本地 Transformer v2
- 第三轮监督微调模型:SFT3
- 最佳偏好适配器:DPO LoRA p2
- 技术报告:MOSS VA 技术报告