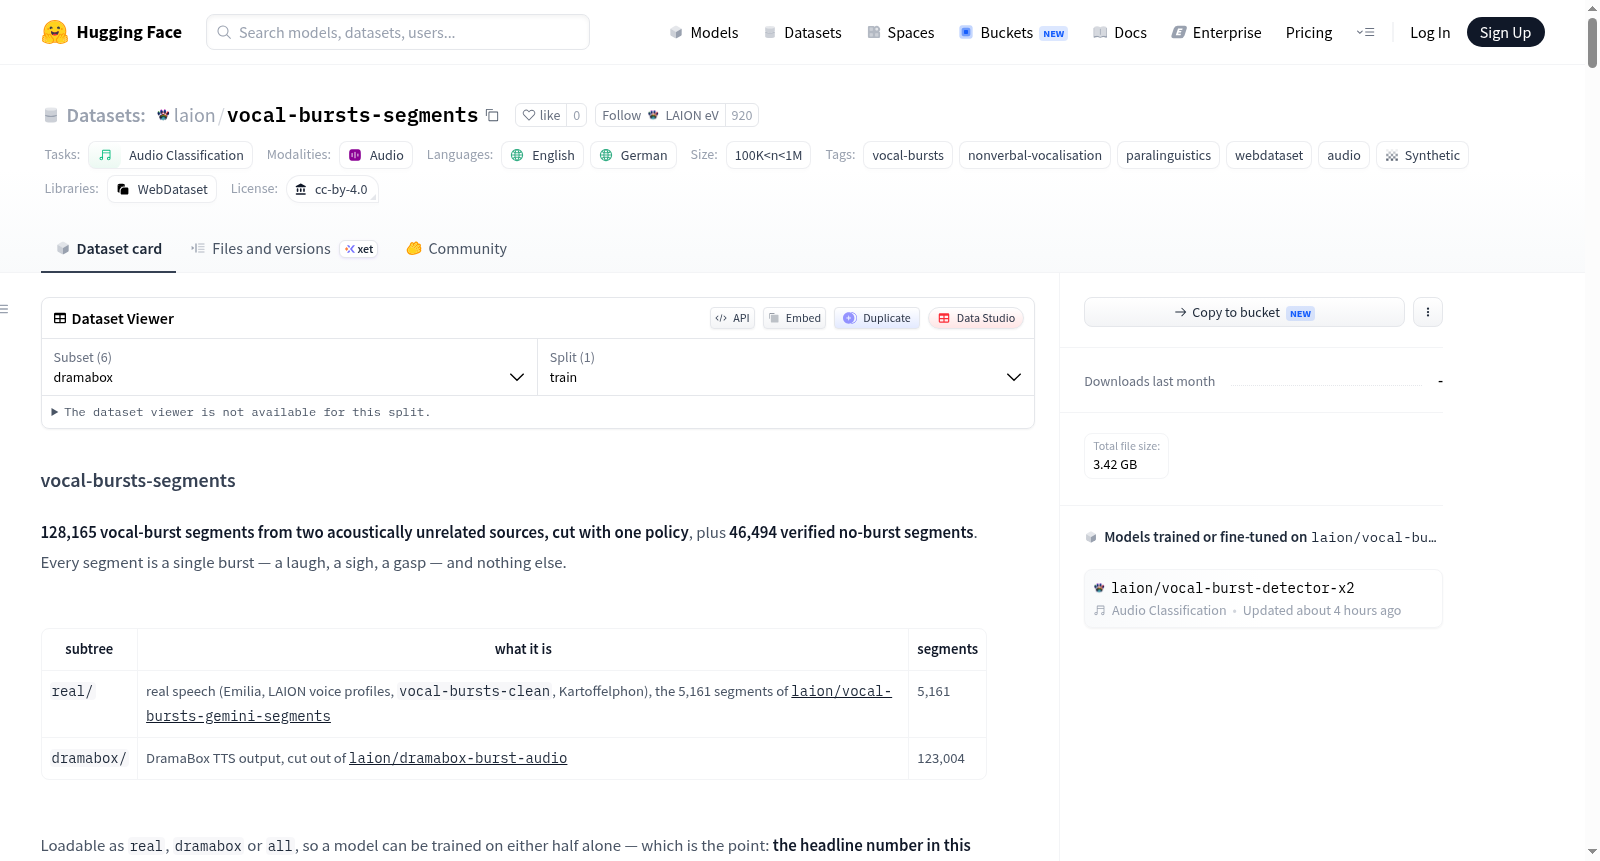
vocal-bursts-segments
收藏资源简介:
vocal-bursts-segments 是一个用于音频分类的数据集,专注于非语言发声(vocal bursts)的识别。数据集包含来自两个声学无关来源的 128,165 个声音爆发片段和 46,494 个验证过的非爆发片段。每个片段代表一个单一的爆发,如笑声、叹息、倒吸一口气、咳嗽、哼唱等。数据来源包括真实语音(来自 Emilia、LAION voice profiles、vocal-bursts-clean、Kartoffelphon 等数据集)和 DramaBox 文本转语音(TTS)输出。所有片段均采用统一的切割策略:在标注跨度基础上左右各扩展 50 毫秒,并去除短于 50 毫秒的片段,同时保留能量收紧窗口作为元数据。标签由 Gemini 模型生成,未经人工验证,因此使用时应谨慎。数据集提供多种配置:all(所有片段)、real(仅真实语音)、dramabox(仅 TTS 生成)、negatives(负样本,包括 speech 和 silence 子类型)、real_negatives 和 dramabox_negatives。负样本通过两个独立检测器(Gemini 标注和专门的爆发检测器)以及声学条件(语音覆盖率和能量阈值)严格筛选,以确保不含爆发。验证结果显示,speech 负样本的污染率约为 4.1%,而 silence 负样本由于模型在低能量输入上的幻觉,污染率无法可靠测量。数据集还提供平衡集(balanced_train.parquet),包含 16 个类别,每类约 1,302 个爆发样本,总爆发和非爆发样本各 20,832 个。跨源评估结果表明,在真实语音和 TTS 之间训练的模型具有可迁移性,但混合训练会降低真实语音上的性能,建议根据需求选择特定配置。该数据集适用于副语言学分类、非语言发声检测、语音情感识别等任务。
vocal-bursts-segments is a dataset for audio classification, focusing on the recognition of vocal bursts (non-linguistic vocalizations). The dataset contains 128,165 vocal burst segments and 46,494 verified non-burst segments from two acoustically unrelated sources. Each segment represents a single burst such as laughter, sigh, gasp, cough, hum, etc. Data sources include real speech (from datasets such as Emilia, LAION voice profiles, vocal-bursts-clean, Kartoffelphon) and DramaBox text-to-speech (TTS) outputs. All segments are cut using a unified strategy: extending 50ms on each side of the annotation span, removing segments shorter than 50ms, and retaining the energy envelope window as metadata. Labels are generated by the Gemini model without human verification, so caution is advised when using. The dataset offers multiple configurations: all (all segments), real (real speech only), dramabox (TTS generated only), negatives (negative samples including speech and silence subtypes), real_negatives and dramabox_negatives. Negative samples are strictly filtered by two independent detectors (Gemini annotations and a dedicated burst detector) and acoustic conditions (speech coverage and energy threshold) to ensure no bursts. Validation results show a contamination rate of about 4.1% for speech negatives, while the contamination rate for silence negatives is unreliable due to model hallucination on low-energy inputs. The dataset also provides a balanced set (balanced_train.parquet) with 16 categories, each containing approximately 1,302 burst samples, totaling 20,832 burst and 20,832 non-burst samples. Cross-source evaluation indicates that models trained on real speech and TTS are transferable, but mixed training degrades performance on real speech; it is recommended to select specific configurations based on needs. The dataset is suitable for tasks such as paralinguistic classification, non-linguistic vocalization detection, and speech emotion recognition.
vocal-bursts-segments 数据集详情
数据集概述
该数据集包含来自两个声学上不相关来源的 128,165 个发声爆发片段(如笑、叹气、喘息等),以及 46,494 个经过验证的无爆发片段。每个片段都是单一爆发,不含其他内容。数据集采用 CC-BY-4.0 许可证,规模在 100K 到 1M 之间,任务类型为音频分类,语言涵盖英语和德语。
数据构成
| 子树 | 内容 | 片段数 |
|---|---|---|
real/ |
真实语音(Emilia、LAION 语音档案、vocal-bursts-clean、Kartoffelphon),包含来自 laion/vocal-bursts-gemini-segments 的 5,161 个片段 | 5,161 |
dramabox/ |
DramaBox TTS 输出(从 laion/dramabox-burst-audio 剪切) | 123,004 |
数据集提供 6 种配置:all、real、dramabox、negatives、real_negatives 和 dramabox_negatives,均可作为 train 分割加载。
关键统计
| 指标 | real | dramabox |
|---|---|---|
| 爆发片段数 | 5,161 | 123,004 |
| 中位片段时长 | 0.76 秒 | 1.37 秒 |
| 平均片段时长 | 0.97 秒 | 1.66 秒 |
| p90 时长 | 1.60 秒 | 2.94 秒 |
| 总音频时长 | 1.39 小时 | 56.77 小时 |
| 不同 top-1 标签数 | 59 | 97 |
| 无爆发片段(语音) | 6,400 | 30,000 |
| 无爆发片段(静音) | 94 | 10,000 |
注意:DramaBox 半集的片段中位时长约为 real 半集的 1.8 倍,这是两半集之间的系统性差异,未被修正。
标签分布
59 个标签同时出现在两半中(如 Deep Breath、Chuckle、Humming、Scream 等),0 个仅存在于 real/,38 个仅存在于 dramabox/(如 Burp、Crying、Giggle 等)。
负面样本设计
负面样本需满足三个条件:
- 与 Gemini 标注的每个片段间隔 ≥ 0.5 秒
- 与 vocalburst-locator v2 和 vocal-burst-detector-v2 发现的每个片段间隔 ≥ 0.5 秒
- 满足语音(≥ 60% 被 Parakeet-TDT 单词覆盖,RMS ≥ 0.15× 片段)或静音(无单词,RMS ≤ 0.10× 片段)条件
负面样本混合比例为 75% 语音 / 25% 静音。注意:静音负面样本的通量率测量反映的是工具本身而非数据——验证显示模型对纯零缓冲区和极低噪声输入 100% 会虚构爆发,且置信度均值 0.88。
平衡集
metadata/balanced_train.parquet 包含:
- 16 个类别(在两半中均至少出现 100 次)
- 每个爆发类别目标 1,302 个
- 爆发行 20,832 个,无爆发行 20,832 个(其中语音 15,624 个、静音 5,208 个)
- 无短缺需补充
跨源实验性能(2×2 设计)
训练数据和测试数据来自不同来源时,平衡准确率约为 6 倍随机水平(随机水平 = 5.9%):
| 训练→测试 | 平衡准确率 | 爆发 vs 无爆发 | 负面语音 | 负面静音 |
|---|---|---|---|---|
| real→real | 43.4% | 97.6% | 96.1% | 70.4% |
| real→dramabox | 34.2% | 92.8% | 95.3% | 83.9% |
| dramabox→real | 34.3% | 94.7% | 95.8% | 26.4% |
| dramabox→dramabox | 50.4% | 97.4% | 97.9% | 82.0% |
| both→real | 38.2% | 96.3% | 96.7% | 28.0% |
| both→dramabox | 51.2% | 97.2% | 98.2% | 79.7% |
关键结论:
- 头部模型可跨源迁移,交叉源单元约为随机水平 6 倍
- 加入 dramabox 半集会降低 real 语音头部性能(both→real 38.2% vs real→real 43.4%),如需最佳 real 语音头部,建议单独使用
real配置 - 静音负面样本不跨源迁移(dramabox→real 仅 26.4%),语音负面样本则可迁移(95-98%),切勿将两种子类型合并为单一负面准确率
编码器对比
使用 VoiceCLAP (3584-d) 替换默认 768-d 提取器,在所有单元上均获胜,且消除了混合两半的惩罚:
| 训练→测试 | FastScorer 768-d | VoiceCLAP 3584-d | Δ |
|---|---|---|---|
| real→real | 43.4% | 45.6% | +2.2 |
| real→dramabox | 34.2% | 40.6% | +6.4 |
| dramabox→real | 34.3% | 35.7% | +1.4 |
| dramabox→dramabox | 50.4% | 56.0% | +5.6 |
| both→real | 38.2% | 44.9% | +6.8 |
| both→dramabox | 51.2% | 57.6% | +6.3 |
重要使用警告
- 无人类人工审核:所有标签均为 gemini-3.8-flash 的自动标注,一致性数字是模型间的而非对真实标注的
- dramabox/ 半集的许可证未评估(LTX-2 社区许可证),下游训练风险自负
- 片段并非作为片段被标注,而是从标注者绘制的完整音频跨度中剪切
- 建议用于标签而非训练定位器