nrl-ai/vn-spell-correction-eval-real
收藏资源简介:
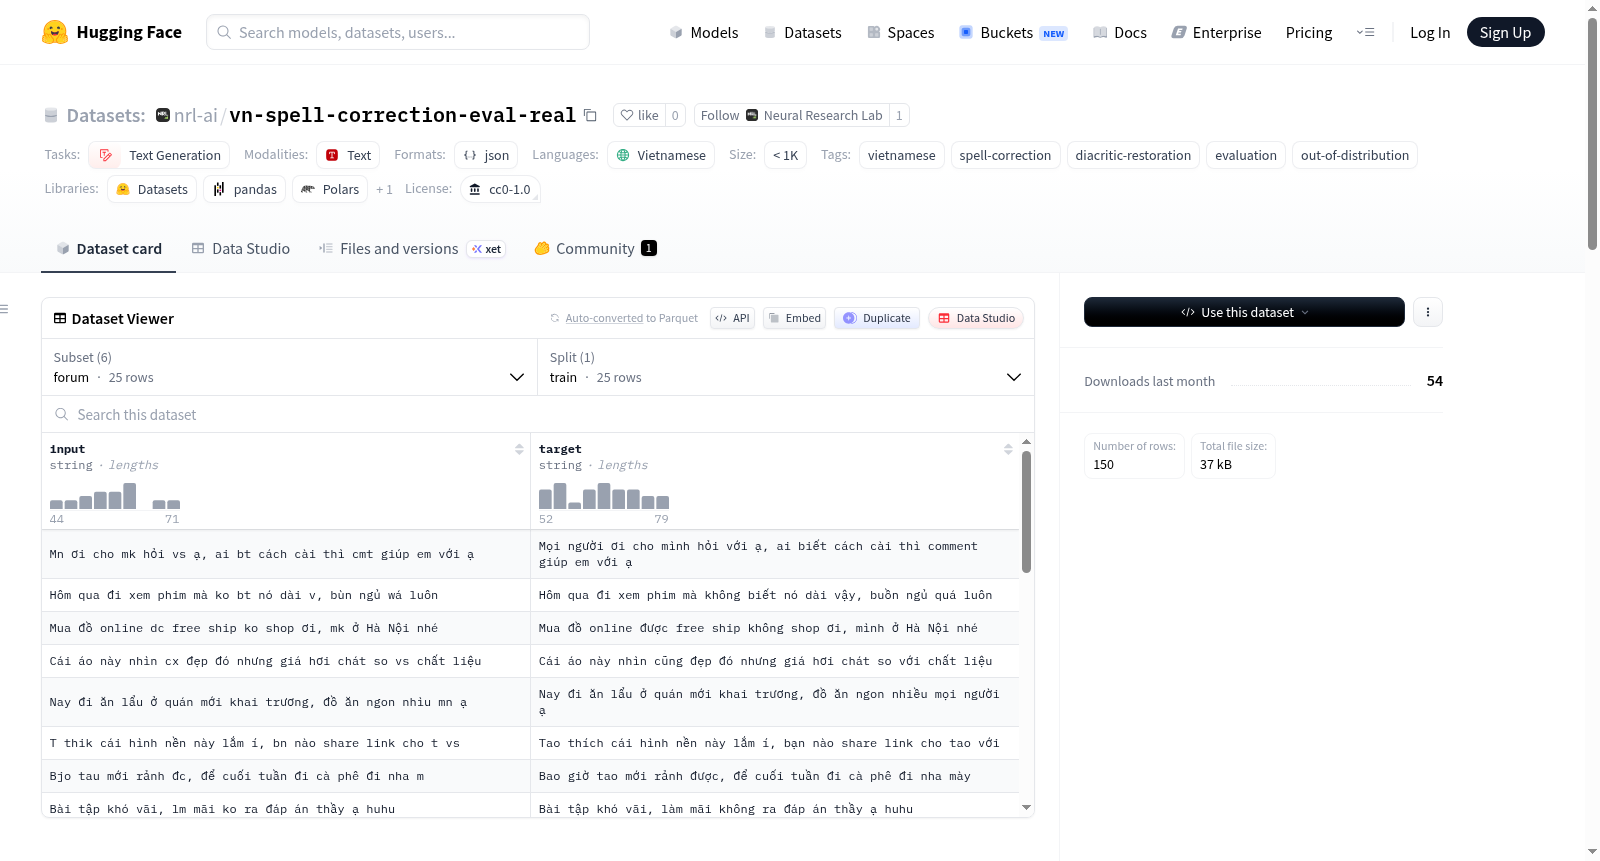
越南语拼写纠正非分布评估数据集(150个句子,6种来源)。该数据集包含手工整理的(有噪声,干净)句子对,噪声模式来自真实的越南语错误来源,而非合成噪声生成器。数据集分为6个配置,分别对应不同的噪声来源和测试目标,包括论坛/社交媒体帖子的缩写、手机输入法的自动纠正错误、真实的Telex/VNI键盘输入错误、OCR引擎输出错误、法律文件中的重音符号缺失以及新闻标题/正文中的重音符号缺失。每个配置包含25个句子,总计150个句子。数据集的设计目的是作为非分布评估的补充,与合成噪声生成的评估数据集区分开来。
Vietnamese spell-correction out-of-distribution evaluation dataset (150 sentences, 6 registers). The dataset contains hand-curated (noisy, clean) pairs whose noise patterns come from real Vietnamese error sources, not from a synthetic noise generator. It is divided into 6 configurations, each corresponding to different noise sources and test objectives, including abbreviations in forum/social-media posts, autocorrect mishaps in phone-typing, real Telex/VNI keystroke artefacts, OCR engine output errors, diacritic-stripped legal documents, and diacritic-stripped news headlines/body. Each configuration contains 25 sentences, totaling 150 sentences. The dataset is designed as the out-of-distribution complement to the in-distribution synthetic evaluation dataset.