nrl-ai/vn-spell-correction-eval
收藏资源简介:
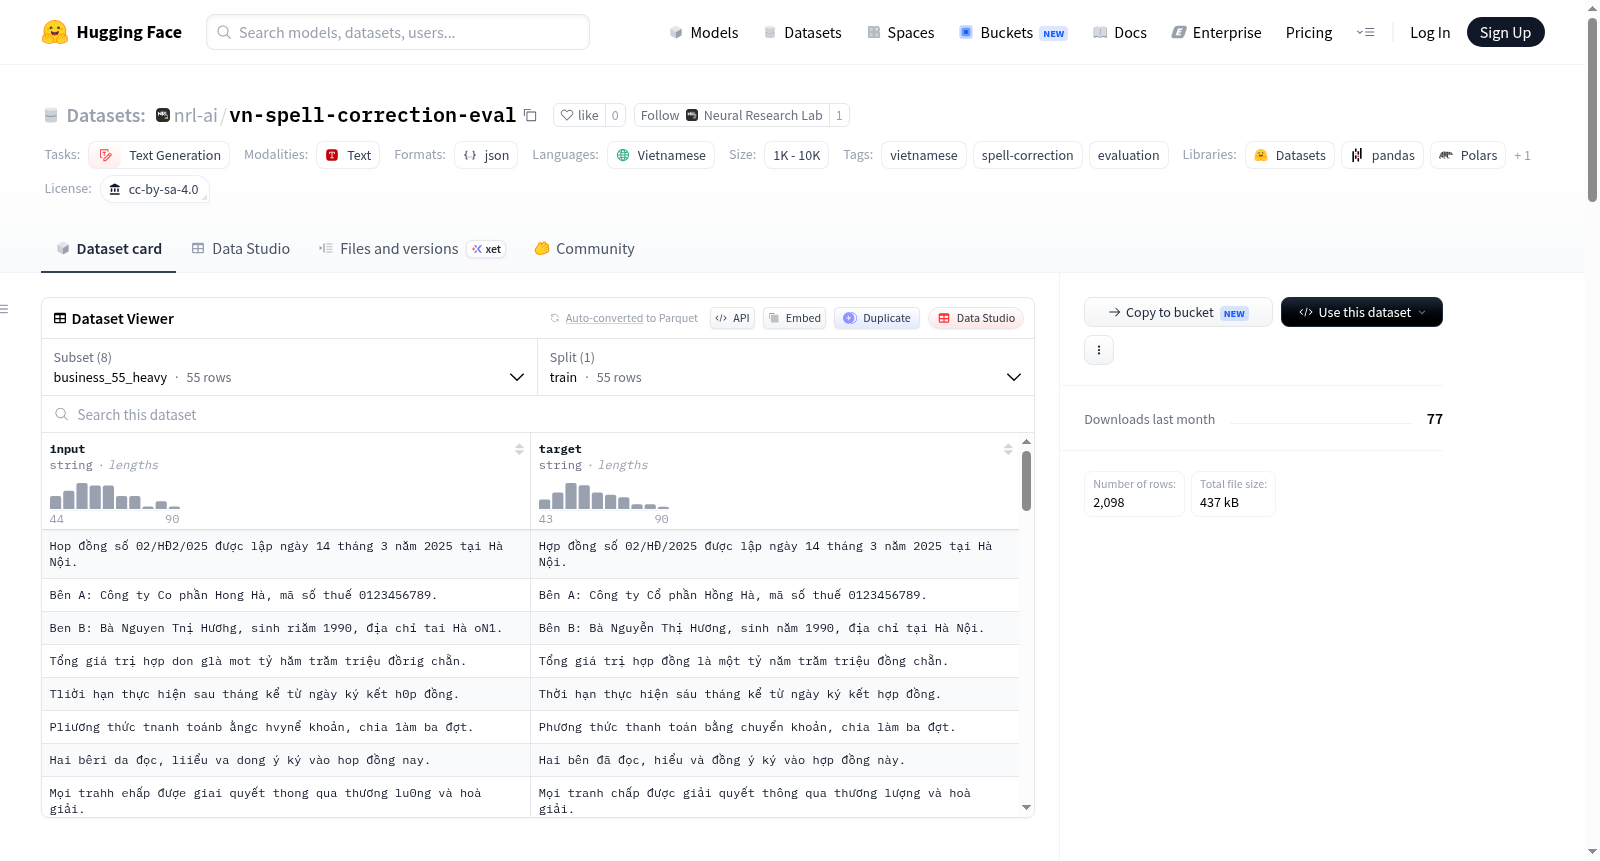
越南语拼写校正评估网格:4个来源语域 × 2种噪声级别 = 8个分割,总计2,098对(含噪声,干净)句子。每对句子格式为{input: <noisy>, target: <clean>}, 双方均经过NFC标准化处理。干净的目标句子与nrl-ai/vn-diacritic-eval数据集中的目标句子相同,因为拼写校正是重音恢复的严格超集,故复用相同的语域平衡语料库。噪声级别分为轻量级(约5%字符级编辑距离,模拟键盘输入时的少量口音错误和偶尔的误按)和重量级(约15-20%编辑距离,模拟中等质量扫描的OCR输出,含重音丢失和字符混淆)。数据集包含商业、正式、对话和文学四种语域,每种语域下分轻量和重量级噪声,具体句子数量及来源许可证详见README中的表格。数据集构建脚本位于nom-vn仓库,具有确定性(固定种子)。组合数据集采用CC-BY-SA-4.0许可证(最严格的组成源许可证),部分分割采用CC0或公共领域许可证。
Vietnamese spell-correction evaluation grid: 4 source registers × 2 noise levels = 8 splits, 2,098 (noisy, clean) sentence pairs total. Each pair is formatted as {input: <noisy>, target: <clean>}, with both sides NFC-normalized. The clean target sentences are the same as those in the nrl-ai/vn-diacritic-eval dataset, as spell correction is a strict superset of diacritic restoration, hence reusing the same registers-balanced corpus. Noise levels are categorized into light (~5% char-level edit distance, simulating a few accent slips and occasional fat-finger errors during typing) and heavy (~15-20% edit distance, modeling OCR output from mid-quality scans with diacritic drops and character confusions). The dataset covers four registers (business, formal, conversational, literary), each with light and heavy noise levels, with detailed sentence counts and source licenses provided in the README table. The dataset build script is located in the nom-vn repository and is deterministic (fixed seeds). The combined dataset is licensed under CC-BY-SA-4.0 (the most restrictive constituent source license), with some splits under CC0 or public domain licenses.