
Spider
收藏资源简介:
Spider是由耶鲁大学计算机科学系创建的大规模、复杂且跨领域的语义解析和文本到SQL的数据集。该数据集包含10,181个问题和5,693个独特的复杂SQL查询,涉及200个数据库,覆盖138个不同领域。数据集由11名大学生耗时1,000小时标注完成。Spider数据集旨在解决模型在面对新SQL查询和新数据库模式时的泛化能力问题,特别强调了模型需要理解自然语言问题以及数据库模式中表和列之间的关系。该数据集的应用领域广泛,主要用于测试和提升模型在复杂查询和跨领域数据库处理上的性能。
Spider is a large-scale, complex, cross-domain semantic parsing and text-to-SQL dataset created by the Department of Computer Science at Yale University. This dataset contains 10,181 questions and 5,693 unique complex SQL queries, covering 200 databases and spanning 138 distinct domains. It was annotated by 11 undergraduate students over 1,000 working hours. The Spider dataset aims to address the generalization capability challenges of models when encountering novel SQL queries and new database schemas, with particular emphasis on requiring models to comprehend natural language questions as well as the relationships between tables and columns within database schemas. This dataset has a wide range of applications, primarily used for testing and improving the performance of models in complex query processing and cross-domain database tasks.
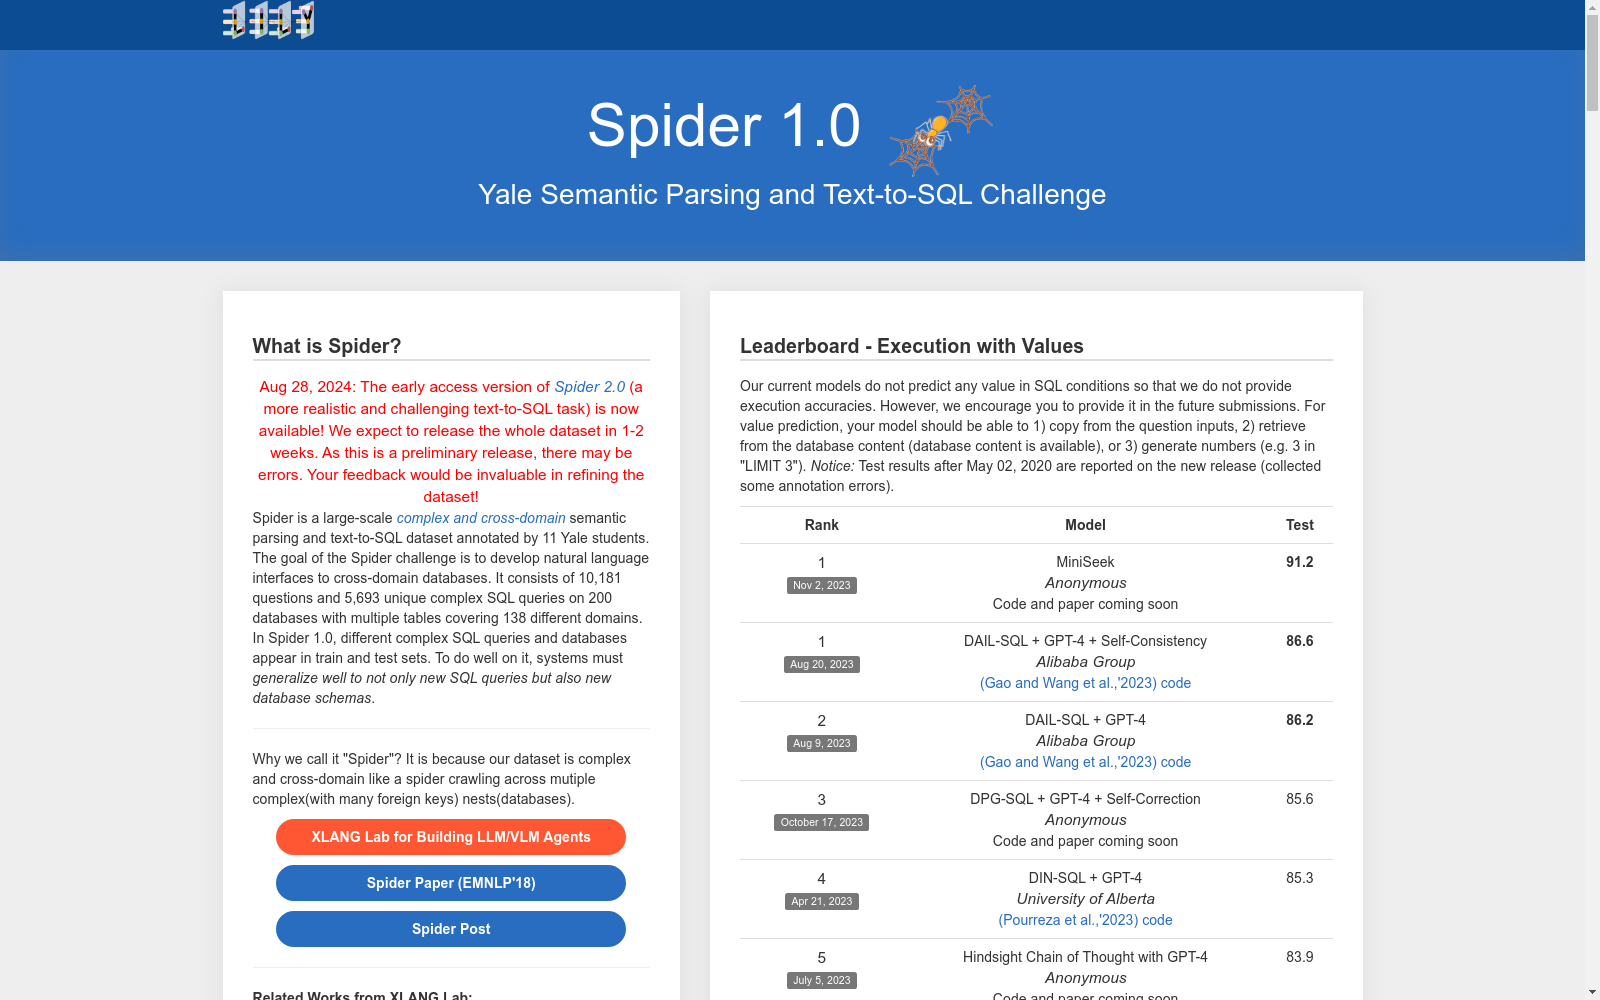
- Spider数据集首次发表,由Yu等人提出,旨在评估自然语言到SQL查询的转换能力。
- Spider数据集首次应用于自然语言处理领域的研究,特别是在语义解析和数据库查询生成任务中。
- Spider数据集的扩展版本发布,增加了更多的数据库和查询类型,以提升数据集的多样性和挑战性。
- Spider数据集在多个国际会议和竞赛中被广泛使用,成为评估自然语言到SQL转换模型性能的标准数据集之一。
- 1Spider: A Large-Scale Human-Labeled Dataset for Complex and Cross-Domain Semantic Parsing and Text-to-SQL TaskUniversity of Washington, AI2, Google Research, McGill University · 2018年
- 2RAT-SQL: Relation-Aware Schema Encoding and Linking for Text-to-SQL ParsersUniversity of Washington, AI2 · 2019年
- 3Global Reasoning over Database Structures for Text-to-SQL ParsingUniversity of Washington, AI2 · 2020年
- 4Towards Complex Text-to-SQL in Cross-Domain Database with Intermediate RepresentationUniversity of Washington, AI2 · 2019年
- 5Improving Text-to-SQL Evaluation MethodologyUniversity of Washington, AI2 · 2018年


