PAD3-dataset-w-caption
收藏资源简介:
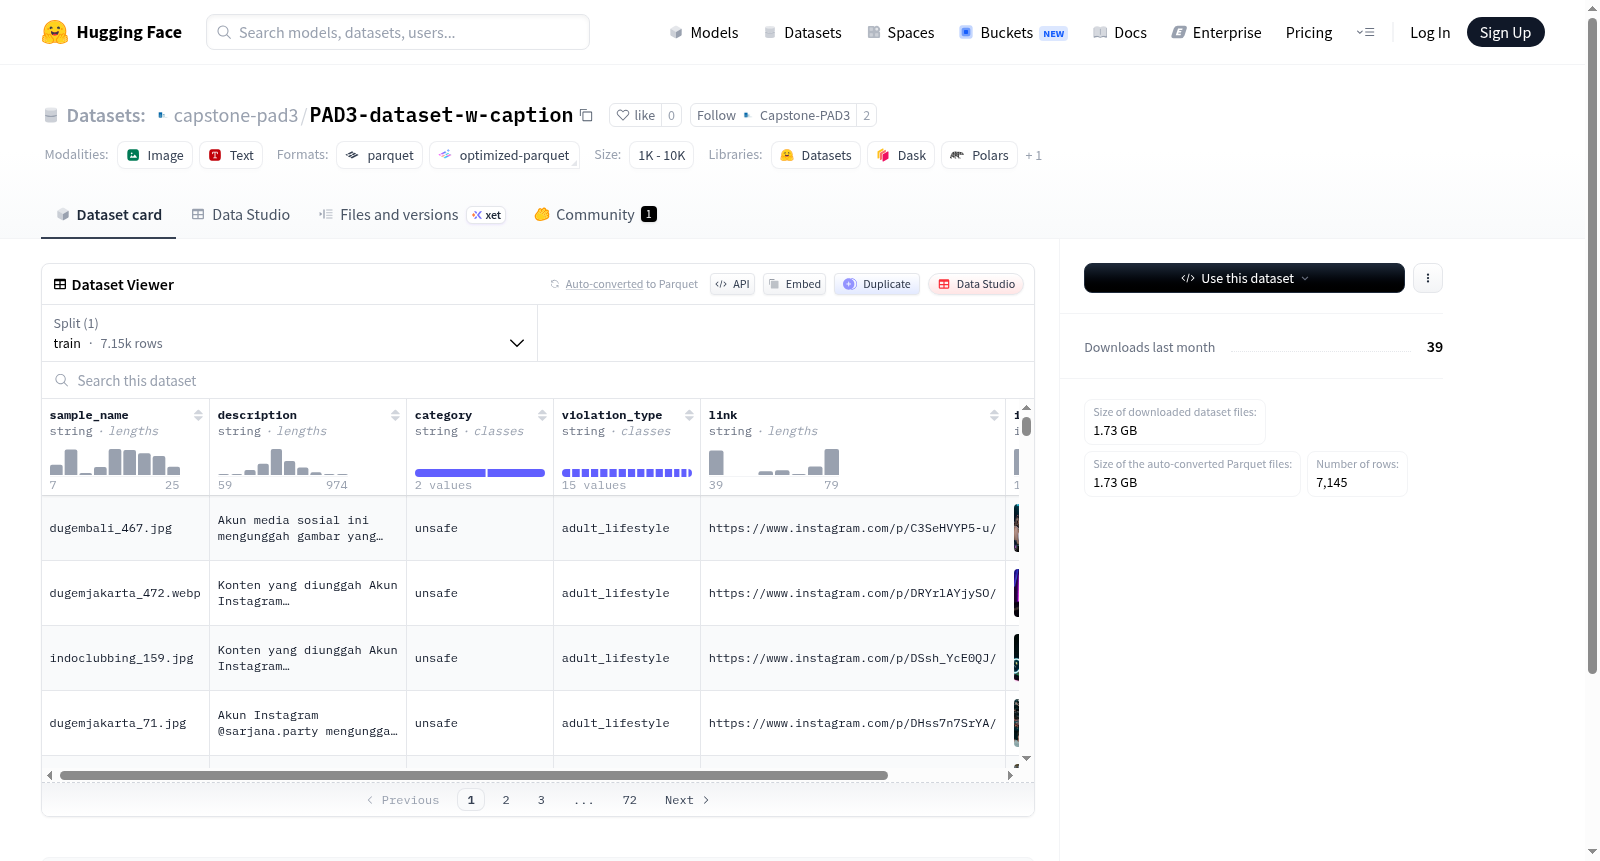
该数据集是一个多模态数据集,包含7,145个训练样本,数据规模约1.73GB。数据集包含文本和图像特征,具体字段包括:样本名称(sample_name)、描述(description)、类别(category)、违规类型(violation_type)、链接(link)和图像(image)。其中图像字段存储为image类型,其他文本字段均为string类型。数据集采用单一训练集划分(train split),原始下载文件大小约1.85GB。该数据结构适用于多模态分类、违规内容检测等计算机视觉与自然语言处理结合的任务。
This is a multimodal dataset containing 7,145 training samples with a total data size of approximately 1.73 GB. It includes text and image features, with specific fields including sample_name, description, category, violation_type, link, and image. The image field is stored as the image data type, while all other text fields are of string type. The dataset adopts a single train split, and the size of the original downloaded file is approximately 1.85 GB. This data structure is suitable for tasks combining computer vision and natural language processing such as multimodal classification and violation content detection.
PAD3-dataset-w-caption 数据集概述
数据集基本信息
- 数据集名称:PAD3-dataset-w-caption
- 存储平台:Hugging Face Datasets
- 详情页面地址:https://huggingface.co/datasets/capstone-pad3/PAD3-dataset-w-caption
数据集结构与内容
数据特征(Features)
数据集包含以下6个字段:
- sample_name:字符串类型,样本名称。
- description:字符串类型,描述信息。
- category:字符串类型,类别信息。
- violation_type:字符串类型,违规类型。
- link:字符串类型,链接信息。
- image:图像类型,图像数据。
数据划分(Splits)
- 训练集(train):
- 样本数量:7,145 个示例
- 数据集大小:1,728,251,712 字节(约1.73 GB)
- 下载大小:1,845,915,109 字节(约1.85 GB)
数据集配置
- 默认配置(default):
- 数据文件路径:
data/train-* - 对应划分:训练集(train)
- 数据文件路径:
数据获取信息
- 下载大小:1,845,915,109 字节(约1.85 GB)
- 数据集存储大小:1,728,251,712 字节(约1.73 GB)