seasoned-advice-dataset
收藏资源简介:
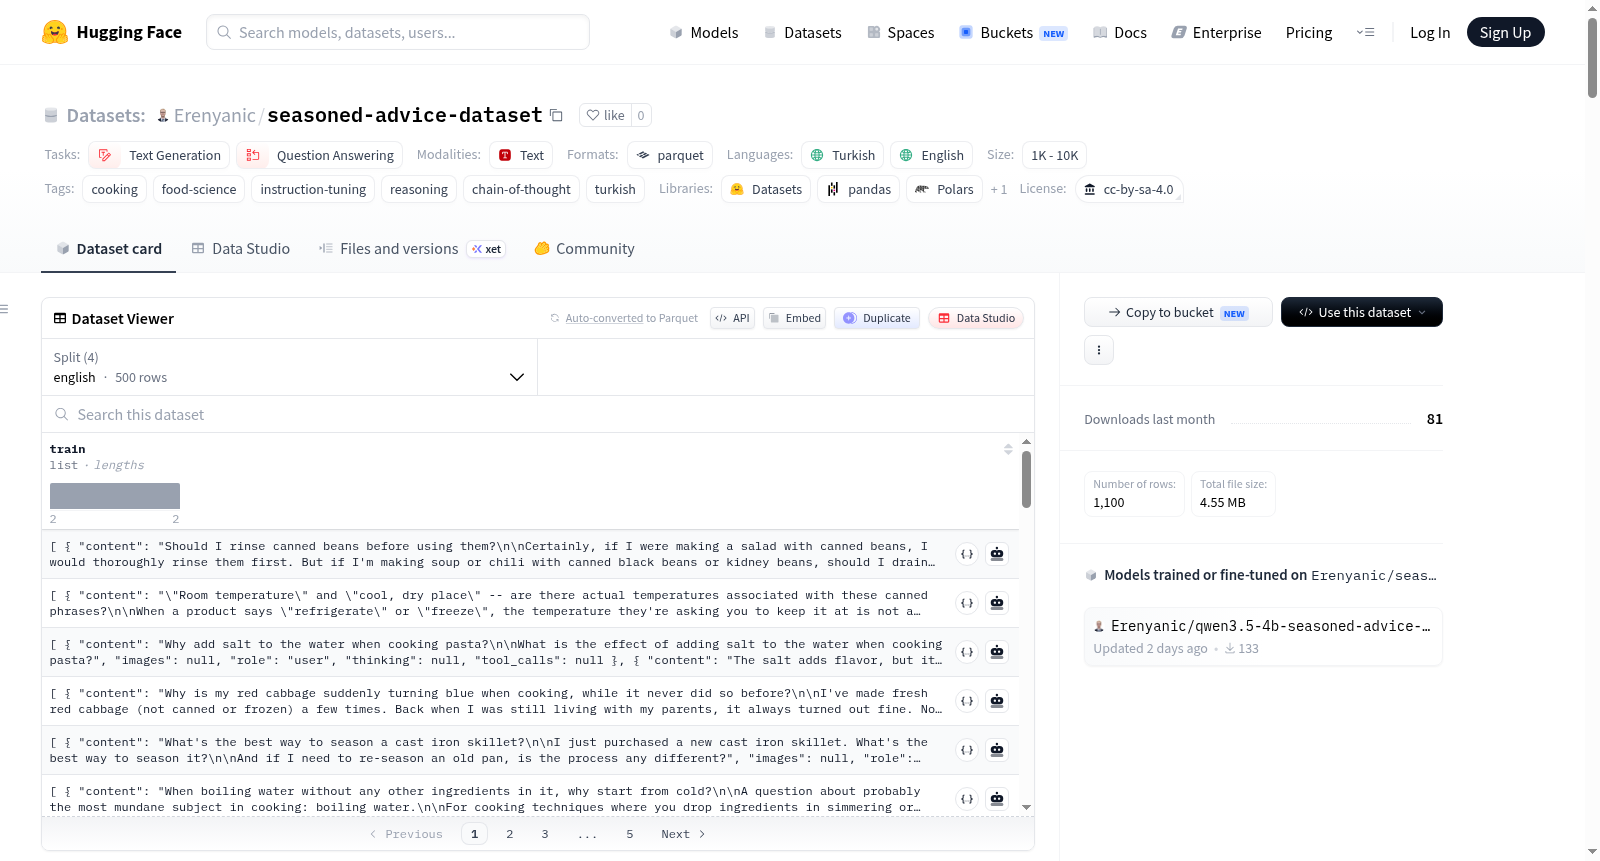
Seasoned Advice数据集是一个专注于烹饪和食品科学领域的双语(土耳其语/英语)指令微调数据集,包含500个对话,数据来源于Stack Exchange旗下Seasoned Advice网站的真实人类问答对,所有内容均为人类撰写,非模型生成。每个对话遵循标准的双轮次消息格式(用户提问,助理回答),并特别为每个助理回答配备了独立的“thinking”字段,用于存放引导至最终答案的推理轨迹,这使得该数据集非常适合用于训练或评估能够展示中间推理过程的模型。数据集包含四个分割:两个并行训练分割(english和turkish,各500个样本,内容一一对应)和两个独立构建的保留测试分割(test_english和test_turkish,各50个样本)。测试集在构建时确保了与训练集零重叠,且其参考答案不包含推理轨迹,专为评估设计。数据格式采用通用的对话(消息列表)格式,包含固定的五个键:role(角色)、content(面向用户的文本内容)、thinking(推理轨迹)、images和tool_calls(后两者始终为null)。这种格式与OpenAI风格的聊天API及主流微调框架兼容。该数据集的主要应用场景包括:1) 土耳其语指令微调,弥补该语言在开源指令数据中的不足;2) 推理轨迹训练,为模型提供答案背后的思维过程示例;3) 翻译评估与跨语言一致性研究,得益于其精确的平行语料。数据集的构建经过精心设计:首先从Seasoned Advice API按评分抓取高质量问答对,经过长度和内容筛选后,构建为对话格式。随后,使用deepseek-v4-pro模型为英语对话生成推理轨迹,并基于包含烹饪术语词汇表的系统提示,将整个英语分割(包括问题、答案和推理轨迹)翻译为土耳其语,以确保术语一致性和分割的平行性。构建过程实施了严格的质量控制,包括过滤模型身份泄漏、检测推理轨迹对答案的过度复制(约8.8%的轨迹因此被重新生成)以及验证翻译的结构完整性。数据集的所有文本内容(英语问答)均源自Seasoned Advice社区用户,根据CC BY-SA 4.0许可发布。推理轨迹和土耳其语翻译作为衍生作品,同样遵循CC BY-SA 4.0许可。每个示例的详细归属信息(问题链接、答案链接、作者信息)保存在单独的源数据文件中。数据集的主要局限性在于:推理轨迹是对已知答案的逆向重建,而非原始作者的实时思考记录;土耳其语分割为机器翻译,未经过全面的人工后编辑;内容范围局限于特定在线社区的烹饪知识与共识,并非权威的食品科学指导。
The Seasoned Advice dataset is a bilingual (Turkish/English) instruction-tuning dataset focused on the cooking and food science domain. It contains 500 conversations, sourced from real human Q&A pairs on the Seasoned Advice website under Stack Exchange, with all content human-written and not model-generated. Each conversation follows a standard two-turn message format (user question, assistant answer), and features a separate thinking field for each assistant answer, which stores the reasoning trace leading to the final answer, making this dataset particularly suitable for training or evaluating models capable of demonstrating intermediate reasoning processes. The dataset includes four splits: two parallel training splits (english and turkish, each with 500 samples, content-aligned one-to-one) and two independently constructed held-out test splits (test_english and test_turkish, each with 50 samples). The test sets are built with zero overlap with the training set, and their reference answers do not include reasoning traces, designed specifically for evaluation. The data format adopts a common conversation (list of messages) format with five fixed keys: role (role), content (user-facing text content), thinking (reasoning trace), images, and tool_calls (the latter two are always null). This format is compatible with OpenAI-style chat APIs and mainstream fine-tuning frameworks. The main application scenarios of the dataset include: 1) Turkish instruction-tuning, addressing the scarcity of open-source instruction data in this language; 2) reasoning trace training, providing models with examples of thought processes behind answers; 3) translation evaluation and cross-lingual consistency research, benefiting from its precise parallel corpus. The datasets construction is meticulously designed: high-quality Q&A pairs are first scraped from the Seasoned Advice API based on ratings, filtered for length and content, and formatted into conversations. Then, reasoning traces are generated for English conversations using the deepseek-v4-pro model, and the entire English split (including questions, answers, and reasoning traces) is translated into Turkish based on a system prompt containing a glossary of cooking terms to ensure terminology consistency and split parallelism. The construction process implements rigorous quality controls, including filtering for model identity leakage, detecting excessive copying of answers in reasoning traces (approximately 8.8% of traces were regenerated as a result), and verifying the structural integrity of translations. All textual content (English Q&A) in the dataset originates from Seasoned Advice community users and is released under the CC BY-SA 4.0 license. The reasoning traces and Turkish translations, as derivative works, also follow the CC BY-SA 4.0 license. Detailed attribution information for each example (question link, answer link, author details) is stored in a separate source data file. The main limitations of the dataset are: the reasoning traces are reverse-engineered from known answers, not real-time thought records of the original authors; the Turkish split is machine-translated and not comprehensively post-edited by humans; and the content scope is limited to the culinary knowledge and consensus of a specific online community, not authoritative food science guidance.
- 数据集名称:Seasoned Advice Dataset
- 语言:土耳其语、英语
- 许可证:CC BY-SA 4.0
- 任务类别:文本生成、问答
- 标签:烹饪、食品科学、指令微调、推理、思维链、土耳其语
- 样本规模:n < 1K
数据集概述
该数据集是一个双语(土耳其语/英语)指令微调数据集,包含 500 段对话,内容源自 Stack Exchange 旗下烹饪问答社区 Seasoned Advice 的真实人类问答对。所有问答内容均通过 Stack Exchange API 收集,非模型生成。每条助手的回复中还包含一个专门的 thinking 字段,记录推理过程,适用于训练或评估具备中间推理能力的模型。
数据集划分
| 划分 | 描述 | 样本数 |
|---|---|---|
english |
英语训练集 | 500 |
turkish |
土耳其语训练集(与英语集平行,第 n 行对应同一段对话) | 500 |
test_english |
英语基准测试集(构建于训练集之后,确保无重叠) | 50 |
test_turkish |
土耳其语基准测试集(与 test_english 平行) | 50 |
- 对话轮次:2 轮(一条用户消息,一条助手消息)
- 领域:烹饪、厨房技巧、食品安全、食品科学
- 许可证:CC BY-SA 4.0
数据格式
每条样本采用对话(或“消息”)格式,即包含 role 和 content 的消息对象列表。此外提供三个可选字段:thinking(助手的推理过程)、images(图像,此数据集中始终为 null)、tool_calls(工具调用,此数据集中始终为 null)。
示例(土耳其语): json [ { "content": "Makarna suyuna neden tuz eklenir?", "images": null, "role": "user", "thinking": null, "tool_calls": null }, { "content": "Tuz lezzet katar, ancak aynı zamanda ...", "images": null, "role": "assistant", "thinking": "Kullanıcı makarna suyuna tuz eklemenin etkisini soruyor ...", "tool_calls": null } ]
加载方式
python from datasets import load_dataset ds = load_dataset("Erenyanic/seasoned-advice-dataset") ds["turkish"][0]["train"] # 返回两个消息字典的列表
数据结构
python DatasetDict({ turkish: Dataset({features: [train], num_rows: 500}) english: Dataset({features: [train], num_rows: 500}) })
{train: List({ content: Value(string), images: Value(null), role: Value(string), thinking: Value(string), tool_calls: Value(null), })}
构建流程
| 阶段 | 脚本 | 输出 |
|---|---|---|
| 1. 爬取英语问答对 | scripts/fetch_stackexchange.py |
data/raw_qa.jsonl、data/sources.jsonl |
| 2. 转换为标准格式 | scripts/build_conversations.py |
data/english.jsonl |
| 3. 生成英语推理过程 | scripts/generate_thinking.py |
填充 data/english.jsonl 中的 thinking 字段 |
| 4. 翻译所有字段 | scripts/translate.py |
data/turkish.jsonl |
| 5. 打包为 Parquet 格式 | scripts/package_dataset.py |
{data,benchmark/data}/*-*.parquet |
- 推理生成:先在英语中生成推理过程,再与问答内容一同翻译。
- API 成本:总耗时约 1,299 次 API 请求,花费 3.26 美元,共消耗 5,957,638 个 token。
- 可恢复执行:各脚本支持断点续传,中断后可继续运行。
数据质量控制
- 推理过程筛选:从 API 返回的
content字段(模型书写的推理过程)中提取,而非reasoning_content(模型内部关于如何书写推理的元评论)。 - 身份泄漏过滤:检测推理过程中是否出现“as an AI”、“language model”等模型身份术语,阻止未通过检测的合并。
- 答案污染检测:检测推理过程是否包含与原始答案高度重复的内容(阈值 100 字符),8.8% 的推理过程被标记并重新生成。
- 翻译结构检查:比较源语言与翻译中 Markdown 标记数量(标题、列表项、代码围栏、链接),对差异发出警告。
来源与归属
| 组成部分 | 来源 |
|---|---|
| 英语问题文本 | 人类撰写,爬取自 Seasoned Advice |
| 英语答案文本 | 人类撰写,爬取自 Seasoned Advice |
| 英语推理过程 | 由 deepseek-v4-pro 基于问答对生成 |
| 土耳其语所有字段 | 由 deepseek-v4-pro 翻译英语内容得到 |
- 来源内容来自 Stack Exchange 的 Seasoned Advice,采用 CC BY-SA 4.0 许可。
- 归属信息保存在
data/sources.jsonl文件中,每条记录包含问题 URL、答案 URL、答案作者姓名和作者主页链接。 - 本数据集同样以 CC BY-SA 4.0 许可发布。
注意事项
- 推理过程是重构生成,并非原作者的真实思维过程。
- 土耳其语部分为机器翻译,未经人工全面校对。
- 领域和语言风格局限于一个英语母语的烹饪社区。
- 答案反映社区共识,非同行评审,食品安全相关内容不应视为权威。