Soofi-Think-SFT-10B-multilingual
收藏资源简介:
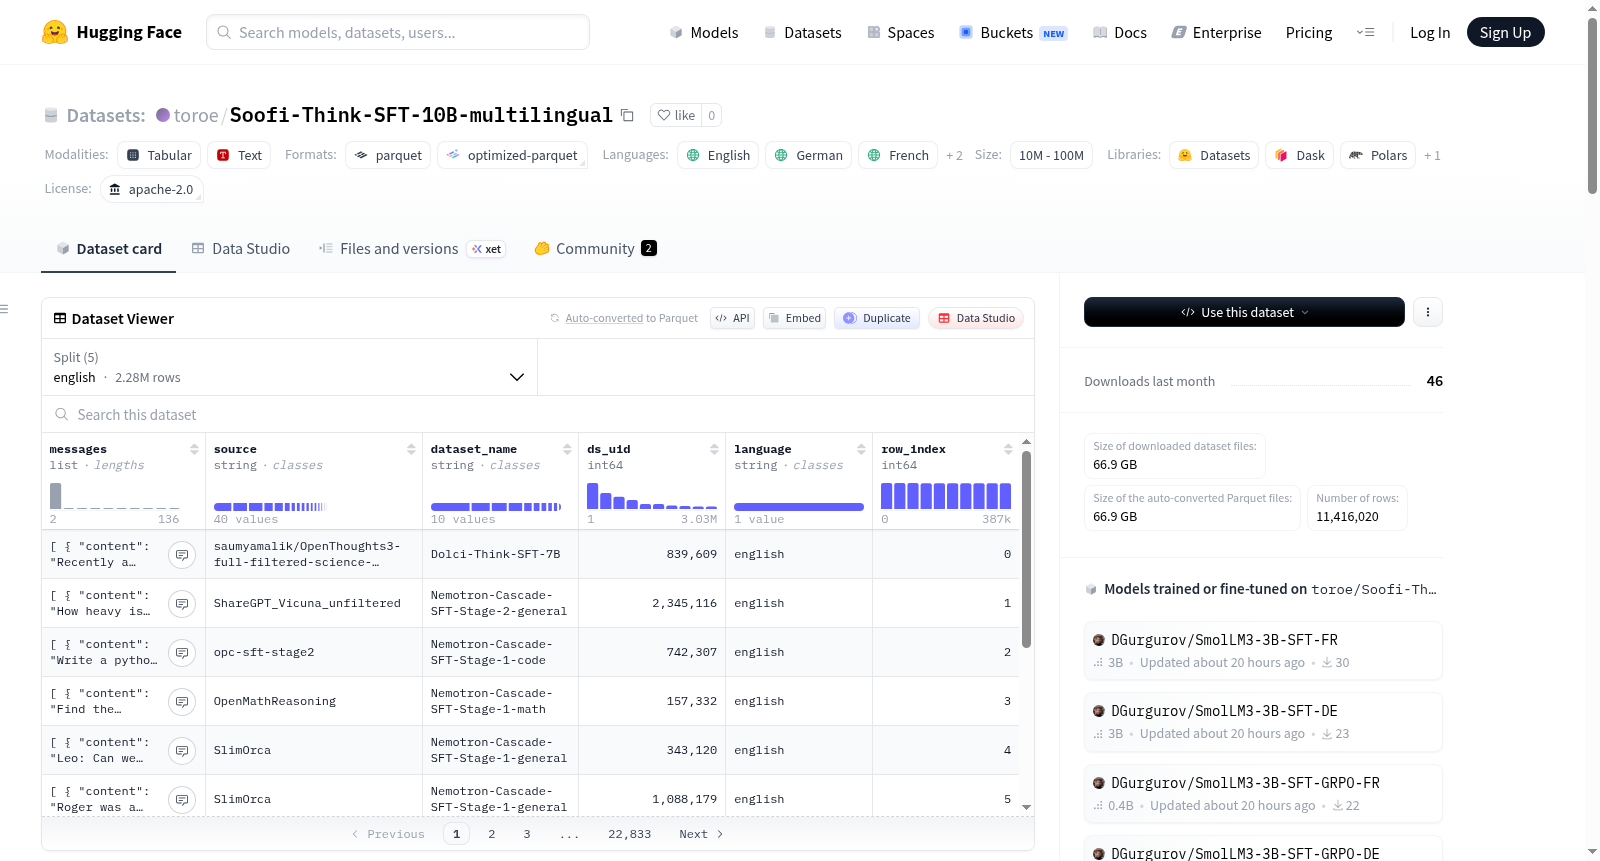
ReasonXL是一个大规模多语言推理语料库,涵盖5种语言(英语、德语、法语、西班牙语、意大利语),总计约440亿token。该数据集旨在支持带有跨领域思维链的多语言推理模型的监督微调。 数据内容包含从10个现有推理数据集中筛选的英语样本,经过质量标注后使用Qwen3-32B模型翻译成其他四种欧洲语言。每个样本包含三个独立翻译的组件:用户输入、思维链(用<think>标签标记)和最终输出。翻译过程严格保留技术术语、数学符号和推理结构。 数据集包含2,282,204个样本,平均每个英语样本总长度4,023 token(输入424 token,输出3,599 token)。特征字段包括消息内容(content)、角色(role)、数据来源(source)、数据集名称(dataset_name)等。数据来源于6个现有推理数据集,包括Cascade-SFT、Dolci-Think等。 该数据集采用Apache-2.0许可证,适用于多语言推理模型训练、思维链研究等场景。
ReasonXL is a large-scale multilingual reasoning corpus covering five languages: English, German, French, Spanish, and Italian, with a total of approximately 44 billion tokens. This corpus is intended to support supervised fine-tuning of multilingual reasoning models with cross-domain chain-of-thought capabilities. The dataset comprises English samples filtered from 10 existing reasoning datasets, which are subsequently translated into the other four European languages using the Qwen3-32B model following quality annotation. Each sample includes three independently translated components: user input, chain-of-thought (marked with the <think> tag), and final output. The translation process strictly retains technical terms, mathematical symbols, and reasoning structures. The dataset contains 2,282,204 samples, with an average total length of 4,023 tokens per English sample (424 tokens for input and 3,599 tokens for output). Its feature fields include message content (content), role (role), data source (source), dataset name (dataset_name), and other relevant fields. It is derived from 6 existing reasoning datasets, including Cascade-SFT, Dolci-Think, and others. This dataset is licensed under Apache-2.0, and is suitable for applications such as multilingual reasoning model training and chain-of-thought research.