cds-jb/cot-qwen3-8b
收藏资源简介:
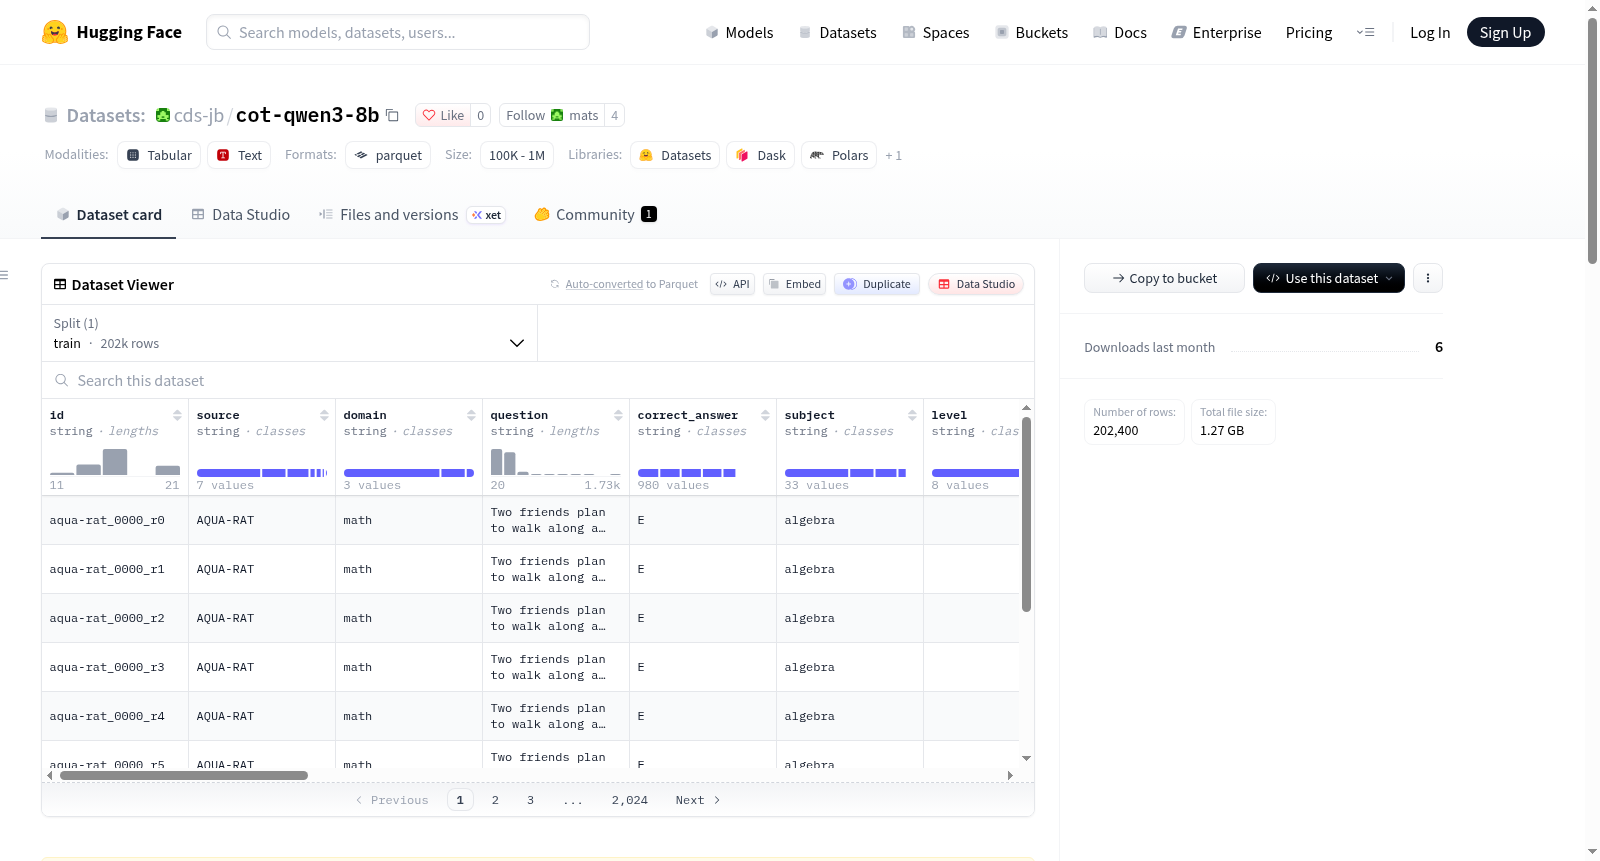
# CoT Oracle Corpus v5 (Qwen3-8B) — 10× rollouts, judged Reproduction of [`ceselder/cot-oracle-corpus-v5`](https://huggingface.co/datasets/ceselder/cot-oracle-corpus-v5) generated with `Qwen3-8B`, **10 distinct rollouts per problem** (vs the OG's 2), and categorized by a Qwen3.5-4B LLM judge. ## Stats - 202,400 entries (= 20,239 unique problems × 10 rollouts) - aggregate `cot_correct`: **92.4%** - per-problem majority-vote correct: **92.9%** (187,740/202,010) - IDs format: `<source>_<NNNNN>_r<rollout>` (globally unique) ## Per-source `cot_correct` | source | n | cot_correct | |---|---|---| | AQUA-RAT | 100000 | 93.8% | | CommonsenseQA | 38810 | 81.3% | | GSM8K | 35200 | 96.5% | | ARC-Easy | 9500 | 99.0% | | ASDiv | 9200 | 98.1% | | MATH | 5000 | 95.4% | | ARC | 4690 | 96.1% | ## Generation - model: `Qwen/Qwen3-8B` - engine: vLLM 0.20.0, bf16 - sampling: temperature=0.6, top_p=0.95, `enable_thinking=True` - token budget: max_new_tokens=16384 throughout (fixes the truncation that limited the OG) - 10 rollouts × 20,240 problems = 202,400 entries - 16 H200 data-parallel; ~4h wall ## Categorization A small LLM judge (Qwen3.5-4B) reads each row's CoT text and the ground truth and returns YES/NO/UNCLEAR. Categories: - `load_bearing`: cot ✓, direct ✗ (CoT was necessary) - `both_correct`: cot ✓, direct ✓ - `both_wrong`: cot ✗, direct ✗ - `cot_hurt`: cot ✗, direct ✓ - `judge_unclear`: judge couldn't decide on cot or direct Categories distribution: {'judge_unclear': 86027, 'both_correct': 104066, 'load_bearing': 4697, 'cot_hurt': 2708, 'both_wrong': 4902} The `judge_unclear` bucket is concentrated in MATH/AQUA-RAT, where the direct (no-thinking) response is capped at 200 tokens and often too brief for the judge to verify equivalence with the ground truth. Treat `judge_unclear` rows as "cot_correct true/false known but direct unknown" if you need a fallback partition. ## Schema Same as ceselder/cot-oracle-corpus-v5, plus: - `judge_cot_verdict`, `judge_direct_verdict`: raw YES/NO/UNCLEAR from judge - `rollout_majority_correct`: True if >50% of the 10 rollouts of the same problem are cot_correct - `rollout_n_correct`, `rollout_n_total`: per-problem count of correct rollouts
The CoT Oracle Corpus v5 (Qwen3-8B) dataset is a reproduction of the original ceselder/cot-oracle-corpus-v5, generated using the Qwen3-8B model. It features 10 distinct rollouts per problem (compared to 2 in the original) and is categorized by a Qwen3.5-4B LLM judge. The dataset contains 202,400 entries, corresponding to 20,239 unique problems, with an aggregate cot_correct rate of 92.4% and a per-problem majority-vote correct rate of 92.9%. Data sources include AQUA-RAT, CommonsenseQA, GSM8K, ARC-Easy, ASDiv, MATH, and ARC, with cot_correct rates ranging from 81.3% to 99.0% per source. Generation was performed using the vLLM 0.20.0 engine with bf16 precision, sampling parameters temperature=0.6 and top_p=0.95, and enable_thinking=True, with a maximum of 16,384 new tokens. Categorization is based on the judges evaluation of CoT text and ground truth, resulting in five categories: load_bearing (CoT correct, direct incorrect), both_correct (both correct), both_wrong (both incorrect), cot_hurt (CoT incorrect, direct correct), and judge_unclear (judge unable to decide). The distribution shows judge_unclear as the most frequent (86,027 entries), followed by both_correct (104,066 entries). The schema extends the original with additional fields for judge verdicts and rollout statistics, such as rollout_majority_correct, rollout_n_correct, and rollout_n_total.