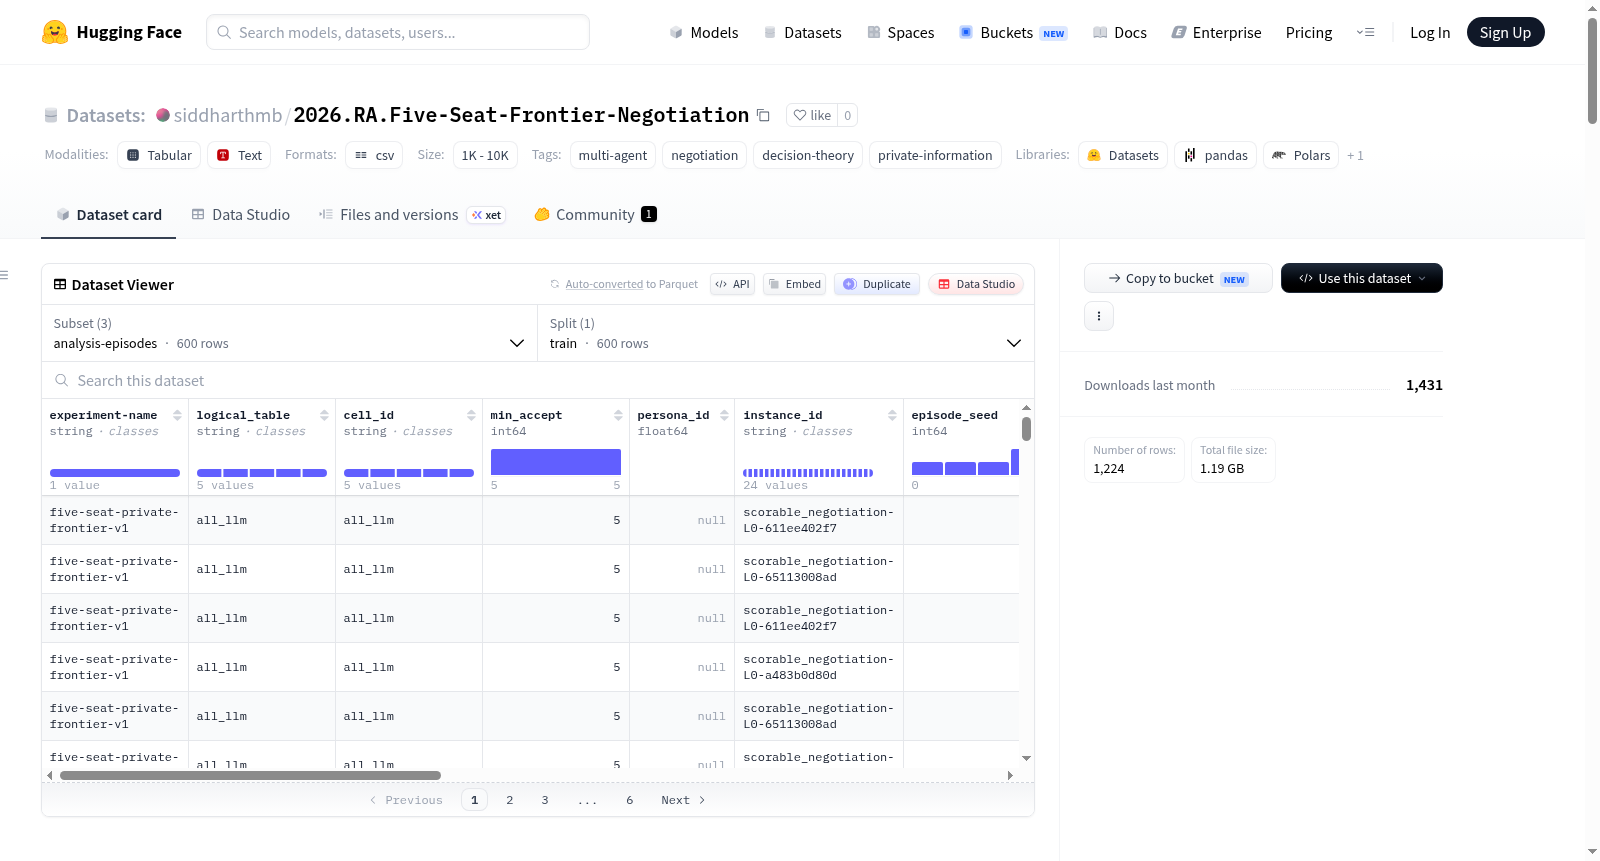
2026.RA.Five-Seat-Frontier-Negotiation
收藏资源简介:
该数据集是五方数据中心谈判实验的公共证据包。实验涉及五个智能体,每个智能体仅接收其私人偏好表和整数阈值,可以提出方案和发送公开说服信息,并使用显式API思考。实验包含五种主要条件:五个LLM(Claude Opus 5)、四个LLM加一个旋转的私人信息理性代理、四个LLM加一个旋转的全知预言家、五个理性代理和五个预言家代理。每个条件使用24个参数集×5个种子,共120个会话,五组主实验共600个会话。生成模型为 Anthropic Claude Opus 5。数据集包含参数集表、会话索引表、分析表、原始会话记录(保留API返回的推理摘要)、Markdown/HTML转录、每个可计分轮次的私人理性反事实和全知预言家反事实,以及交互式可视化工具。此外,还包含能力阶梯扩展(240个新会话,使用Sonnet 5和Haiku 4.5模型,同一银行的五座全LLM表)和Advised advocate扩展(120个会话,其中一个LLM被私下告知贝叶斯策略的精确行动并添加说服信息)。注意:原始发布的预言家臂存在投票错误(OmniscientBestResponsePolicy在强制终局投票中投给了当前最值方案而非待表决方案),导致通过率等指标失真,但修正后的数据(采用修复后的臂)已包含在数据集中(分别位于runs_ballot_repaired和关联数据集)。数据集适用于多智能体谈判、私人信息博弈、决策理论分析、语言模型性能评估等研究。
This dataset is a public evidence package for the five-party data center negotiation experiment. The experiment involves five agents, each receiving only its private preference table and integer threshold, capable of proposing solutions and sending public persuasive messages, and using an explicit API to think. The experiment includes five main conditions: five LLMs (Claude Opus 5), four LLMs plus one rotating private information rational agent, four LLMs plus one rotating omniscient oracle, five rational agents, and five oracle agents. Each condition uses 24 parameter sets × 5 seeds, totaling 120 sessions, with five main experimental groups totaling 600 sessions. The generative model is Anthropic Claude Opus 5. The dataset contains parameter set tables, session index tables, analysis tables, raw session records (preserving API-returned reasoning summaries), Markdown/HTML transcripts, private rational counterfactuals and omniscient oracle counterfactuals for each scorable round, and interactive visualization tools. Additionally, it includes a capability ladder extension (240 new sessions using Sonnet 5 and Haiku 4.5 models, same bank of five all-LLM tables) and an Advised advocate extension (120 sessions, where one LLM is privately informed of the precise action of the Bayesian strategy and adds persuasive messages). Note: The originally released oracle arm had a voting error (OmniscientBestResponsePolicy voted for the current best solution instead of the pending one in mandatory final voting), causing distortions in metrics such as pass rate, but corrected data (using the repaired arm) is included in the dataset (located in runs_ballot_repaired and associated datasets). The dataset is suitable for research on multi-agent negotiation, private information games, decision theory analysis, and language model performance evaluation.
Five-Seat Frontier Negotiation 数据集概述
基本信息
- 数据集名称:Five-Seat Frontier Negotiation
- 数据集地址:https://huggingface.co/datasets/siddharthmb/2026.RA.Five-Seat-Frontier-Negotiation
- 数据类型:多智能体谈判实验的公开证据包
- 生成模型:
anthropic:claude-opus-5 - 实验名称:
five-seat-private-frontier-v1 - 冻结活动名称:
five_seat_private_opus_v3
实验设计
该数据集包含一个匹配的五方数据中心谈判实验,每个LLM仅接收其私有偏好表和整数的接受阈值,可以提出方案、发送公开说服性消息,并使用显式API思考。
五个主要条件
- 五个LLM(
all_llm) - 四个LLM + 一个轮换的私有信息理性智能体(
one_rational) - 四个LLM + 一个轮换的全知预言机(
one_oracle) - 五个理性智能体(
all_rational) - 五个预言机智能体(
all_oracle)
每个条件使用24个参数集 × 5个种子,共120场游戏。
关键特性
- 每个可提交/可计分的回合都有私有信息理性反事实和全知预言机反事实双重要注释
- 原始回合保留提供者返回的推理摘要/令牌(不声称访问隐藏的思维链)
- 无法解析的排放(包括重试尝试)在原始回合和记录中保持可见,但不产生注释回合
⚠ 重要勘误说明
勘误1(2026-08-10)— 预言机臂存在有缺陷的选票
OmniscientBestResponsePolicy(每个*_oracle阵容中的可计算席位)在强制最终投票中投给了它认为价值最高的实时报价,而不是正在表决的报价。协议将其视为合法性错误,该席位在一次重试中重复自身,回合被记录为弃权。
all_oracle的交易率从0.875 → 1.000(其15次未成交均为有缺陷选票),得分从0.791 → 0.907- 在预注册的新银行复制中,
one_oracle−all_llm的功利得分差异为−0.068 [−0.136, −0.001],而非−0.412 - 修复于提交
ca20157(2026-08-10),晚于本包中所有回合 - 不含该策略的臂(all-LLM、私有贝叶斯阵容、公平性/DP组合策略)是干净的(9,589个重新推导回合中0个不匹配)
勘误2(2026-08-14)— 两个预言机臂的收官数据均为有缺陷选票
重新推导后发现:all_oracle的107个强制最终回合中有94个受到影响,涉及其全部15个未成交回合;one_oracle中全知席位的116个强制最终选票中有114个受影响,涉及其59个未成交回合中的57个。
| 臂 | 交易率 | 标准化得分 | 与all_llm的配对得分 |
|---|---|---|---|
all_oracle(此处发布) |
0.875 | 0.791 | −0.082 [−0.146, −0.022] |
all_oracle(修复后) |
1.000 | 0.907 | +0.034 [+0.001, +0.074] |
one_oracle(此处发布) |
0.508 | 0.461 | −0.412 [−0.495, −0.321] |
one_oracle(修复后) |
0.917 | 0.829 | −0.044 [−0.104, +0.011](无效) |
修正后的排序:all_oracle > all_llm > one_oracle > one_rational > all_rational(交易率和得分均如此)。只有私有信息贝叶斯智能体会崩溃,全知阵容的成交频率与LLM表格相当或更高,这五个臂所描绘的梯度是信息,而非可计算性。
修复后的one_oracle运行发布在runs_ballot_repaired/one_oracle/下;修复后的all_oracle运行发布在兄弟数据集2026.RA.Seeded-Optimal-Opening中,作为其*_ballot_fixed臂。
数据内容
目录结构
bank/:冻结的、经哈希验证的24参数集库及其难度度量campaign/:活动清单和完整不可变尝试的确定性选择runs/<logical-table>/:选定的运行清单/日志、精确保存的实例、回合、Markdown/HTML记录、双注释和自包含的交互式可视化器tables/parameter_sets.csv:可追加的参数集索引tables/episode_index.csv:每个回合一行,包含所有配对公共工件的路径analysis/:分析行、机器可读摘要、叙述性摘要和每个在summary.json中声明的图writeup/:可复现的LaTeX源码和编译后的PDFartifact_manifest.json:每个其他打包文件的字节大小和SHA-256哈希
数据集配置
parameter-sets:tables/parameter_sets.csv(训练分割)episodes:tables/episode_index.csv(训练分割)analysis-episodes:analysis/episode_rows.csv(训练分割)
附加实验
能力阶梯(capability_ladder_v1/)
240个新回合:五席全LLM表格分别使用五个Sonnet 5席位和五个Haiku 4.5席位在bank-v2协议上重新运行,与匹配的Opus-5参考及同银行可计算臂配对。实验名称:five-seat-capability-ladder-v1。主要发现:阶梯的大步是Sonnet → Opus(配对交易率−0.383),而非Haiku → Sonnet(−0.075,未解决),公平性与能力排序一致。
咨询倡导者(wave 1, arm A2,five_seat_advised_v1/)
120个回合的rational_advised_llm:五个Opus-5席位,其中一个被私下告知one_rational臂的贝叶斯策略会采取的确切行动,并被指示执行该行动并添加有说服力的公开消息。实验名称:five-seat-advised-advocate-v1。它将会发布的one_rational赤字分解为渠道组件和规则组件。
相关公共数据集
- 2026.RA.Negotiation-Campaigns:早期的理性智能体谈判活动和控制组
- 2026.RA.Divergence-DPO-Pairs:从相关谈判分歧中导出的偏好对
- Anthropic模型文档:用于生成LLM回合的托管模型家族文档
使用注意事项
- 不要在不考虑预言机席位的强制最终投票缺陷的情况下,基于该席位的回合进行训练或评估
- 本包中的预言机臂保持原样,作为该版本的记录
- 该仓库设计为可追加扩展:兼容的未来表格应保留其模式并使用新的
experiment-name值 - 完整的勘误账户见源仓库中的研究笔记0045、0039和0043