
SlovKE
收藏资源简介:
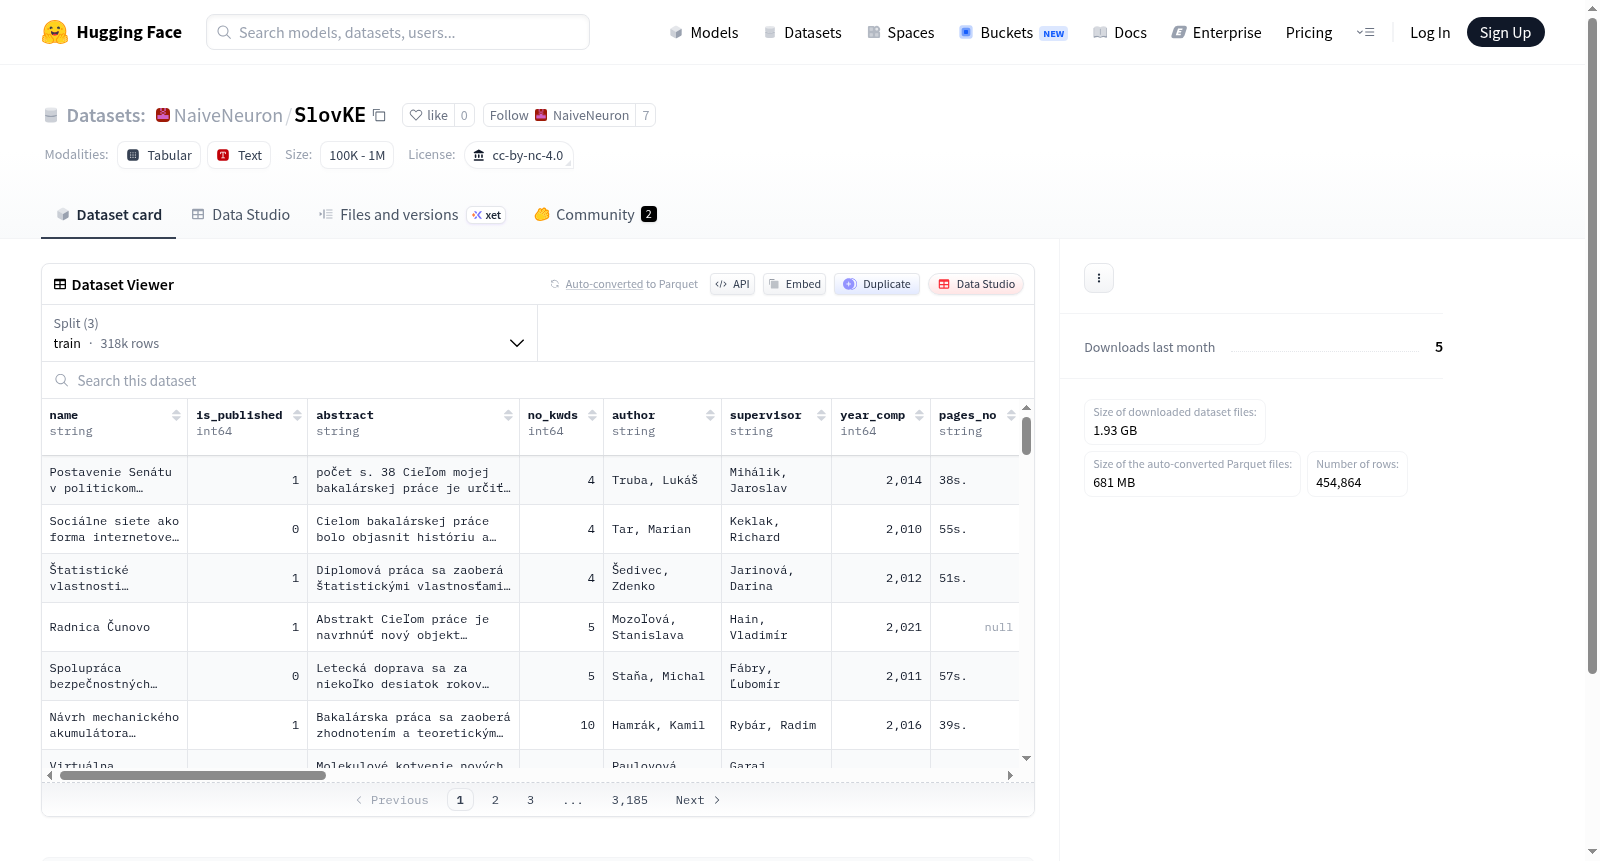
SlovKE是由NaiveNeuron等机构联合构建的斯洛伐克语关键词提取基准数据集,包含22.7万篇经过系统清洗的科学摘要及作者标注的关键短语,规模达到先前最大斯洛伐克语资源的25倍。数据集源自斯洛伐克中央论文注册系统,通过多阶段清洗流程去除重复记录、混合语言内容和不一致元数据,最终保留50-2000字符的摘要和4-15个关键短语。该数据集支持形态复杂语言的关键词提取研究,特别针对低资源斯拉夫语系语言中词形变化导致的表面形式与规范短语不匹配问题,为无监督方法和LLM模型提供了重要评估基准。
SlovKE is a Slovak keyword extraction benchmark dataset jointly constructed by NaiveNeuron and other institutions. It comprises 227,000 systematically cleaned scientific abstracts and author-annotated key phrases, with a scale 25 times that of the previously largest Slovak language resource. The dataset is sourced from the Slovak Central Paper Registration System, and underwent a multi-stage cleaning process to remove duplicate records, mixed-language content and inconsistent metadata, finally retaining abstracts of 50–2000 characters and 4–15 key phrases per entry. This dataset supports keyword extraction research on morphologically complex languages, specifically addressing the mismatch between surface forms and standard phrases caused by inflection in low-resource Slavic languages, and serves as an important evaluation benchmark for unsupervised methods and LLM models.
数据集概述
基本信息
- 数据集名称:SlovKE
- 托管平台:Hugging Face
- 发布者:NaiveNeuron
- 许可证:cc-by-nc-4.0(知识共享署名-非商业性使用 4.0 国际许可协议)
许可证说明
- 本数据集采用知识共享署名-非商业性使用 4.0 国际许可协议(CC BY-NC 4.0)进行授权。
- 使用者可以自由地共享、改编本数据集,但必须给出适当的署名,且不得将本数据集用于商业目的。
- 1SlovKE: A Large-Scale Dataset and LLM Evaluation for Slovak Keyphrase Extraction维也纳大学; 夸美纽斯大学·数学、物理与信息学院; 思科系统公司; NaiveNeuron · 2026年


