surgeai/GDP.pdf
收藏资源简介:
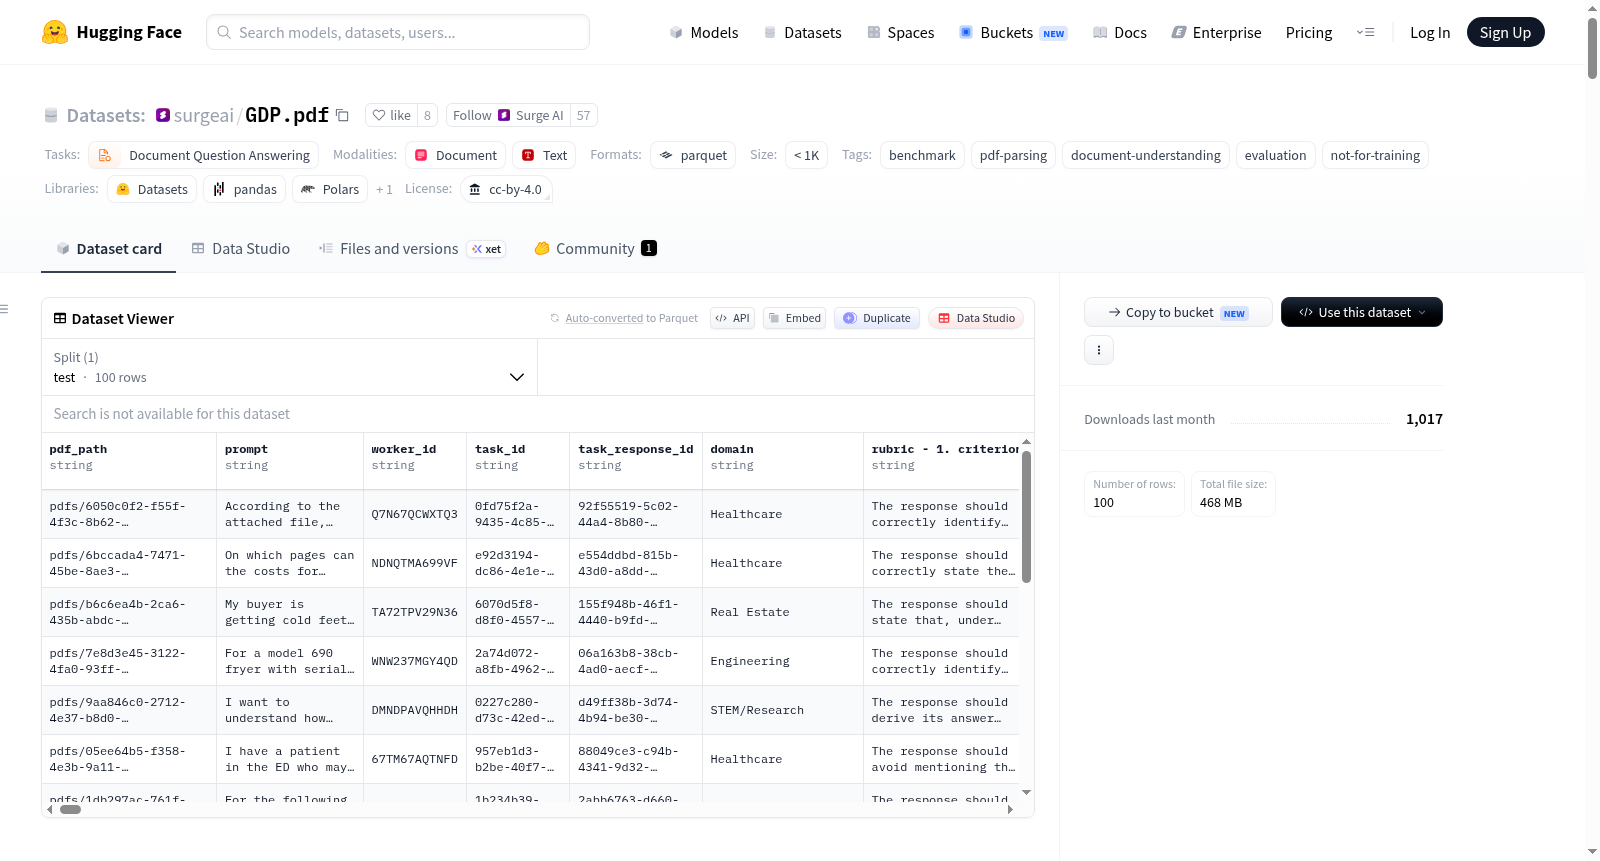
GDP.pdf是一个专门用于评估PDF解析和文档理解系统的基准数据集。该数据集包含100个示例,每个示例对应一个唯一的PDF文档,并与一个提示(prompt)及一组评分标准(rubric criteria)配对,这些标准定义了正确响应应包含的内容。每个示例最多有30个评分标准,用于独立检查模型响应的各个方面。数据集仅包含测试集(test split),没有训练集,这是为了防止数据污染和确保评估的公正性。数据集结构包括元数据表(data.parquet)和PDF文档(pdfs/目录)。使用该数据集时,需将PDF和提示输入系统,然后根据评分标准对响应进行评分。数据集仅用于评估或基准测试,不能用于训练、微调或其他训练阶段。许可证方面,元数据部分使用cc-by-4.0许可证,而PDF文档是第三方内容,版权归原作者所有,仅用于非商业研究和评估目的。
A benchmark for evaluating PDF parsing and document understanding systems. It contains 100 examples, each pairing a unique PDF document with a prompt and a set of rubric criteria that define what a correct response should contain. Each example has up to 30 rubric criteria for independent evaluation. The dataset includes only a test split (no train split) to prevent data contamination and ensure fair evaluation. The structure consists of a metadata table (data.parquet) and PDF documents (in the pdfs/ directory). Usage involves passing the PDF and prompt to a system and scoring the response against the rubric criteria. The dataset is intended solely for evaluation or benchmarking and must not be used for training, fine-tuning, or other training stages. Licensing-wise, the metadata is under cc-by-4.0, while the PDF documents are third-party content with their own copyrights, included for non-commercial research and evaluation purposes.