open-wikipedia-markdown
收藏资源简介:
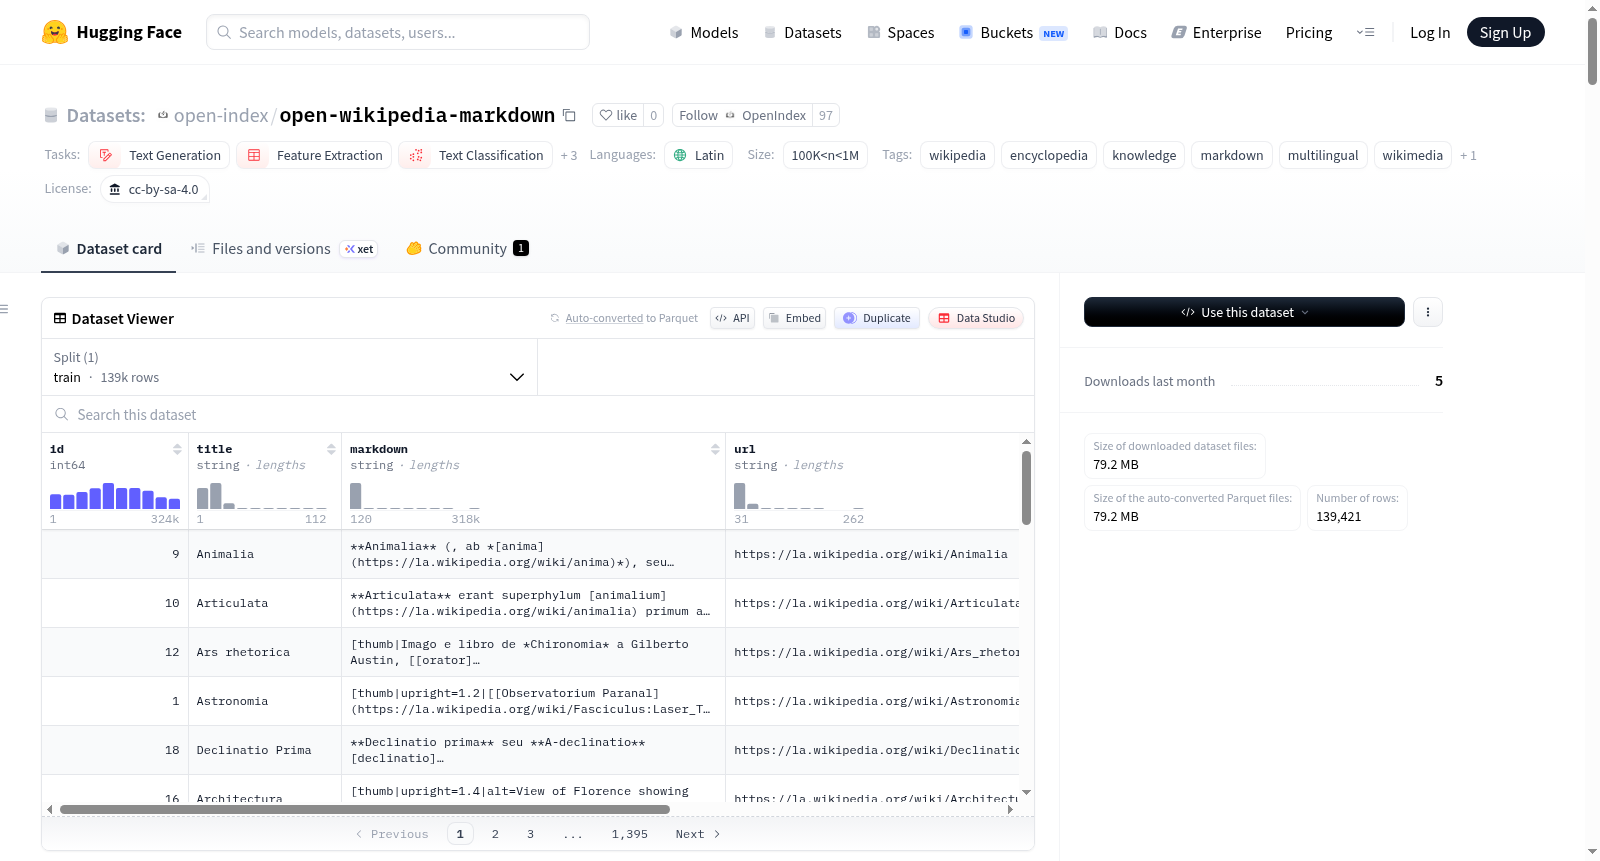
Open Wikipedia (Markdown) 数据集包含所有语言版本的维基百科文章,这些文章已从原始的 MediaWiki 标记转换为干净、可读的 Markdown 格式。数据集保留了标题、粗体、斜体、代码块和内部链接等 Markdown 语法,同时移除了模板、信息框、引用、表格、分类等噪音内容。当前数据集包含 139.4K 篇文章,涵盖 1 种语言(拉丁语),数据来源于官方的 Wikimedia 数据库转储。数据集以分片的 Apache Parquet 文件形式存储,每个文件最多包含 500,000 篇文章。数据集适用于文本生成、特征提取、文本分类、问答、摘要和翻译等任务。
Open Wikipedia (Markdown) Dataset contains Wikipedia articles from all language editions, which have been converted from the original MediaWiki markup into clean, readable Markdown format. The dataset retains Markdown syntax elements including titles, bold text, italic text, code blocks, and internal links, while removing noisy content such as templates, infoboxes, citations, tables, and categories. Currently, the dataset includes 139.4K articles covering 1 language (Latin), with data sourced from official Wikimedia database dumps. It is stored as sharded Apache Parquet files, with each file containing up to 500,000 articles. This dataset is applicable to tasks such as text generation, feature extraction, text classification, question answering, summarization, and machine translation.
Open Wikipedia (Markdown) 数据集概述
数据集基本信息
- 数据集名称: Open Wikipedia (Markdown)
- 发布者: Open Index
- 发布日期: 2026年
- 许可证: Creative Commons Attribution-ShareAlike 4.0 International License (CC BY-SA 4.0)
- 数据集地址: https://huggingface.co/datasets/open-index/open-wikipedia-
数据集内容与目标
- 核心内容: 包含所有语言版本的维基百科文章,已从原始的MediaWiki标记语言转换为干净、可读的Markdown格式。
- 数据来源: 官方Wikimedia数据库转储 (https://dumps.wikimedia.org/)。
- 处理目标: 保留标题、粗体、斜体、代码块和内部链接等作为正确的Markdown语法,同时去除模板、信息框、引用、表格、分类和其他噪音。
- 数据状态: 数据集正在积极填充中,新语言在处理完成后会陆续添加。预计完成日期为2026年4月13日。
数据规模与结构
- 当前规模: 包含1种语言,共计139,421篇文章。
- 数据格式: 以Apache Parquet文件(使用Zstandard压缩)分片存储。
- 组织结构: 按语言组织,每种语言在
data/目录下拥有自己的子目录,每个分片最多包含500,000篇文章。 - 当前可用语言:
- 拉丁语 (
la): 139.4K篇文章,1个分片。
- 拉丁语 (
数据模式 (Schema)
每个Parquet文件共享相同的模式,包含以下字段:
| 字段名 | 数据类型 | 描述 |
|---|---|---|
id |
int64 |
维基百科页面ID,在每种语言版本中唯一。 |
title |
string |
文章标题,与维基百科上显示的一致。 |
markdown |
string |
从wikitext转换而来的完整文章正文(Markdown格式)。 |
url |
string |
维基百科文章的直接URL。 |
lang |
string |
ISO 639语言代码(例如 en, de, fr, ja)。 |
length |
int32 |
Markdown正文的字节长度。 |
timestamp |
string |
最后一次修订的时间戳(ISO 8601格式)。 |
数据处理流程
- 下载: 从dumps.wikimedia.org流式下载最新的
{lang}wiki-latest-pages-articles.xml.bz2转储文件。 - 解析: 使用流式XML解析器处理bzip2压缩的转储文件,仅保留命名空间-0的页面(文章)。
- 转换: 通过一系列基于正则表达式的转换,将每篇文章的wikitext转换为Markdown。
- 过滤: 排除转换后长度小于100字节的文章。
- 分片: 将文章写入Zstandard压缩的Parquet文件,每片约500,000行。
- 发布: 每种语言的分片在处理完成后提交至Hugging Face仓库。
使用方式
- 使用DuckDB: 可直接从Hugging Face读取Parquet文件进行查询。
- 使用
datasets库: 通过load_dataset函数加载特定语言的数据集。 - 使用
huggingface_hub库: 通过snapshot_download下载特定语言的数据。 - 使用CLI: 通过
huggingface-cli download命令下载。 - 使用Polars: 通过
pl.read_parquet读取Parquet文件进行分析。
相关数据集
- 纯文本版本: https://huggingface.co/datasets/open-index/open-wikipedia-text
- 原始wikitext版本: https://huggingface.co/datasets/open-index/open-wikipedia
已知限制
- 转换基于正则表达式,并非完整解析器,某些复杂的wikitext结构可能无法完美转换。
- 模板被完全剥离,而非展开,这意味着一些在渲染后的维基百科页面中出现的结构化数据在此数据集中不存在。
- 此数据集代表每种语言转储的单一快照,不跟踪编辑历史或文章修订。
- 并非所有语言版本的转储都始终可用。