synthetic_vocal_burts_dramabox
收藏资源简介:
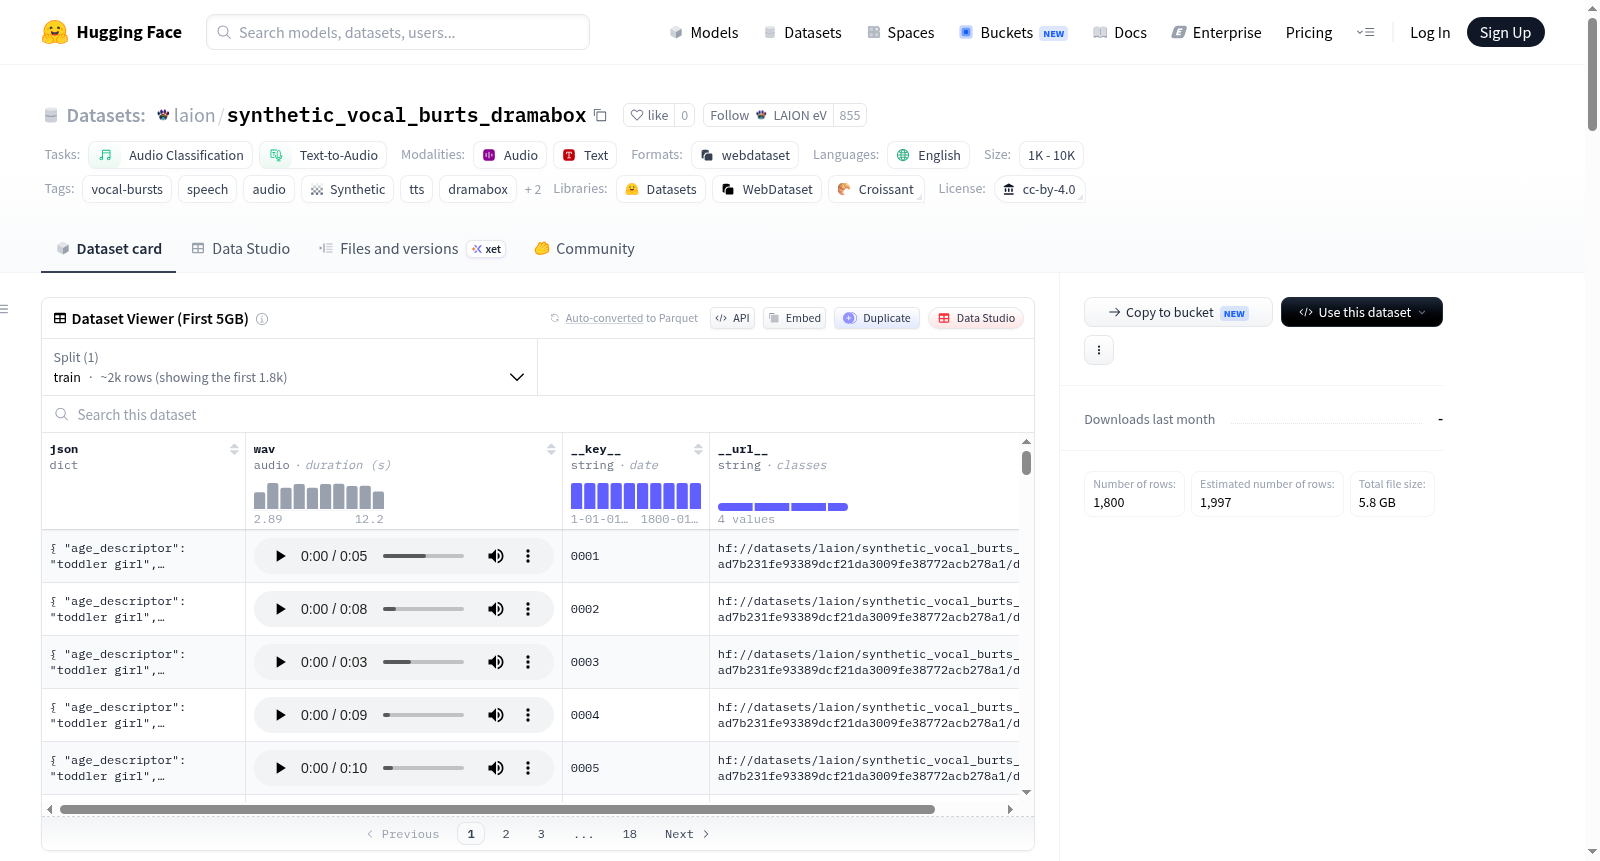
Synthetic Vocal Bursts (DramaBox) 是一个由LAION发布的合成人声爆发音频数据集。该数据集旨在为人类非言语发声提供一个全面的分类学研究资源。它包含2,000个音频样本,总时长约4.2小时(14,992秒),平均每个样本7.5秒,时长范围在3.0至12.0秒之间。所有音频均为44.1 kHz采样率的WAV格式。数据集在性别上完全平衡,包含1,000个女性样本和1,000个男性样本,并进一步细分为16个年龄/性别组(每组125个样本),覆盖从幼儿到衰老期的不同生命阶段。数据集的核⼼是覆盖了197种独特的人声爆发类型,这些类型基于LAION Voice-Acting-Pipeline的分类法进行了扩展,新增了NSFW发声、运动/原始声音、歌唱、哼唱、口哨等类别,并同时提供了一个包含180个条目的安全内容(SFW)子集。示例类型包括腹笑、轻笑、呜咽、喘息、恼怒的哼声、战斗呐喊、摇篮曲哼唱等。每个样本由两部分组成:一个.wav音频文件和一个包含详细元数据的.json文件。元数据包括样本ID、生成提示词、时长、性别、年龄组、人声爆发关键词及其描述。数据集以WebDataset tar分片格式存储,便于流式加载和处理。所有样本均使用DramaBox TTS模型在8块NVIDIA A100 GPU上合成生成。该数据集适用于音频分类、文本到音频生成、语音情感计算以及人机交互等领域的研究和模型训练。数据集采用知识共享署名4.0国际许可协议(CC BY 4.0)发布。
Synthetic Vocal Bursts (DramaBox) is a synthetic vocal burst audio dataset released by LAION. It aims to provide a comprehensive taxonomic resource for human non-verbal vocalizations. The dataset contains 2,000 audio samples with a total duration of approximately 4.2 hours (14,992 seconds), averaging 7.5 seconds per sample, and a duration range from 3.0 to 12.0 seconds. All audio is in WAV format with a 44.1 kHz sampling rate. The dataset is fully balanced by gender, including 1,000 female samples and 1,000 male samples, and further subdivided into 16 age/gender groups (125 samples per group), covering different life stages from infancy to old age. The core of the dataset covers 197 unique vocal burst types, which are extended based on the LAION Voice-Acting-Pipeline taxonomy, adding categories such as NSFW vocalizations, movement/primitive sounds, singing, humming, whistling, and also includes a safe-for-work (SFW) subset with 180 entries. Example types include belly laugh, light chuckle, whimper, gasp, annoyed grunt, battle cry, lullaby hum, etc. Each sample consists of two parts: a .wav audio file and a .json file containing detailed metadata. The metadata includes sample ID, generation prompt, duration, gender, age group, vocal burst keywords, and their descriptions. The dataset is stored in WebDataset tar shards for easy streaming loading and processing. All samples were synthesized using the DramaBox TTS model on 8 NVIDIA A100 GPUs. The dataset is suitable for research and model training in areas such as audio classification, text-to-audio generation, speech emotion computing, and human-computer interaction. The dataset is released under the Creative Commons Attribution 4.0 International License (CC BY 4.0).
数据集概述
数据集名称:Synthetic Vocal Bursts (DramaBox)
许可证:Creative Commons Attribution 4.0 International (CC BY 4.0)
任务类别:音频分类、文本转音频
语言:英语
数据集规模:1K < n < 10K(2,000个样本)
数据集详情
- 总样本数:2,000个音频片段
- 总时长:约4.2小时(14,992秒)
- 平均时长:7.5秒
- 时长范围:3.0 – 12.0秒
- 采样率:44.1 kHz(WAV格式)
- 性别分布:1,000个女性 / 1,000个男性
- 年龄组:16组(8个女性组、8个男性组)
- 每组样本数:125个
- 独特声音爆发类型:197种
- 生成模型:DramaBox TTS
- 硬件:8x NVIDIA A100 GPU
年龄组
数据集在16个年龄/性别组间平衡(每组125个样本):
女性组:
- toddler_girl(幼儿女孩)
- pre_puberty_girl(青春期前女孩)
- teenage_girl(青少年女孩)
- young_woman(年轻女性)
- mature_woman(成熟女性)
- middle_aged_woman(中年女性)
- elderly_woman(老年女性)
- senescent_woman(衰老女性)
男性组:
- toddler_boy(幼儿男孩)
- pre_puberty_boy(青春期前男孩)
- teenage_boy(青少年男孩)
- young_man(年轻男性)
- mature_man(成熟男性)
- middle_aged_man(中年男性)
- elderly_man(老年男性)
- senescent_man(衰老男性)
声音爆发分类
数据集使用了扩展的197种声音爆发类型分类体系,来源包括:
- 原始LAION分类:约120个条目(来自LAION Voice-Acting-Pipeline)
- 附加类别:NSFW声音、运动/原始声音、唱歌、哼唱、吹口哨
此外还提供了一个SFW(安全)子集,包含180个条目,过滤了NSFW内容。
分类文件包含在数据集中:
vocal_bursts_taxonomy_extended.json:完整扩展分类(202个条目 + 元数据)vocal_bursts_taxonomy_sfw.json:SFW子集(180个条目 + 元数据)
示例声音爆发类型:捧腹大笑、轻声笑、咯咯笑、窃笑、尖笑、轻声哭泣、痛哭、呜咽、喘息、如释重负的叹息、恼怒的哼声、沮丧的低吼、惊吓咕哝、黑暗中紧张的吹口哨、战斗呐喊、摇篮曲哼唱等。
数据格式
数据集以WebDataset tar分片形式存储在 data/ 目录下:
data/ shard-0000.tar (样本 0001–0500) shard-0001.tar (样本 0501–1000) shard-0002.tar (样本 1001–1500) shard-0003.tar (样本 1501–2000)
每个分片是标准的tar归档文件。每个样本包含两个文件,共享相同的零填充4位键:
{NNNN}.wav— 音频文件(WAV,44.1 kHz){NNNN}.json— 元数据JSON
元数据字段:
json { "id": 1, "prompt": "A toddler girl performing Nervous Whistling in the Dark, A shaky, slightly off-key whistling used to mask fear in an unsettling environment.", "duration_s": 5.2, "gender": "female", "age_group": "toddler_girl", "age_descriptor": "toddler girl", "vocal_burst_key": "Nervous Whistling in the Dark", "vocal_burst_description": "A shaky, slightly off-key whistling used to mask fear in an unsettling environment." }
使用方式
使用 webdataset(推荐用于流式/训练):
python import webdataset as wds import json
url = "https://huggingface.co/datasets/laion/synthetic_vocal_burts_dramabox/resolve/main/data/shard-{0000..0003}.tar"
dataset = ( wds.WebDataset(url, shardshuffle=True) .decode("pil") .to_tuple("wav", "json") )
for wav_bytes, metadata_bytes in dataset: metadata = json.loads(metadata_bytes) print(metadata["vocal_burst_key"], metadata["age_descriptor"], len(wav_bytes), "bytes") break
使用 huggingface_hub(下载单个分片):
python from huggingface_hub import hf_hub_download
path = hf_hub_download( repo_id="laion/synthetic_vocal_burts_dramabox", filename="data/shard-0000.tar", repo_type="dataset", )
直接提取tar文件:
python import tarfile import json
with tarfile.open("shard-0000.tar") as tar: members = tar.getmembers() for m in members[:4]: print(m.name, m.size)
附加文件
prompts_manifest.csv:完整生成清单,包含列:id,prompt,output_path,gender,age_group,vocal_burst_key,vocal_burst_description,duration_svocal_bursts_taxonomy_extended.json:扩展分类(202个条目)vocal_bursts_taxonomy_sfw.json:SFW分类(180个条目)
生成过程
- 从LAION Voice-Acting-Pipeline分类中整理出扩展的声音爆发分类,并添加附加类别
- 对于16个年龄/性别组中的每组,从分类中采样125种声音爆发类型
- 生成文本提示,格式为:"A {age_descriptor} performing {burst_key}, {burst_description}"
- 使用DramaBox TTS在8x NVIDIA A100 GPU上分布式合成音频
- 每个样本生成时随机设定3–12秒的时长
引用
如使用本数据集,请引用:
bibtex @dataset{synthetic_vocal_bursts_dramabox_2026, title={Synthetic Vocal Bursts (DramaBox)}, author={LAION}, year={2026}, url={https://huggingface.co/datasets/laion/synthetic_vocal_burts_dramabox}, license={CC-BY-4.0} }