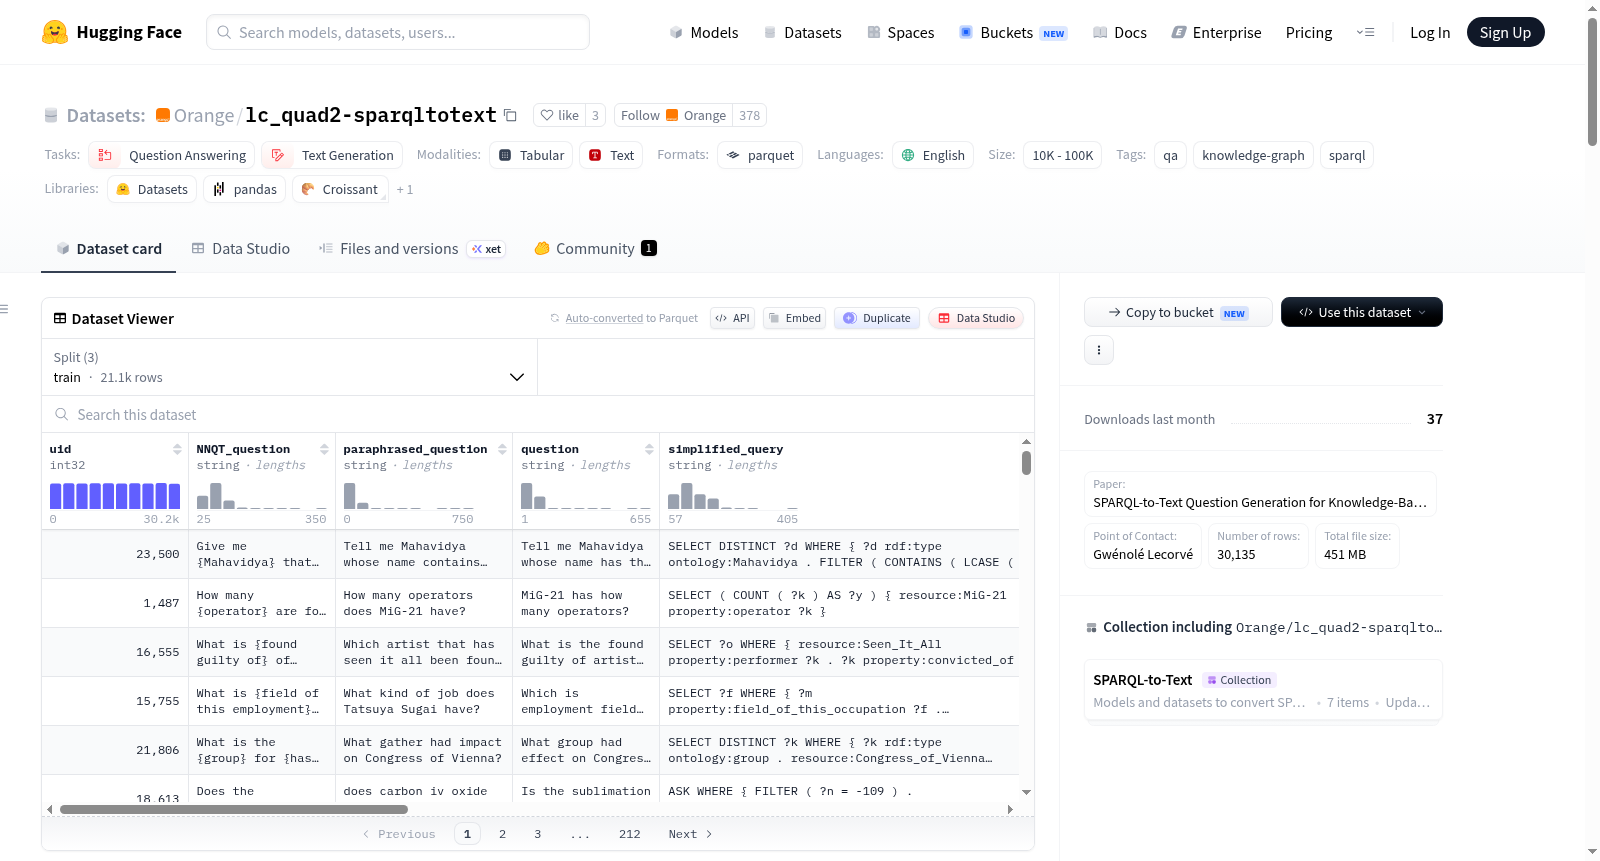
Orange/lc_quad2-sparqltotext
收藏资源简介:
--- dataset_info: features: - name: uid dtype: int32 - name: NNQT_question dtype: string - name: paraphrased_question dtype: string - name: question dtype: string - name: simplified_query dtype: string - name: sparql_dbpedia18 dtype: string - name: sparql_wikidata dtype: string - name: answer list: string - name: solved_answer list: string - name: subgraph dtype: string - name: template dtype: string - name: template_id dtype: string - name: template_index dtype: int32 splits: - name: train num_bytes: 241621115 num_examples: 21101 - name: validation num_bytes: 11306539 num_examples: 3010 - name: test num_bytes: 21146458 num_examples: 6024 download_size: 79003648 dataset_size: 274074112 task_categories: - question-answering - text-generation tags: - qa - knowledge-graph - sparql language: - en --- # Dataset Card for LC-QuAD 2.0 - SPARQLtoText version ## Table of Contents - [Dataset Card for LC-QuAD 2.0 - SPARQLtoText version](#dataset-card-for-lc-quad-20---sparqltotext-version) - [Table of Contents](#table-of-contents) - [Dataset Description](#dataset-description) - [Dataset Summary](#dataset-summary) - [New field `simplified_query`](#new-field-simplified_query) - [New split "valid"](#new-split-valid) - [Supported tasks](#supported-tasks) - [Languages](#languages) - [Dataset Structure](#dataset-structure) - [Types of questions](#types-of-questions) - [Data splits](#data-splits) - [Additional information](#additional-information) - [Related datasets](#related-datasets) - [Licencing information](#licencing-information) - [Citation information](#citation-information) - [This version of the corpus (with normalized SPARQL queries)](#this-version-of-the-corpus-with-normalized-sparql-queries) - [Original version](#original-version) ## Dataset Description - **Paper:** [SPARQL-to-Text Question Generation for Knowledge-Based Conversational Applications (AACL-IJCNLP 2022)](https://aclanthology.org/2022.aacl-main.11/) - **Point of Contact:** Gwénolé Lecorvé ### Dataset Summary Special version of [LC-QuAD 2.0](https://huggingface.co/datasets/lc_quad) for the SPARQL-to-Text task #### New field `simplified_query` New field is named "simplified_query". It results from applying the following step on the field "query": * Replacing URIs with a simpler format with prefix "resource:", "property:" and "ontology:". * Spacing the delimiters `(`, `{`, `.`, `}`, `)`. * Adding diversity to some filters which test a number (`contains ( ?var, 'number' )` can become `contains ?var = number` * Randomizing the variables names * Shuffling the clauses #### New split "valid" A validation set was randonly extracted from the test set to represent 10% of the whole dataset. ### Supported tasks - Knowledge-based question-answering - Text-to-SPARQL conversion - SPARQL-to-Text conversion ### Languages - English ## Dataset Structure The corpus follows the global architecture from the original version of CSQA (https://amritasaha1812.github.io/CSQA/). There is one directory of the train, dev, and test sets, respectively. Dialogues are stored in separate directories, 100 dialogues per directory. Finally, each dialogue is stored in a JSON file as a list of turns. ### Types of questions Comparison of question types compared to related datasets: | | | [SimpleQuestions](https://huggingface.co/datasets/OrangeInnov/simplequestions-sparqltotext) | [ParaQA](https://huggingface.co/datasets/OrangeInnov/paraqa-sparqltotext) | [LC-QuAD 2.0](https://huggingface.co/datasets/OrangeInnov/lcquad_2.0-sparqltotext) | [CSQA](https://huggingface.co/datasets/OrangeInnov/csqa-sparqltotext) | [WebNLQ-QA](https://huggingface.co/datasets/OrangeInnov/webnlg-qa) | |--------------------------|-----------------|:---------------:|:------:|:-----------:|:----:|:---------:| | **Number of triplets in query** | 1 | ✓ | ✓ | ✓ | ✓ | ✓ | | | 2 | | ✓ | ✓ | ✓ | ✓ | | | More | | | ✓ | ✓ | ✓ | | **Logical connector between triplets** | Conjunction | ✓ | ✓ | ✓ | ✓ | ✓ | | | Disjunction | | | | ✓ | ✓ | | | Exclusion | | | | ✓ | ✓ | | **Topology of the query graph** | Direct | ✓ | ✓ | ✓ | ✓ | ✓ | | | Sibling | | ✓ | ✓ | ✓ | ✓ | | | Chain | | ✓ | ✓ | ✓ | ✓ | | | Mixed | | | ✓ | | ✓ | | | Other | | ✓ | ✓ | ✓ | ✓ | | **Variable typing in the query** | None | ✓ | ✓ | ✓ | ✓ | ✓ | | | Target variable | | ✓ | ✓ | ✓ | ✓ | | | Internal variable | | ✓ | ✓ | ✓ | ✓ | | **Comparisons clauses** | None | ✓ | ✓ | ✓ | ✓ | ✓ | | | String | | | ✓ | | ✓ | | | Number | | | ✓ | ✓ | ✓ | | | Date | | | ✓ | | ✓ | | **Superlative clauses** | No | ✓ | ✓ | ✓ | ✓ | ✓ | | | Yes | | | | ✓ | | | **Answer type** | Entity (open) | ✓ | ✓ | ✓ | ✓ | ✓ | | | Entity (closed) | | | | ✓ | ✓ | | | Number | | | ✓ | ✓ | ✓ | | | Boolean | | ✓ | ✓ | ✓ | ✓ | | **Answer cardinality** | 0 (unanswerable) | | | ✓ | | ✓ | | | 1 | ✓ | ✓ | ✓ | ✓ | ✓ | | | More | | ✓ | ✓ | ✓ | ✓ | | **Number of target variables** | 0 (⇒ ASK verb) | | ✓ | ✓ | ✓ | ✓ | | | 1 | ✓ | ✓ | ✓ | ✓ | ✓ | | | 2 | | | ✓ | | ✓ | | **Dialogue context** | Self-sufficient | ✓ | ✓ | ✓ | ✓ | ✓ | | | Coreference | | | | ✓ | ✓ | | | Ellipsis | | | | ✓ | ✓ | | **Meaning** | Meaningful | ✓ | ✓ | ✓ | ✓ | ✓ | | | Non-sense | | | | | ✓ | ### Data splits Text verbalization is only available for a subset of the test set, referred to as *challenge set*. Other sample only contain dialogues in the form of follow-up sparql queries. | | Train | Validation | Test | | --------------------- | ---------- | ---------- | ---------- | | Questions | 21,000 | 3,000 | 6,000 | | NL question per query | 1 | | Characters per query | 108 (± 36) | | Tokens per question | 10.6 (± 3.9) | ## Additional information ### Related datasets This corpus is part of a set of 5 datasets released for SPARQL-to-Text generation, namely: - Non conversational datasets - [SimpleQuestions](https://huggingface.co/datasets/OrangeInnov/simplequestions-sparqltotext) (from https://github.com/askplatypus/wikidata-simplequestions) - [ParaQA](https://huggingface.co/datasets/OrangeInnov/paraqa-sparqltotext) (from https://github.com/barshana-banerjee/ParaQA) - [LC-QuAD 2.0](https://huggingface.co/datasets/OrangeInnov/lcquad_2.0-sparqltotext) (from http://lc-quad.sda.tech/) - Conversational datasets - [CSQA](https://huggingface.co/datasets/OrangeInnov/csqa-sparqltotext) (from https://amritasaha1812.github.io/CSQA/) - [WebNLQ-QA](https://huggingface.co/datasets/OrangeInnov/webnlg-qa) (derived from https://gitlab.com/shimorina/webnlg-dataset/-/tree/master/release_v3.0) ### Licencing information * Content from original dataset: CC-BY 3.0 * New content: CC BY-SA 4.0 ### Citation information #### This version of the corpus (with normalized SPARQL queries) ```bibtex @inproceedings{lecorve2022sparql2text, title={SPARQL-to-Text Question Generation for Knowledge-Based Conversational Applications}, author={Lecorv\'e, Gw\'enol\'e and Veyret, Morgan and Brabant, Quentin and Rojas-Barahona, Lina M.}, journal={Proceedings of the Conference of the Asia-Pacific Chapter of the Association for Computational Linguistics and the International Joint Conference on Natural Language Processing (AACL-IJCNLP)}, year={2022} } ``` #### Original version ```bibtex @inproceedings{dubey2017lc2, title={LC-QuAD 2.0: A Large Dataset for Complex Question Answering over Wikidata and DBpedia}, author={Dubey, Mohnish and Banerjee, Debayan and Abdelkawi, Abdelrahman and Lehmann, Jens}, booktitle={Proceedings of the 18th International Semantic Web Conference (ISWC)}, year={2019}, organization={Springer} } ```
数据集概述
名称: LC-QuAD 2.0
版本: 特殊版本
任务: SPARQL-to-Text
描述: 该数据集是LC-QuAD 2.0的一个特殊版本,专门为SPARQL-to-Text任务设计。