ASR_Code_Switch
收藏资源简介:
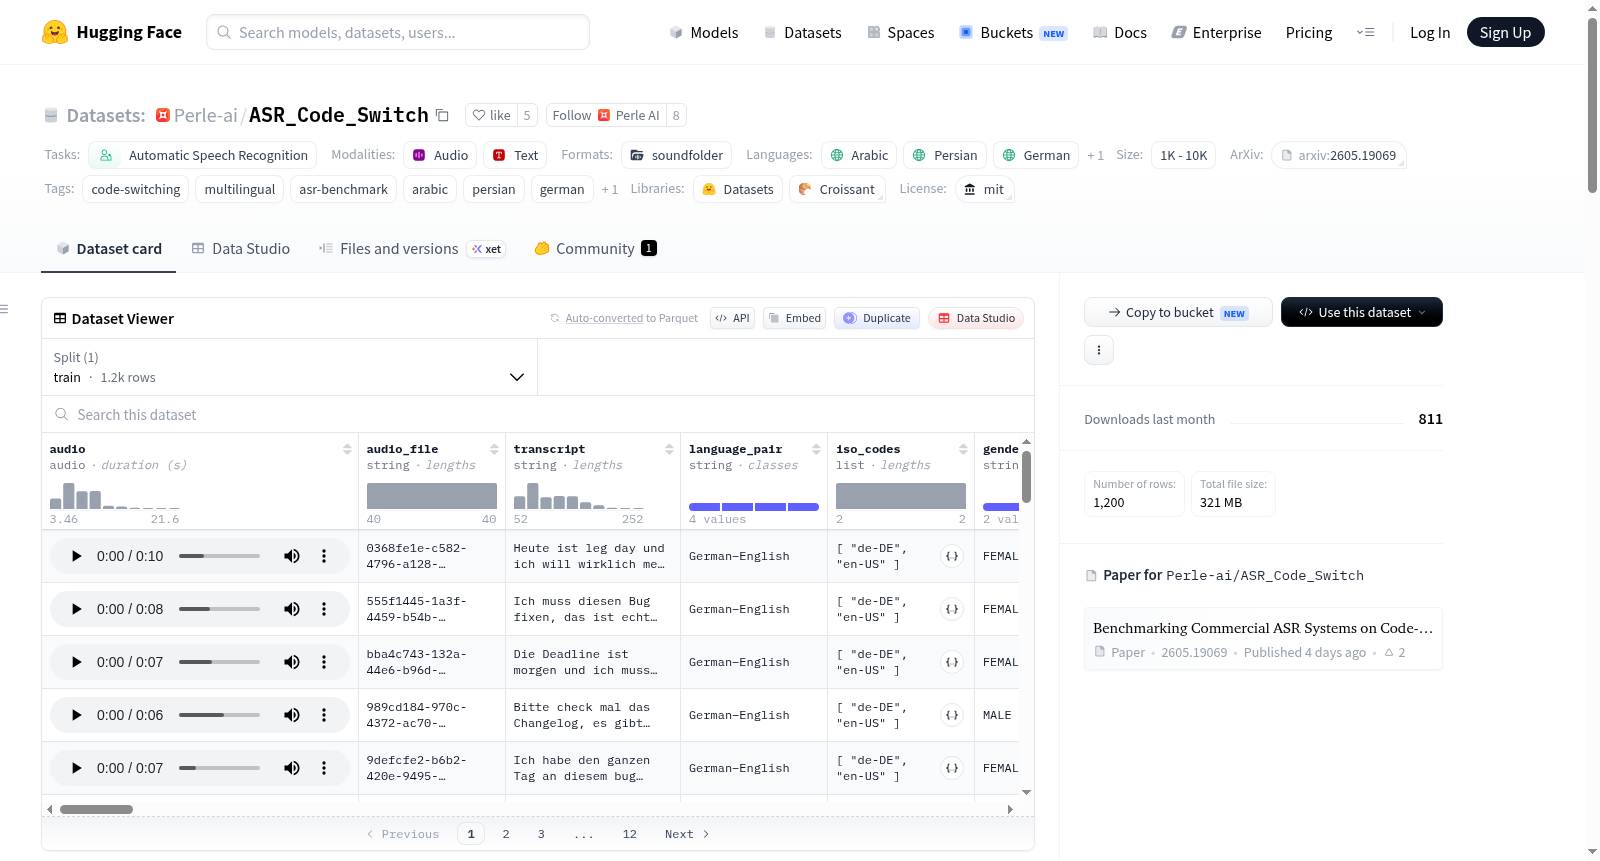
ASR语码转换基准是一个精选的基准数据集,专门设计用于评估商业自动语音识别(ASR)系统在处理包含句内语言转换的多语言语音时的性能。该数据集包含总计1,200个语码转换话语,均匀分布在四个语言对中:埃及阿拉伯语-英语、沙特阿拉伯语(Najdi/Hijazi)-英语、波斯语(Farsi)-英语和德语-英语,每个语言对包含300个样本。数据样本通过一个两阶段的严格流程筛选而来,旨在从源语料库中找出最具挑战性的语码转换实例。第一阶段采用启发式过滤器,根据脚本混合比例、词符交替率、形态混合检测、长度和词汇多样性(类符-形符比)五个结构信号对每个转录文本进行评分。第二阶段则利用LLM集成(GPT-4o和Gemini 1.5 Pro)对候选样本在六个语言学维度上进行独立评分,最终保留每个语言对中集成分数最高的300个样本。数据集中的每个样本包含音频文件(MP3格式)、人工标注的参考转录文本、语言对标签、语言BCP-47代码、说话者性别以及一系列详细的难度评分字段(包括综合启发式难度分数、各维度LLM评分、自由文本难度总结和模型间分歧指标)。该数据集适用于多语言ASR基准测试、语码切换研究以及ASR系统鲁棒性评估等任务。
ASR Code-Switching Benchmark is a curated benchmark dataset specifically designed to evaluate the performance of commercial automatic speech recognition (ASR) systems on multilingual speech containing intra-sentential code-switching. The dataset contains a total of 1,200 code-switched utterances, evenly distributed across four language pairs: Egyptian Arabic-English, Saudi Arabic (Najdi/Hijazi)-English, Persian (Farsi)-English, and German-English, with 300 samples per language pair. The data samples are selected through a rigorous two-stage pipeline aimed at identifying the most challenging instances of code-switching from source corpora. The first stage employs heuristic filters that score each transcription based on five structural signals: script mixing ratio, token alternation rate, morphological mixing detection, length, and lexical diversity (type-token ratio). The second stage leverages an ensemble of LLMs (GPT-4o and Gemini 1.5 Pro) to independently score candidate samples across six linguistic dimensions, ultimately retaining the 300 samples with the highest ensemble scores per language pair. Each sample in the dataset includes an audio file (MP3 format), a human-annotated reference transcription, language pair label, language BCP-47 code, speaker gender, and a set of detailed difficulty scoring fields (including composite heuristic difficulty score, per-dimension LLM scores, free-text difficulty summary, and inter-model disagreement metrics). The dataset is suitable for tasks such as multilingual ASR benchmarking, code-switching research, and ASR system robustness evaluation.