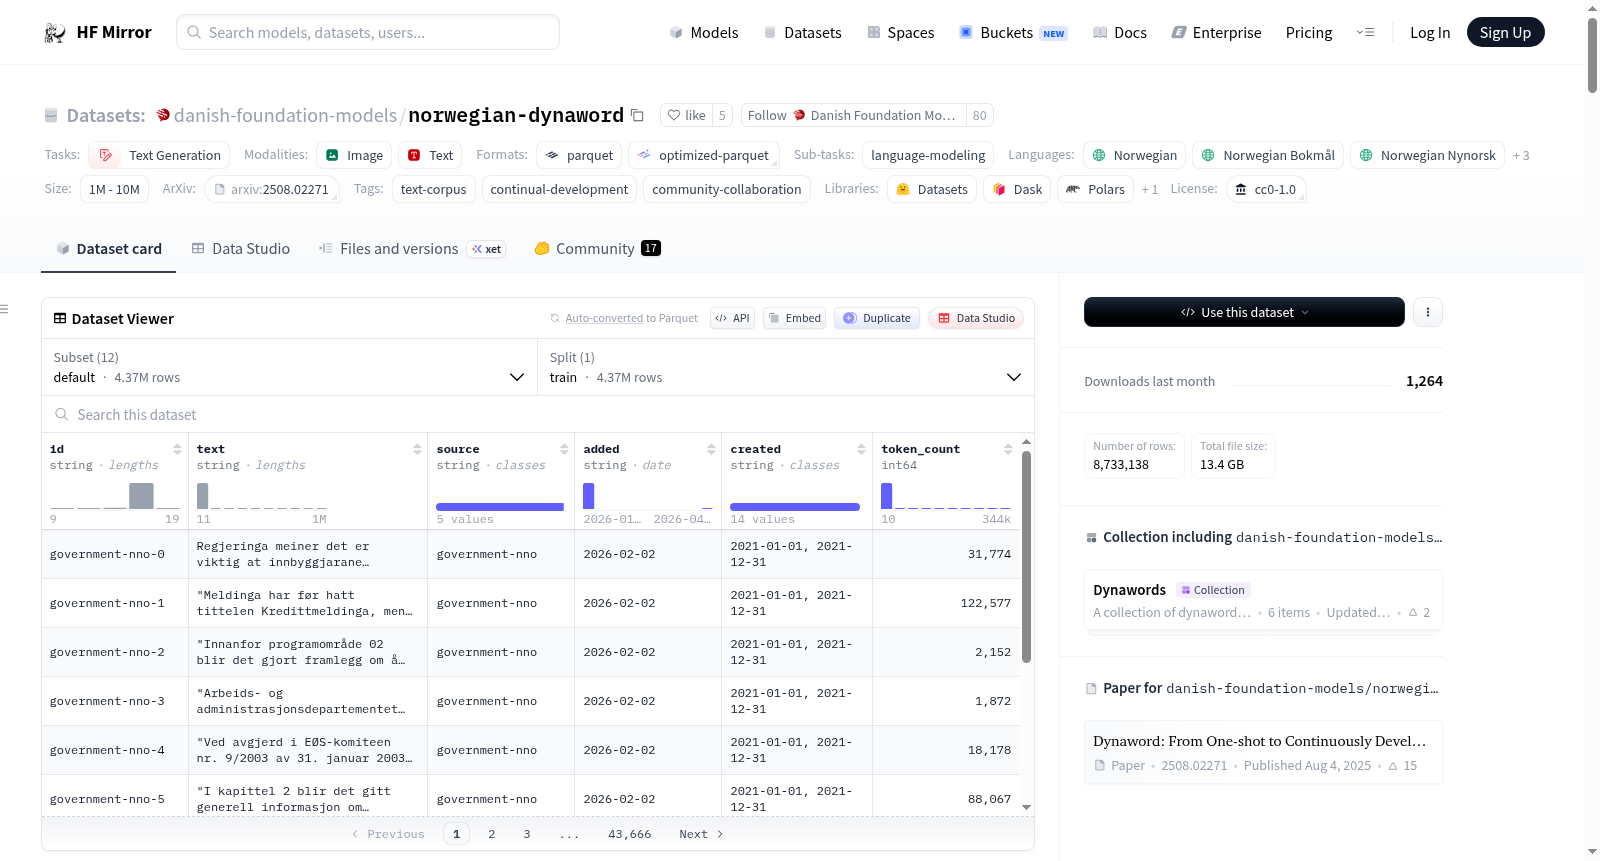
danish-foundation-models/norwegian-dynaword
收藏资源简介:
Norwegian Dynaword是一个包含多种挪威语自由文本的数据集,涵盖了多个领域(如法律、书籍、社交媒体等)。数据集是持续开发的,意味着会不断更新。数据集中的文本都是公开许可的,适合用于训练大型语言模型。数据集包含挪威语的多种变体,如Bokmål和Nynorsk,以及少量的英语和丹麦语。数据集的结构包括多个子集,每个子集都有详细的描述和统计信息。
The Norwegian dynaword is a collection of Norwegian free-form text datasets from various domains. All of the datasets in the Norwegian Dynaword are openly licensed and deemed permissible for training large language models. Norwegian dynaword is continually developed, which means that the dataset will actively be updated as new datasets become available. The dataset includes multiple variants of Norwegian, such as Bokmål and Nynorsk, as well as small amounts of English and Danish. The dataset structure includes multiple subsets, each with detailed descriptions and statistics.