bio-nlp-umass/Synth-SBDH
收藏资源简介:
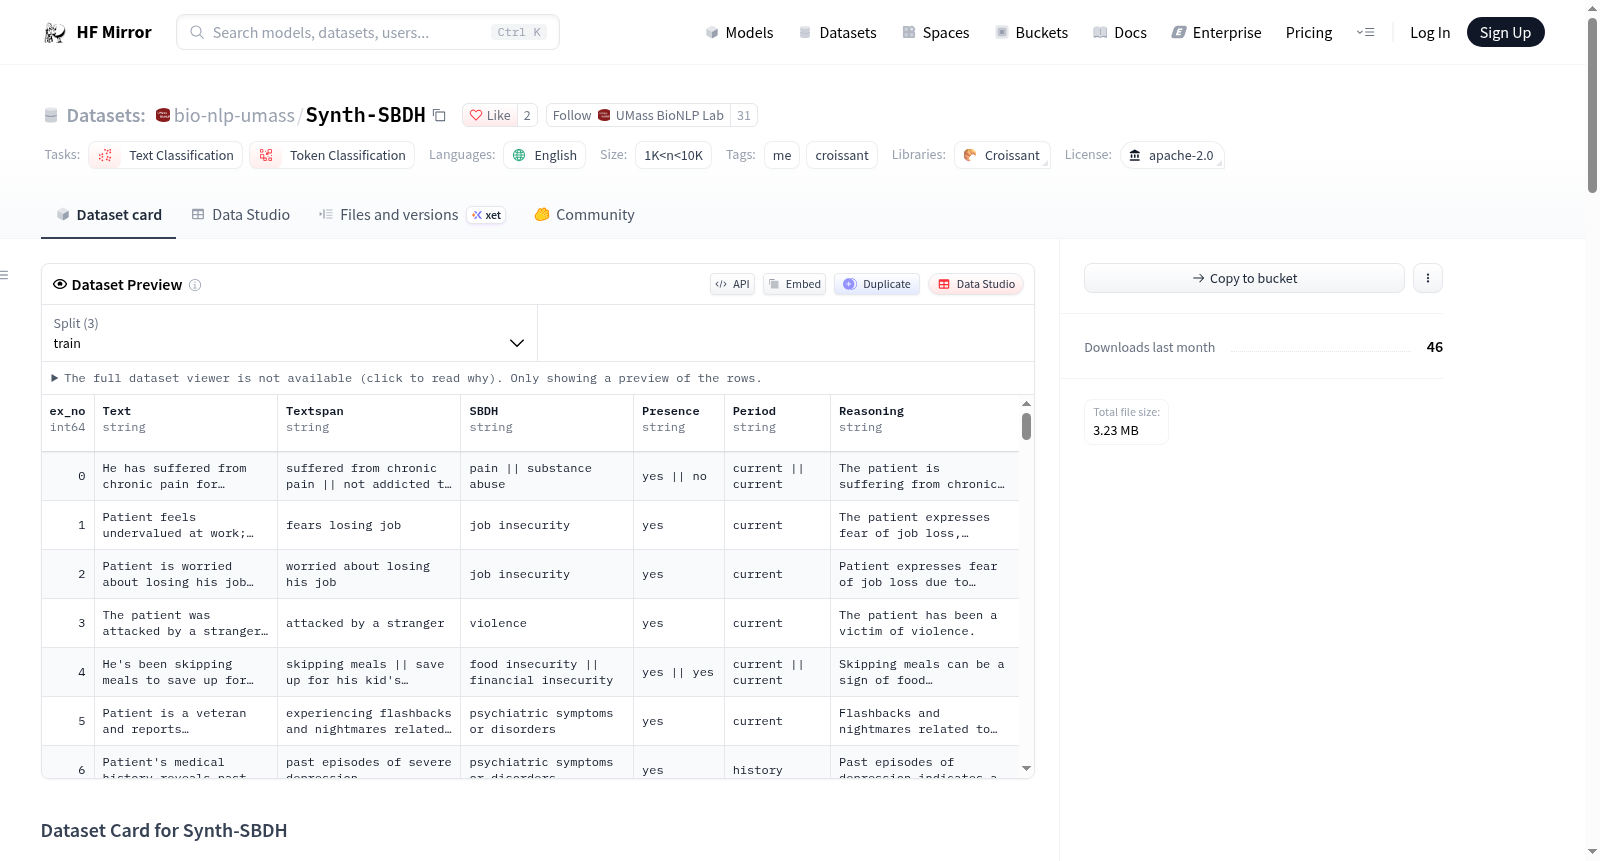
--- license: apache-2.0 task_categories: - text-classification - token-classification language: - en tags: - me - croissant pretty_name: Synth-SBDH size_categories: - 1K<n<10K --- # Dataset Card for Synth-SBDH Synth-SBDH is a collection of 8,767 synthetic examples with annotations for 15 SBDH categories. SBDH annotations include information such as presence, period and annotation rationale. ## Dataset Description Synth-SBDH is a novel synthetic SBDH dataset that mimics EHR notes. - **Repository:** [Codes to reproduce experiments](https://github.com/avipartho/Synth-SBDH) - **Paper:** [Link](https://aclanthology.org/2025.emnlp-main.1418/) - **Point of Contact:** [Avijit Mitra](mailto:avijitmitra@umass.edu) ## Dataset Structure ### Data Instances Some examples from [synth_sbdh_train.csv](synth_sbdh_train.csv) looks as follows. ``` { 'ex_no': 30, 'Text': 'Patient has lost his job due to physical disabilities and is currently living on government financial aid.', 'Textspan': 'lost his job || living on government financial aid', 'SBDH': 'job insecurity || financial insecurity', 'Presence': 'yes || yes', 'Period': 'current || current', 'Reasoning': 'The patient lost his job due to physical issues and this refers to job insecurity. || Reliance on government financial aid signifies financial insecurity.' } { 'ex_no': 31, 'Text': 'Patient was assaulted last year and suffers from PTSD.', 'Textspan': 'assaulted || suffers from PTSD', 'SBDH': 'violence || psychiatric symptoms or disorders', 'Presence': 'yes || yes', 'Period': 'history || current', 'Reasoning': 'Being assaulted is a form of violence. || PTSD is a psychiatric disorder.' } ``` ### Data Fields We release Synth-SBDH as CSV files. Each CSV file has the following fields: - `ex_no`: Unique identifier for an example. - `Text`: Example text sequence, at max a few sentences long. - `Textspan`: Text spans with mentions of SBDH, separated by '||'. - `Reasoning`: Rationales for SBDH annotations, separated by '||'. - `SBDH`: SBDH annotations for text spans in `Textspan`, separated by '||'. - `Presence`: Presence annotations (yes/no) for text spans in `Textspan`, separated by '||'. - `Period`: Period annotations (current/history) for text spans in `Textspan`, separated by '||'. - `Operation` (only for [synth_sbdh_test_reviewed.csv](synth_sbdh_test_reviewed.csv) file): One of the four review operation considered by the human experts - *keep*, *correct*, *discard* or *add*. ### Data Splits The Synth-SBDH dataset has 4 splits: _train_, _val_, _test_, and _test_reviewed_. Below are the statistics for the dataset. | Dataset Split | Number of Examples | Number of Annotations | | ------------- | ------------------ | --------------------- | | Train | 6,136 | 10,022 | | Val | 876 | 1,443 | | Test | 1,755 | 2,904 | | Test (Expert Reviewed) | 1,732 | 3,345 | ## Dataset Creation Details about how the data was created are available in our paper. ## Uses You may directly download and use the dataset using the `datasets` library. ```python from datasets import load_dataset synth_sbdh_dataset = load_dataset("bio-nlp-umass/Synth-SBDH") ``` Or you can also individually download the files and load them using any compatible libray. For example, using `pandas` - ```python import pandas as pd synth_sbdh_df = pd.read_csv('FILE_NAME') ``` ## Citation ``` @inproceedings{mitra-etal-2025-synth, title = "Synth-{SBDH}: A Synthetic Dataset of Social and Behavioral Determinants of Health for Clinical Text", author = "Mitra, Avijit and Yang, Zhichao and Druhl, Emily and Goodwin, Raelene and Yu, Hong", editor = "Christodoulopoulos, Christos and Chakraborty, Tanmoy and Rose, Carolyn and Peng, Violet", booktitle = "Proceedings of the 2025 Conference on Empirical Methods in Natural Language Processing", month = nov, year = "2025", address = "Suzhou, China", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2025.emnlp-main.1418/", doi = "10.18653/v1/2025.emnlp-main.1418", pages = "27899--27935", ISBN = "979-8-89176-332-6", abstract = "Social and behavioral determinants of health (SBDH) play a crucial role in health outcomes and are frequently documented in clinical text. Automatically extracting SBDH information from clinical text relies on publicly available good-quality datasets. However, existing SBDH datasets exhibit substantial limitations in their availability and coverage. In this study, we introduce Synth-SBDH, a novel synthetic dataset with detailed SBDH annotations, encompassing status, temporal information, and rationale across 15 SBDH categories. We showcase the utility of Synth-SBDH on three tasks using real-world clinical datasets from two distinct hospital settings, highlighting its versatility, generalizability, and distillation capabilities. Models trained on Synth-SBDH consistently outperform counterparts with no Synth-SBDH training, achieving up to 63.75{\%} macro-F improvements. Additionally, Synth-SBDH proves effective for rare SBDH categories and under-resource constraints while being substantially cheaper than expert-annotated real-world data. Human evaluation reveals a 71.06{\%} Human-LLM alignment and uncovers areas for future refinements." } ```
Synth-SBDH is a collection of 8,767 synthetic examples with annotations for 15 SBDH categories. SBDH annotations include information such as presence, period and annotation rationale. It is a novel synthetic SBDH dataset that mimics EHR notes.