poolside-laguna-hackathon/protein-ligand-design
收藏资源简介:
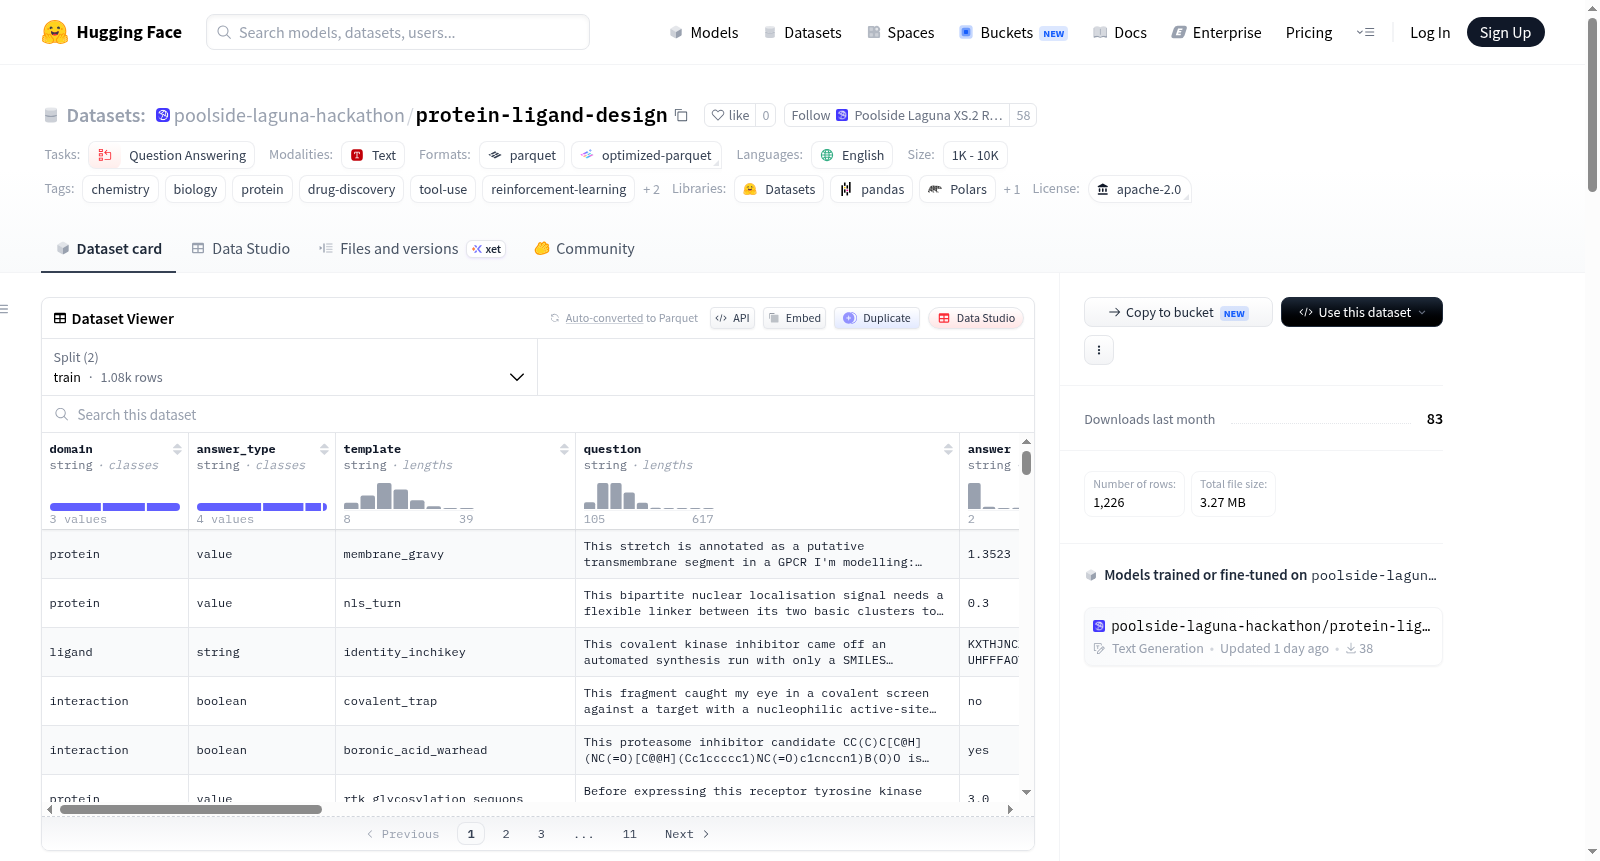
Protein-Ligand Design Gym(蛋白质-配体设计健身房)是一个用于工具使用强化学习的数据集,由Team JAMMY为poolside Laguna Hackathon开发。该数据集旨在教导大型语言模型(LLM)像计算化学家或蛋白质工程师一样推理,通过测量而非猜测来回答关于蛋白质和配体(小分子,如药物)的问题。数据集包含由Claude Opus 4.8生成的问题,这些问题涉及分子或蛋白质的属性(例如,分子量、药物相似性、蛋白质等电点等),并通过RDKit和Biopython等化学/生物学工具进行验证和计算,确保每个答案都有确切的、工具可验证的基础。数据集分为训练和测试分割,存储在parquet文件中,字段包括问题提示、候选分子/蛋白质(以SMILES或序列表示)、参数、工具认证的真实答案、模板、所需工具和推理过程。该环境支持蛋白质-配体相互作用分析,例如匹配子结构或搜索蛋白质基序,适用于药物发现和蛋白质工程任务。
Protein-Ligand Design Gym is a tool-use reinforcement learning dataset created by Team JAMMY for the poolside Laguna Hackathon. It teaches a large language model (LLM) to reason like a computational chemist or protein engineer by measuring, not guessing, in response to questions about proteins and ligands (small molecules, often drugs). The dataset includes questions generated by Claude Opus 4.8, focusing on properties of molecules or proteins (e.g., molecular weight, drug-likeness, protein isoelectric point) that are verified and computed using chemistry/biology tools like RDKit and Biopython, ensuring each answer has an exact, tool-verifiable ground truth. It is split into train and test sets stored in parquet files, with fields such as question prompts, candidate molecules/proteins (as SMILES or sequences), parameters, tool-certified answers, templates, required tools, and reasoning. The environment supports protein-ligand interaction analysis, e.g., substructure matching or protein motif searching, for drug discovery and protein engineering tasks.