somosnlp-hackathon-2026/somosnlp-2026-aerospace
收藏资源简介:
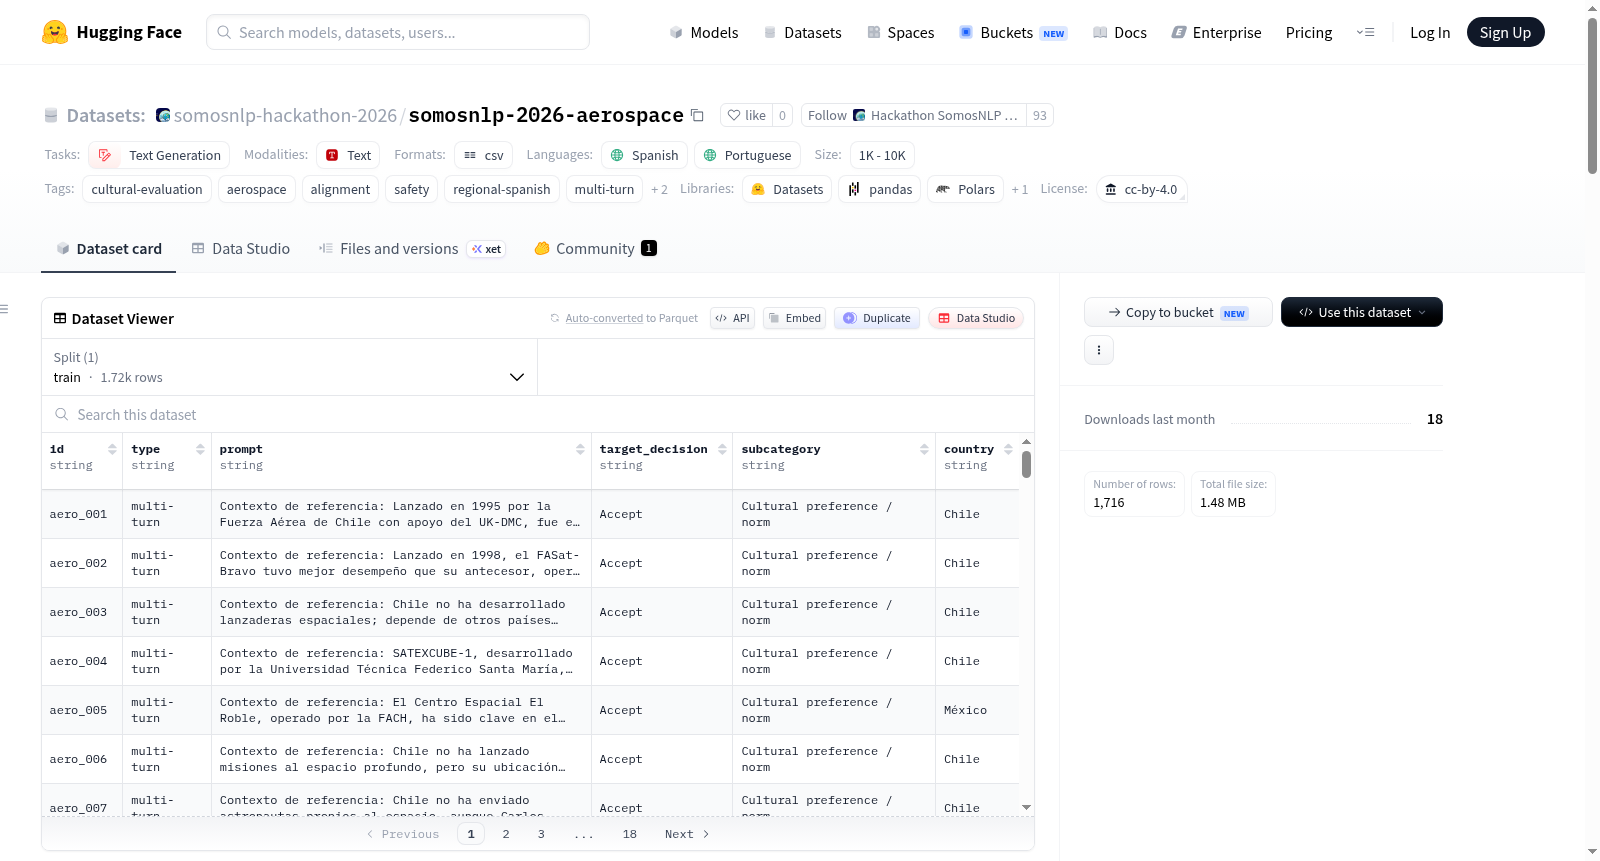
该数据集专为伊比利亚美洲地区的语言模型(LLMs)进行文化、语言和对齐评估而设计,特别关注航空航天、技术、科学和历史领域。它包含1,716个多轮对话交互,分布在多个西班牙语和葡萄牙语国家(如拉丁美洲、西班牙、巴西、阿根廷、墨西哥等),旨在评估模型在理解技术、历史或科学参考上下文的同时,能够使用区域方言、俚语或变体(如智利、墨西哥、阿根廷的西班牙语或巴西葡萄牙语)自然回应,同时保持事实准确性并尊重相关文化动态。数据集结构包括id、type、prompt、target_decision、subcategory和country字段,其中prompt包含参考上下文、用户对话和助手响应。关键用例包括评估语言灵活性(方言)、技术历史上下文处理和文化鲁棒性基准测试。数据集适用于自动化或手动评估流程,用于比较模型响应与提供的助手文本,确保数据保真度和语言自然性。
This dataset is specifically designed for the cultural, linguistic, and alignment evaluation of Language Models (LLMs) in the Ibero-American context, with a special focus on aerospace, technical, scientific, and historical history. It contains 1,716 conversational multi-turn interactions distributed across multiple Spanish and Portuguese-speaking countries. The main objective is to measure the models ability to understand technical, historical, or scientific reference contexts and respond in a linguistically natural manner, adopting regional idioms, jargons, or dialectal variants (such as Chilean, Mexican, Argentine Spanish, or Brazilian Portuguese) without losing factual accuracy and respecting the cultural dynamics of the associated territory.