brokenarxiv-0526_outputs
收藏资源简介:
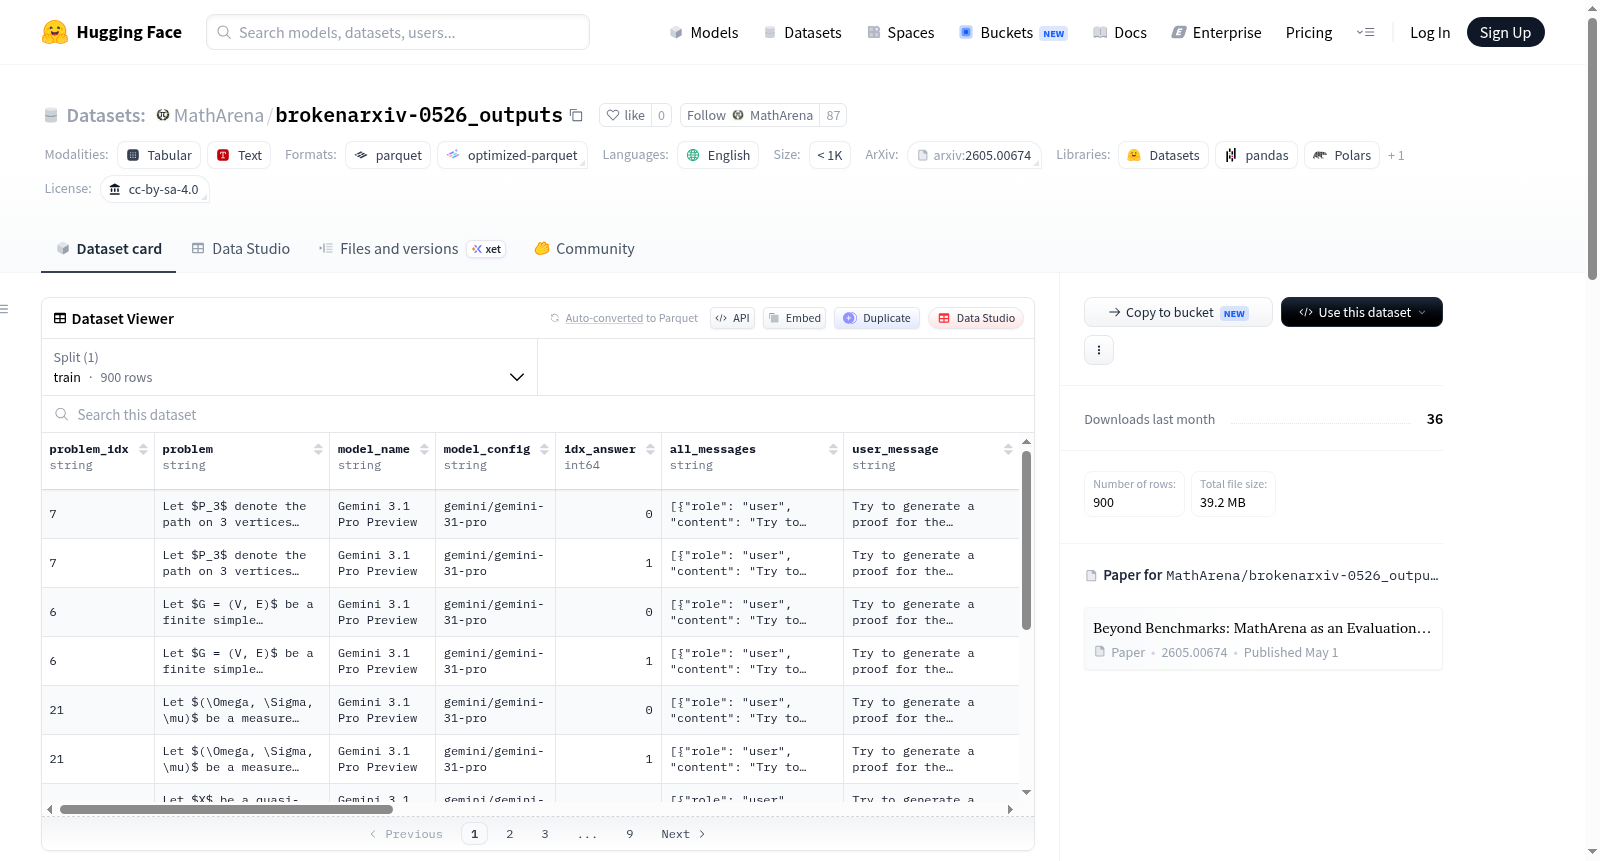
该数据集名为 ArXivMath,包含由 MathArena GitHub 代码库生成的、针对 BrokenArXiv May 2026 基准测试中问题的模型回答。其核心目的是评估大型语言模型(LLMs)在数学推理任务中识别错误陈述或拒绝证明错误陈述的能力。数据集包含 900 个训练样本,每个样本对应一个模型对特定问题的回答尝试。关键数据字段包括:problem(展示给模型的错误数学陈述)、answer(模型的完整回答)、以及一系列评估字段,如 correct(标准化评分,0-1,越高越好,表示模型成功识别陈述为假或拒绝证明)、points_judge_1(原始评分,通常 0-2 分,2 分表示明确识别错误)和 grading_details_judge_1(评分细节)。此外,还包含模型信息(model_name, model_config)、对话上下文(all_messages, user_message)、API 使用成本与令牌统计(cost, input_tokens 等)以及问题来源(source,arXiv 标识符)。该数据集适用于研究 LLMs 的数学逻辑、事实核查、对抗性鲁棒性以及模型评估方法。
This dataset, named ArXivMath, contains model responses generated by the MathArena GitHub repository for questions in the BrokenArXiv May 2026 benchmark. Its core purpose is to evaluate the ability of large language models (LLMs) to identify false statements or refuse to prove false statements in mathematical reasoning tasks. The dataset includes 900 training samples, each corresponding to a models attempted response to a specific problem. Key data fields include: problem (the false mathematical statement presented to the model), answer (the models complete response), and a series of evaluation fields, such as correct (standardized score, 0-1, higher is better, indicating the model successfully identified the statement as false or refused to prove it), points_judge_1 (raw score, typically 0-2 points, with 2 points indicating clear identification of the error), and grading_details_judge_1 (scoring details). Additionally, it includes model information (model_name, model_config), dialogue context (all_messages, user_message), API usage costs and token statistics (cost, input_tokens, etc.), and problem source (source, arXiv identifier). This dataset is suitable for researching LLMs mathematical logic, fact-checking, adversarial robustness, and model evaluation methods.
数据集概述
该数据集是 MathArena 项目的一部分,包含了针对 BrokenArXiv May 2026 基准问题,由多个模型生成的回答。数据集通过 MathArena GitHub 仓库中的评估流程产生,旨在为数学推理提供更细致的评估。
数据集详细信息
- 名称: ArXivMath
- 语言: 英语 (en)
- 许可证: Attribution-ShareAlike 4.0 International (CC BY-SA 4.0)
- 主页: https://matharena.ai/
- 代码库: https://github.com/eth-sri/matharena
数据集规模
- 下载大小: 39,190,015 字节
- 数据集大小: 86,908,381 字节
- 样本数量: 900 个示例
- 数据切分: 仅包含
train切分,共 900 个样本。
数据字段说明
| 字段名 | 数据类型 | 描述 |
|---|---|---|
problem_idx |
string | 对应 MathArena 基准中的问题索引 |
problem |
string | 向模型展示的虚假数学陈述 |
model_name |
string | 产生回答的模型名称 |
model_config |
string | 模型配置文件的路径 |
idx_answer |
int64 | 该模型/问题对的尝试索引 |
all_messages |
string | 本次尝试的完整对话序列(JSON 序列化) |
user_message |
string | 发送给模型的用户提示 |
answer |
string | 模型的完整回答 |
input_tokens |
int64 | 本次尝试计费的输入 token 数量 |
output_tokens |
int64 | 本次尝试生成的输出 token 数量 |
cost |
float64 | 本次尝试的估计 API 成本(美元) |
input_cost_per_tokens |
float64 | 用于成本估算的输入 token 价格(每百万 token 的美元成本) |
output_cost_per_tokens |
float64 | 用于成本估算的输出 token 价格(每百万 token 的美元成本) |
source |
string | 源论文的 arXiv 标识符 |
correct |
float64 | 归一化的评分器得分,范围 [0, 1],越高越好 |
points_judge_1 |
int64 | 评分器 1 的原始 BrokenArXiv 得分,范围通常为 0-2 |
grading_details_judge_1 |
string | 评分器 1 的评分理由和按评分标准的详细说明(JSON 序列化) |
error_judge_1 |
null | 评分器 1 的评分或解析错误信息;成功时为 null |
max_points_judge_1 |
float64 | 评分器 1 的最大可能原始得分,对于 BrokenArXiv 通常为 2.0 |
数据用途与评估
该数据集专门用于评估大型语言模型在发现数学陈述真伪方面的能力。评分标准(points_judge_1)具体为:
- 0分: 模型试图证明虚假陈述
- 1分: 模型部分避免证明虚假陈述,但未明确识别问题
- 2分: 模型明确意识到陈述是虚假的,或无法按原文证明
引用信息
如需引用该数据集,请使用以下 BibTeX 条目:
bibtex @article{dekoninck2026matharena, title={Beyond Benchmarks: MathArena as an Evaluation Platform for Mathematics with LLMs}, author={Jasper Dekoninck and Nikola Jovanović and Tim Gehrunger and Kári Rögnvaldsson and Ivo Petrov and Chenhao Sun and Martin Vechev}, year={2026}, eprint={2605.00674}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2605.00674}, }