MMAU
收藏资源简介:
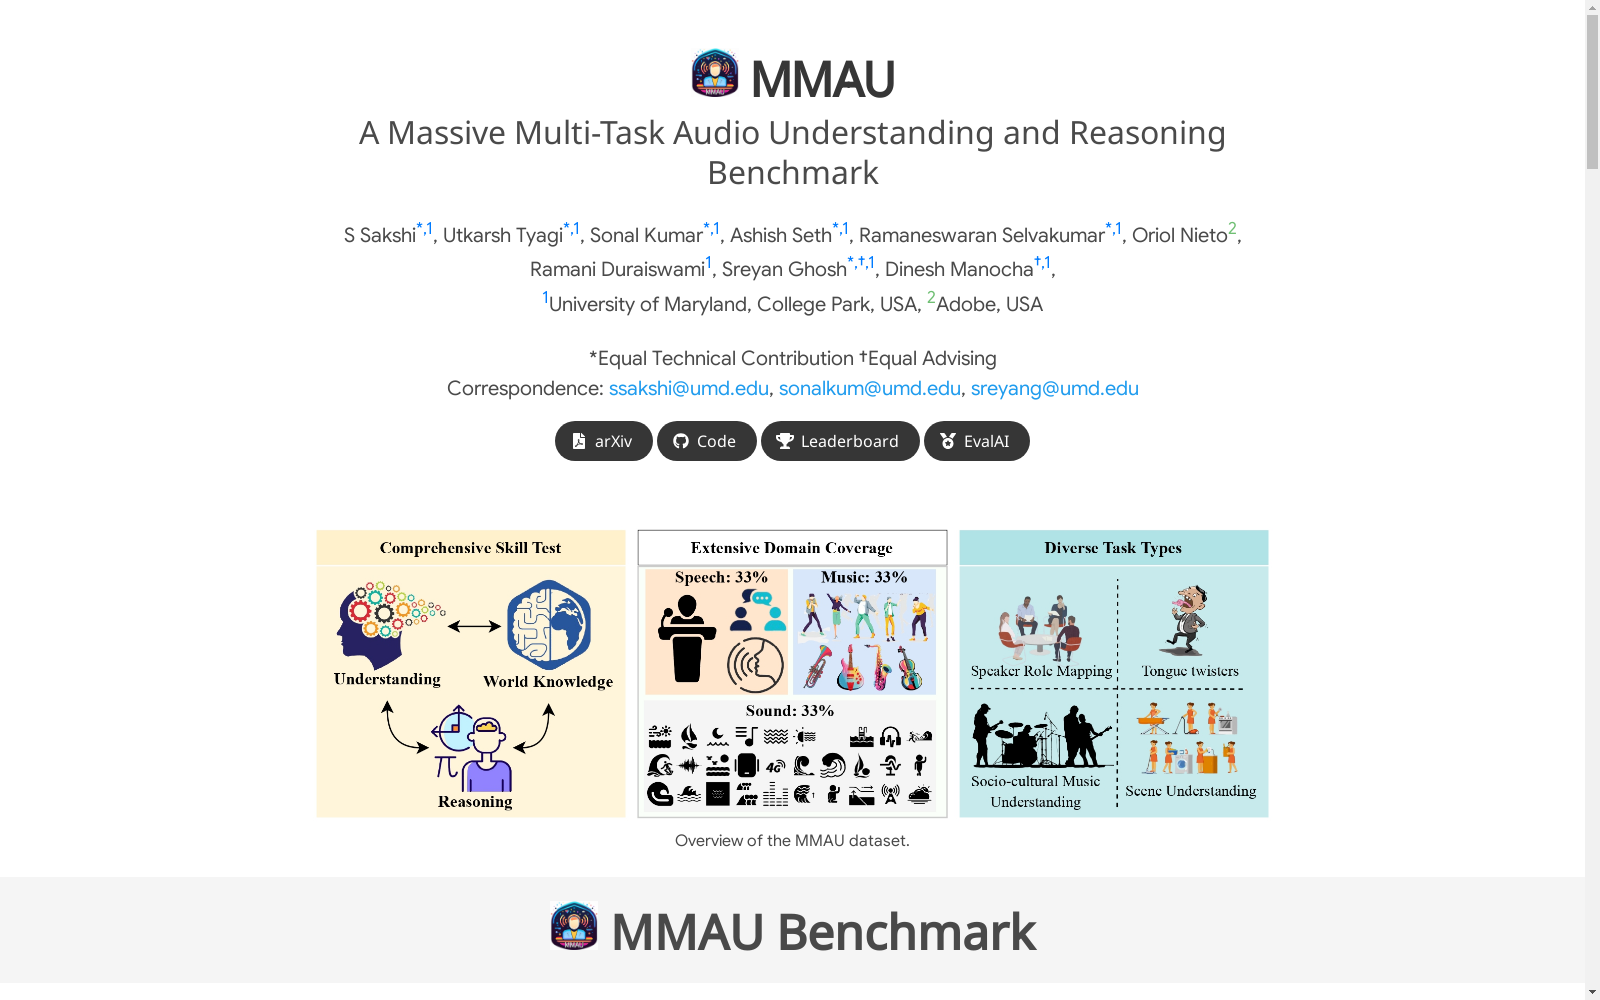
MMAU数据集由马里兰大学创建,是一个大规模的多任务音频理解和推理基准,包含10,000条精心策划的音频片段,涵盖语音、环境声音和音乐。数据集内容丰富,包含27种不同的技能测试,旨在评估模型在复杂音频任务中的表现。数据集的创建过程严格遵循7步管道,确保数据质量和任务的相关性。MMAU主要应用于评估和推动多模态音频理解模型的发展,旨在解决复杂音频任务中的理解和推理问题。
The MMAU Dataset was developed by the University of Maryland. It is a large-scale multi-task audio understanding and reasoning benchmark comprising 10,000 carefully curated audio clips spanning speech, environmental sounds and music. Featuring rich content, the dataset includes 27 distinct skill tests designed to evaluate models' performance on complex audio tasks. Its development follows a rigorous 7-step pipeline to guarantee data quality and task relevance. MMAU is primarily utilized to evaluate and advance the development of multimodal audio understanding models, aiming to resolve comprehension and reasoning challenges in complex audio tasks.