media-metadata-listennotes-podcasts
收藏资源简介:
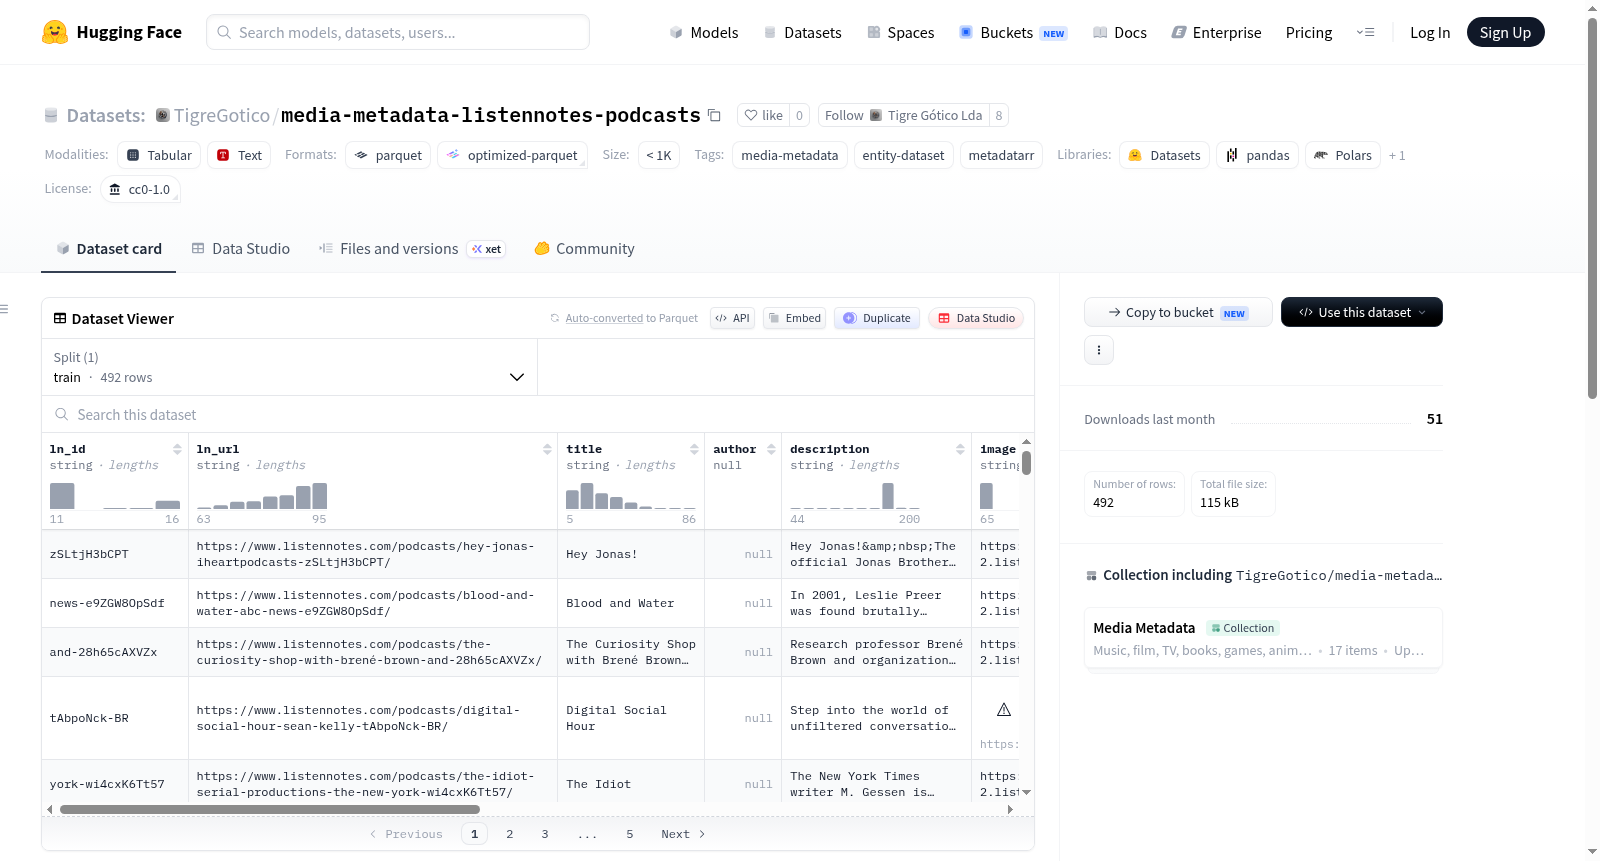
TigreGotico/media-metadata-listennotes-podcasts 是一个媒体元数据实体数据集,专门包含从ListenNotes播客平台抓取的播客节目信息。数据集由492条记录组成,每条记录代表一个播客实体,包含13个结构化字段:播客在ListenNotes的唯一标识符(ln_id)、原始URL(ln_url)、标题(title)、作者(author)、描述(description)、封面图片链接(image)、使用语言(language)、所属流派(genres)、总集数(episode_count)、收听评分(listen_score)、全球排名(global_rank)、官方网站(website)以及固定的实体类型标识(entity_type)。该数据集使用CC0 1.0公共领域贡献许可证,数据通过metadatarr项目中的`listennotes_podcasts.py`抓取脚本生成。数据集适用于媒体内容分析、播客推荐系统、多语言实体信息挖掘以及元数据标准化研究等任务。
TigreGotico/media-metadata-listennotes-podcasts is a media metadata entity dataset specifically containing podcast program information scraped from the ListenNotes podcast platform. The dataset consists of 492 records, each representing a podcast entity with 13 structured fields: the unique identifier on ListenNotes (ln_id), original URL (ln_url), title, author, description, cover image link (image), language used, genres, total episode count (episode_count), listen score, global rank, official website, and a fixed entity type identifier (entity_type). The dataset is licensed under CC0 1.0 Public Domain Dedication, and the data is generated via the `listennotes_podcasts.py` scraping script in the metadatarr project. It is suitable for tasks such as media content analysis, podcast recommendation systems, multilingual entity information mining, and metadata standardization research.