media-metadata-podcastindex-podcasts
收藏资源简介:
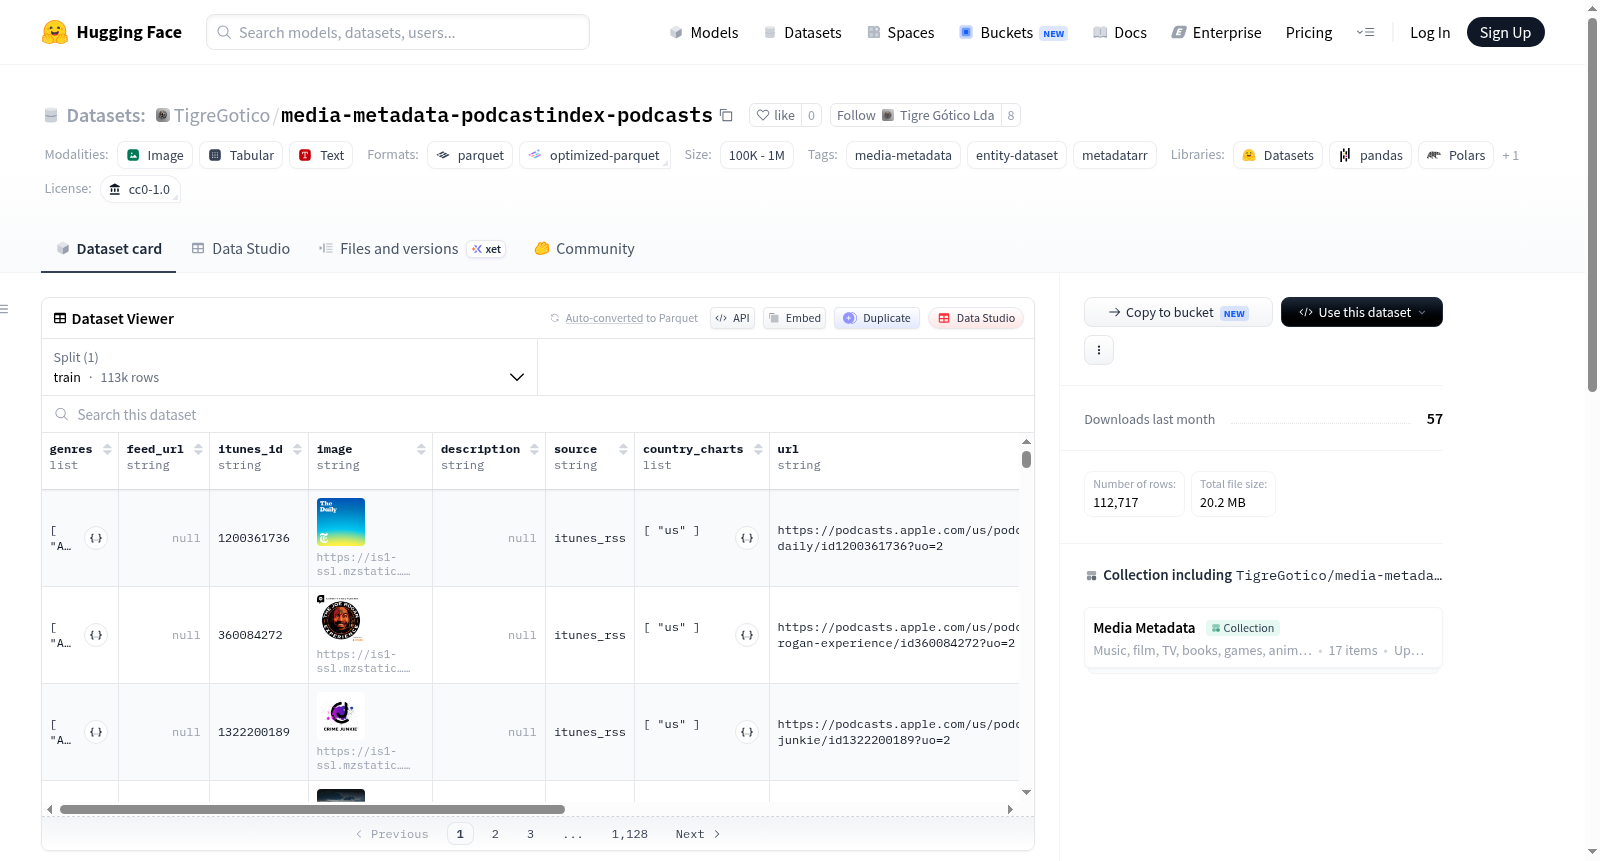
该数据集是一个播客元数据实体数据集,由 metadatarr 项目的 `podcastindex_podcasts` 爬虫从 PodcastIndex 抓取并整理而成。数据集包含 112,717 条记录,每条记录代表一个播客实体,涵盖了丰富的元数据字段,包括播客的 iTunes ID、标题、作者、封面图像链接、所属流派、播客主页 URL、描述文本、语言、剧集数量、是否包含成人内容标记、Feed URL、国家排行榜信息、数据来源以及实体类型。该数据集适用于媒体内容分析、播客推荐系统、自然语言处理(如基于描述的文本分类或摘要)以及跨平台实体链接等任务。数据以结构化形式提供,遵循 CC0 1.0 公共领域贡献许可。
This dataset is a podcast metadata entity dataset, scraped and curated from PodcastIndex by the `podcastindex_podcasts` crawler from the metadatarr project. It contains 112,717 records, where each entry represents a single podcast entity and includes a comprehensive set of metadata fields: the podcast's iTunes ID, title, author, cover image link, genre, podcast homepage URL, description text, language, number of episodes, adult content flag, Feed URL, country ranking information, data source, and entity type. This dataset is suitable for tasks such as media content analysis, podcast recommendation systems, natural language processing (e.g., description-based text classification or summarization), and cross-platform entity linking. The data is provided in a structured format and is licensed under CC0 1.0 Public Domain Dedication.