africa-corpus
收藏资源简介:
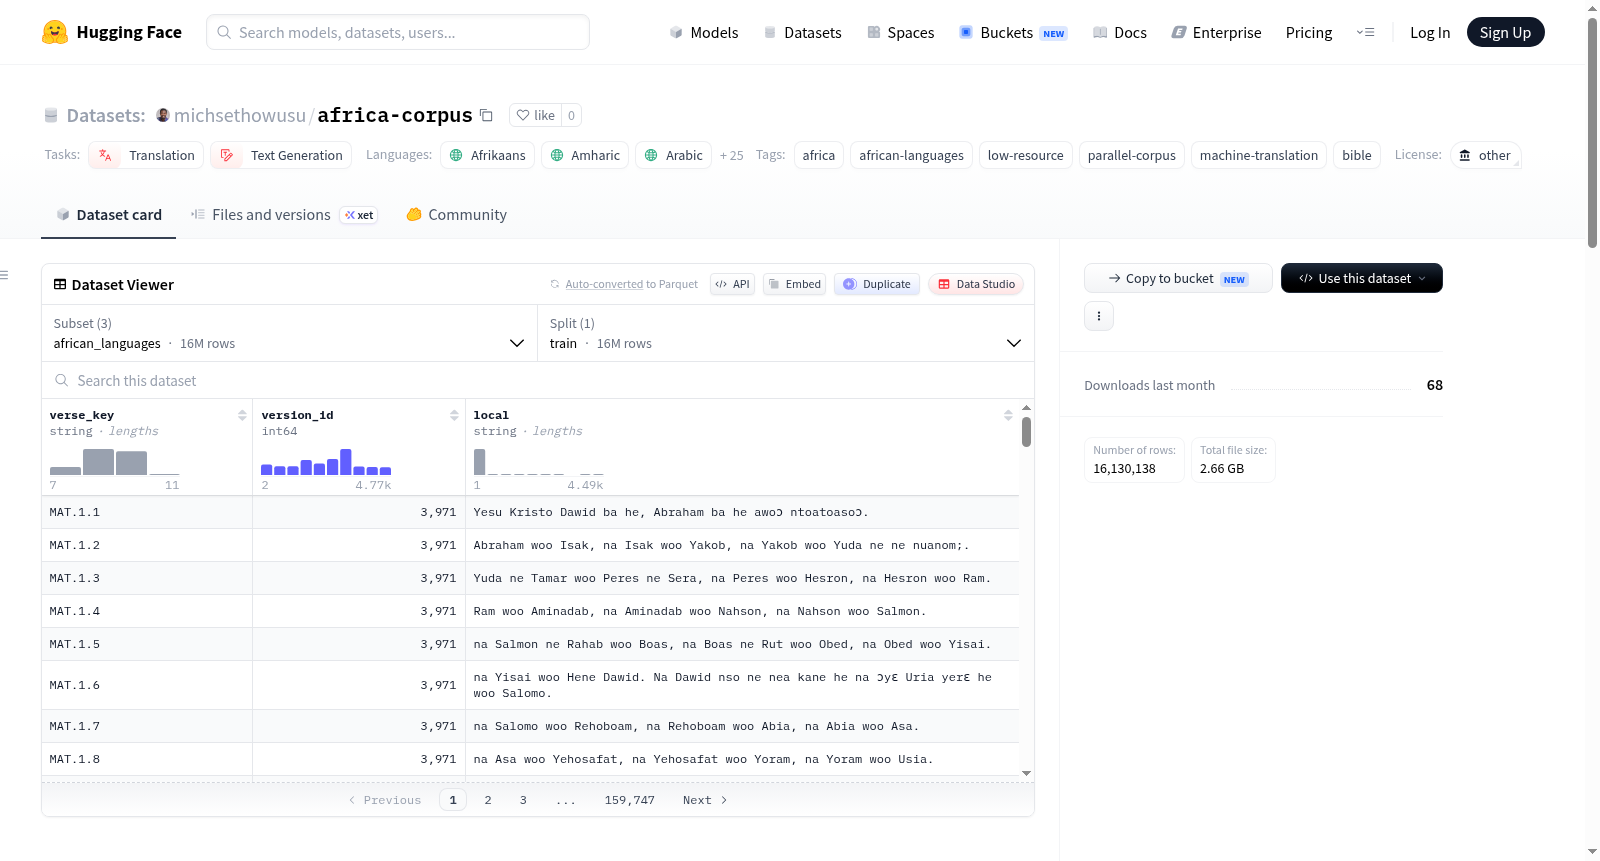
Africa Corpus是一个大规模多语言平行语料库,旨在为机器翻译和文本生成等任务提供高质量的训练数据。该数据集基于公共圣经翻译构建,核心特点是经文级别的精确对齐。它覆盖了792种以上的非洲语言(涵盖尼日尔-刚果语系、亚非语系、尼罗-撒哈拉语系、科伊桑语系和南岛语系等主要非洲语言家族),以及英语、法语、阿拉伯语、中文、葡萄牙语等多种世界语言。所有语言通过共享的经文键(如JHN.3.16)对齐,支持任意两种语言组合成平行语料对(如非洲语言↔英语、非洲语言↔非洲语言、非洲语言↔其他语言),也可用于构建单语料库。数据集包含约1,090个圣经版本,总计约1,600万条经文记录。数据以CSV文件格式组织,分为三个配置:african_languages配置包含各非洲语言的经文文本(列:verse_key, version_id, local);english配置包含英语参考文本(列:verse_key, eng);reference_caches配置包含其他参考语言的缓存文本(列:verse_key, version_id, lang_code, text)。主要适用于低资源语言机器翻译、多语言NLP模型训练、语言学研究等场景。数据来源于YouVersion的圣经翻译,使用时需遵守其服务条款。
The Africa Corpus is a large-scale multilingual parallel corpus designed to provide high-quality training data for tasks such as machine translation and text generation. It is built on public Bible translations, with a core feature of verse-level alignment. The dataset covers over 792 African languages (spanning major language families including Niger-Congo, Afro-Asiatic, Nilo-Saharan, Khoisan, and Austronesian) as well as world languages such as English, French, Arabic, Chinese, and Portuguese. All languages are precisely aligned via shared verse keys (e.g., JHN.3.16), enabling easy combination of any two languages into parallel corpus pairs (e.g., African language ↔ English, African language ↔ African language, African language ↔ other languages) and also supporting the construction of monolingual corpora. The dataset contains approximately 1,090 Bible versions, totaling about 16 million verse records. Data is organized in CSV format with three configurations: the african_languages configuration includes verse texts in African languages (columns: verse_key, version_id, local); the english configuration includes English reference texts (columns: verse_key, eng); and the reference_caches configuration includes cached texts for other reference languages (columns: verse_key, version_id, lang_code, text). It is primarily suitable for low-resource language machine translation, multilingual NLP model training, and linguistic research. The data originates from YouVersions Bible translations, and users must comply with its terms of service.
数据集概述:Africa Corpus
Africa Corpus 是一个面向非洲语言的端到端对齐语料库,包含 792+ 种非洲语言及多种世界语言,支持构建平行语料与单语语料。所有语言均基于共享的 verse_key(如 JHN.3.16)对齐,因此任意两种语言均可拼接为平行语料。
主要特性
- 多语言对齐:除非洲语言外,还提供英语、法语、阿拉伯语、中文、葡萄牙语作为平行目标语言。
- 语料组合灵活:
- 非洲语言 ↔ 英语(默认配对)
- 非洲语言 ↔ 非洲语言(如Twi ↔ Yoruba)
- 非洲语言 ↔ 其他世界语言
- 任意单一语言的单语语料
- 数据格式:基于CSV文件,每行包含
verse_key、version_id、local(或eng、text等)列。
数据规模与覆盖
- 圣经版本:1,090 个
- 语言覆盖:792+ 种非洲语言,涵盖主要语系(尼日尔-刚果语系、亚非语系、尼罗-撒哈拉语系、科伊桑语系、南岛语系(马达加斯加))。
- 总记录数:约 1,600 万节经文。
数据结构
数据集分为三个视图配置,分别对应不同文件组:
| 配置 | 文件模式 | 列 |
|---|---|---|
african_languages |
{Language}_{code}_v{id}.csv |
verse_key, version_id, local |
english |
english_cache.csv |
verse_key, eng |
reference_caches |
reference_caches/{Language}_{code}_v{id}.csv |
verse_key, version_id, lang_code, text |
所有文件通过 verse_key 列对齐,文件名本身编码了语言名称、代码和圣经版本ID。
使用方法
推荐使用专用的 Africa Corpus Builder 库(GitHub仓库:michsethowusu/africa-corpus-builder)来下载和拼接所需数据:
bash pip install huggingface_hub git clone https://github.com/michsethowusu/africa-corpus-builder.git cd africa-corpus-builder
示例:Swahili ↔ English
python africa_corpus.py --source swc
示例:Twi ↔ Yoruba,随机抽取 5,000 对
python africa_corpus.py --source twi --target yor --limit 5000 --sample
示例:单语 Hausa
python africa_corpus.py --source hau --monolingual
列出所有可用语言
python africa_corpus.py --list
也可直接加载原始CSV文件:
python from huggingface_hub import hf_hub_download import pandas as pd
path = hf_hub_download("michsethowusu/africa-corpus", "Swahili_swc_v74.csv", repo_type="dataset") df = pd.read_csv(path)
许可与来源
- 文本来源:公共领域的 圣经译本,来自 YouVersion。使用时需遵守 YouVersion 的服务条款。
- 代码许可:MIT 许可证(详见 GitHub 仓库)。
- 引用建议:若在研究中使用了本数据,请引用所涉及的圣经翻译来源。