Global-MMLU
收藏资源简介:
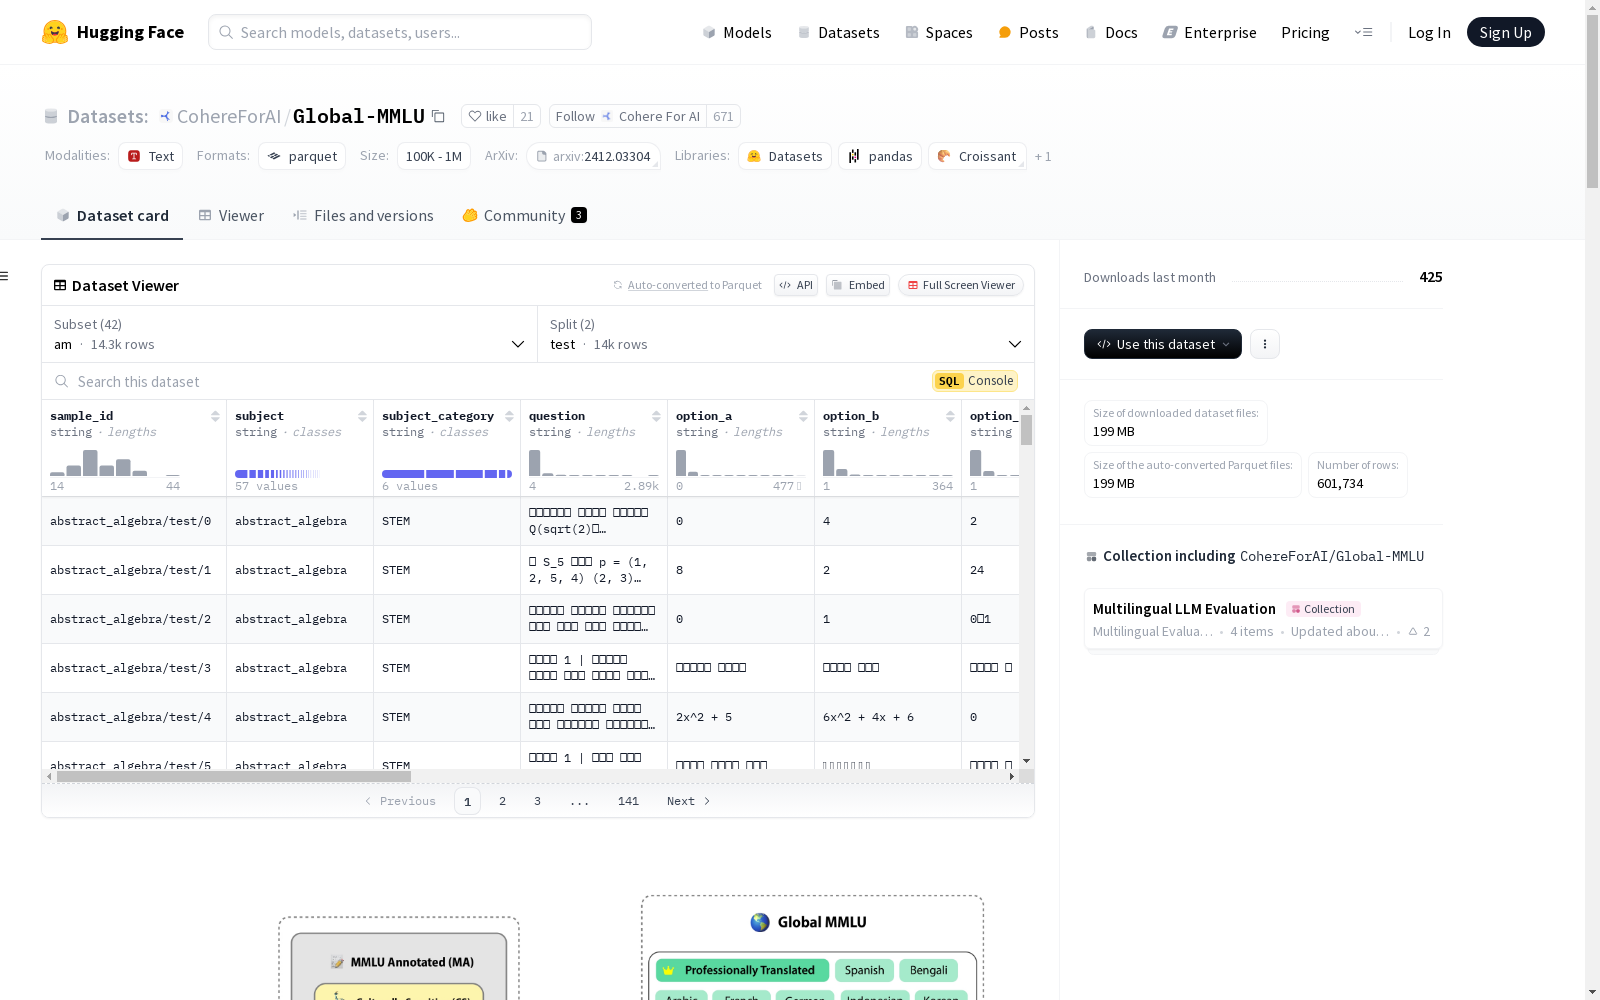
Global-MMLU数据集由Cohere For AI创建,旨在解决多语言评估中的文化和语言偏见问题。该数据集包含2850个样本,涵盖42种语言,包括英语。数据集的创建过程包括专业翻译、社区翻译和机器翻译的结合,并通过专业注释者进行质量验证和偏见评估。Global-MMLU数据集特别标注了文化和地理敏感问题,以更全面地评估模型的多语言性能。该数据集的应用领域主要集中在多语言生成模型的评估和改进,旨在解决现有数据集在文化和地理知识上的偏见问题。
The Global-MMLU dataset, developed by Cohere For AI, is designed to address cultural and linguistic biases in multilingual evaluation. It comprises 2,850 samples across 42 languages, including English. The dataset's creation integrates professional translation, community-based translation, and machine translation, with quality validation and bias assessment conducted by professional annotators. Notably, Global-MMLU explicitly labels culturally and geographically sensitive questions to enable a more comprehensive evaluation of a model's multilingual performance. The primary application scenarios of this dataset focus on the evaluation and improvement of multilingual generative models, aiming to resolve the cultural and geographic knowledge biases present in existing datasets.