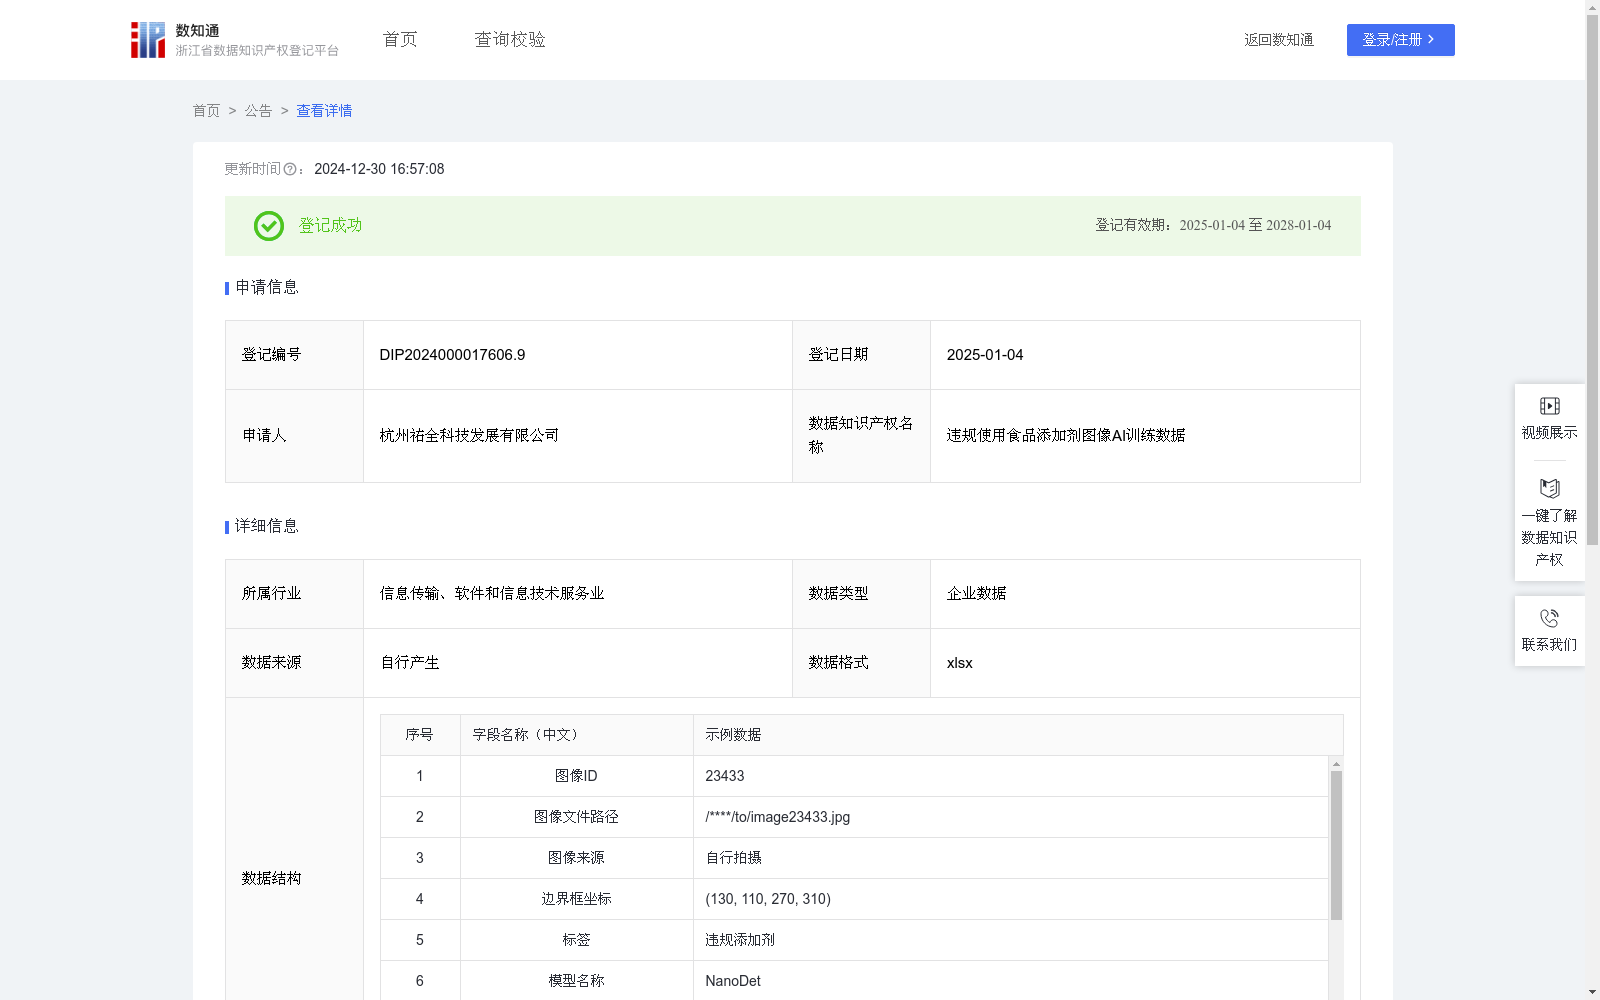
违规使用食品添加剂图像AI训练数据
收藏资源简介:
本数据的价值在于其为构建精准、高效的违规使用食品添加剂识别AI模型提供了丰富且具针对性的信息基础。这些数据覆盖了食品加工过程中违规使用食品添加剂的关键特征,包括非法添加剂种类、超量使用、未按规定程序添加等,使AI模型能够深入学习并掌握这些因素对食品安全的影响。通过利用这些数据进行训练,AI模型能够更加准确地识别出食品加工中是否违反了食品添加剂使用规定,进而在实际应用中提供更加自动化和客观的食品添加剂使用监测。这一训练过程的核心价值在于提升AI模型的识别精确度和适应能力,确保其在面对现实食品加工和生产环境中的复杂多变情况时,能够做出更加符合食品安全管理需求的决策。1.数据采集:原始图像数据来源于自行拍摄或算法生成,确保数据来源多样化和合法性,并对原始图像的ID、文件路径进行记录。 2.数据预处理与标注:根据自身项目需求和模型要求,将违规使用食品添加剂图像数据分类成训练集和测试集,并对训练集进行标注,形成边界框坐标及对应的标签。 3.模型选择与初始化:选择NanoDet预训练模型,并初始化模型参数,设置合理的超参数,如学习率、批量大小、冗余度等,以优化模型的训练过程。 4.模型训练:使用TensorFlow深度学习框架加载和初始化模型,然后将准备好的训练集输入到模型中进行训练。在训练过程中,模型会不断调整权重,以最小化预测框与真实框之间的差值,从而提高检测的准确性,训练通常需要多个epoch(迭代次数)。 5.模型评估:在训练完成后,使用测试集对模型进行评估。计算模型在不同场景下的精度、召回率、F1分数等性能指标,确保模型的准确性和鲁棒性。 6.模型部署与实时性能评估:将最终训练、测试后得到的模型应用到具体的项目中。在实际应用中,评估模型的实时性能(即准确率),确保满足项目需求。
The value of this dataset lies in providing a rich and targeted information foundation for building accurate and efficient AI models for identifying illegal use of food additives. This dataset covers the key characteristics of illegal food additive use during food processing, including types of illegal additives, excessive usage, non-compliant addition procedures, etc., enabling AI models to deeply learn and grasp the impact of these factors on food safety. By training with this dataset, AI models can more accurately identify whether food additive use regulations are violated during food processing, thereby providing more automated and objective monitoring of food additive usage in practical applications. The core value of this training process is to improve the recognition accuracy and adaptability of AI models, ensuring that they can make decisions more aligned with food safety management requirements when facing the complex and changing scenarios in actual food processing and production environments. 1. Data Collection: Original image data is sourced from self-shot photography or algorithmic generation to ensure diversity and legality of data sources, and the ID and file path of each original image are recorded. 2. Data Preprocessing and Annotation: According to the project requirements and model specifications, the image data of illegal food additive use is classified into training set and test set, and the training set is annotated with bounding box coordinates and corresponding labels. 3. Model Selection and Initialization: The NanoDet pre-trained model is selected, and its parameters are initialized, with reasonable hyperparameters such as learning rate, batch size, and redundancy set to optimize the model training process. 4. Model Training: The TensorFlow deep learning framework is used to load and initialize the model, and the prepared training set is input into the model for training. During the training process, the model continuously adjusts weights to minimize the difference between predicted boxes and ground-truth boxes, thereby improving detection accuracy. Training usually requires multiple epochs (iterations). 5. Model Evaluation: After training is completed, the test set is used to evaluate the model. Performance metrics such as precision, recall, and F1-score under different scenarios are calculated to ensure the model's accuracy and robustness. 6. Model Deployment and Real-time Performance Evaluation: The final trained and tested model is applied to specific projects. In practical applications, the real-time performance (i.e., accuracy) of the model is evaluated to ensure it meets project requirements.