
VIDGEN-1M
收藏资源简介:
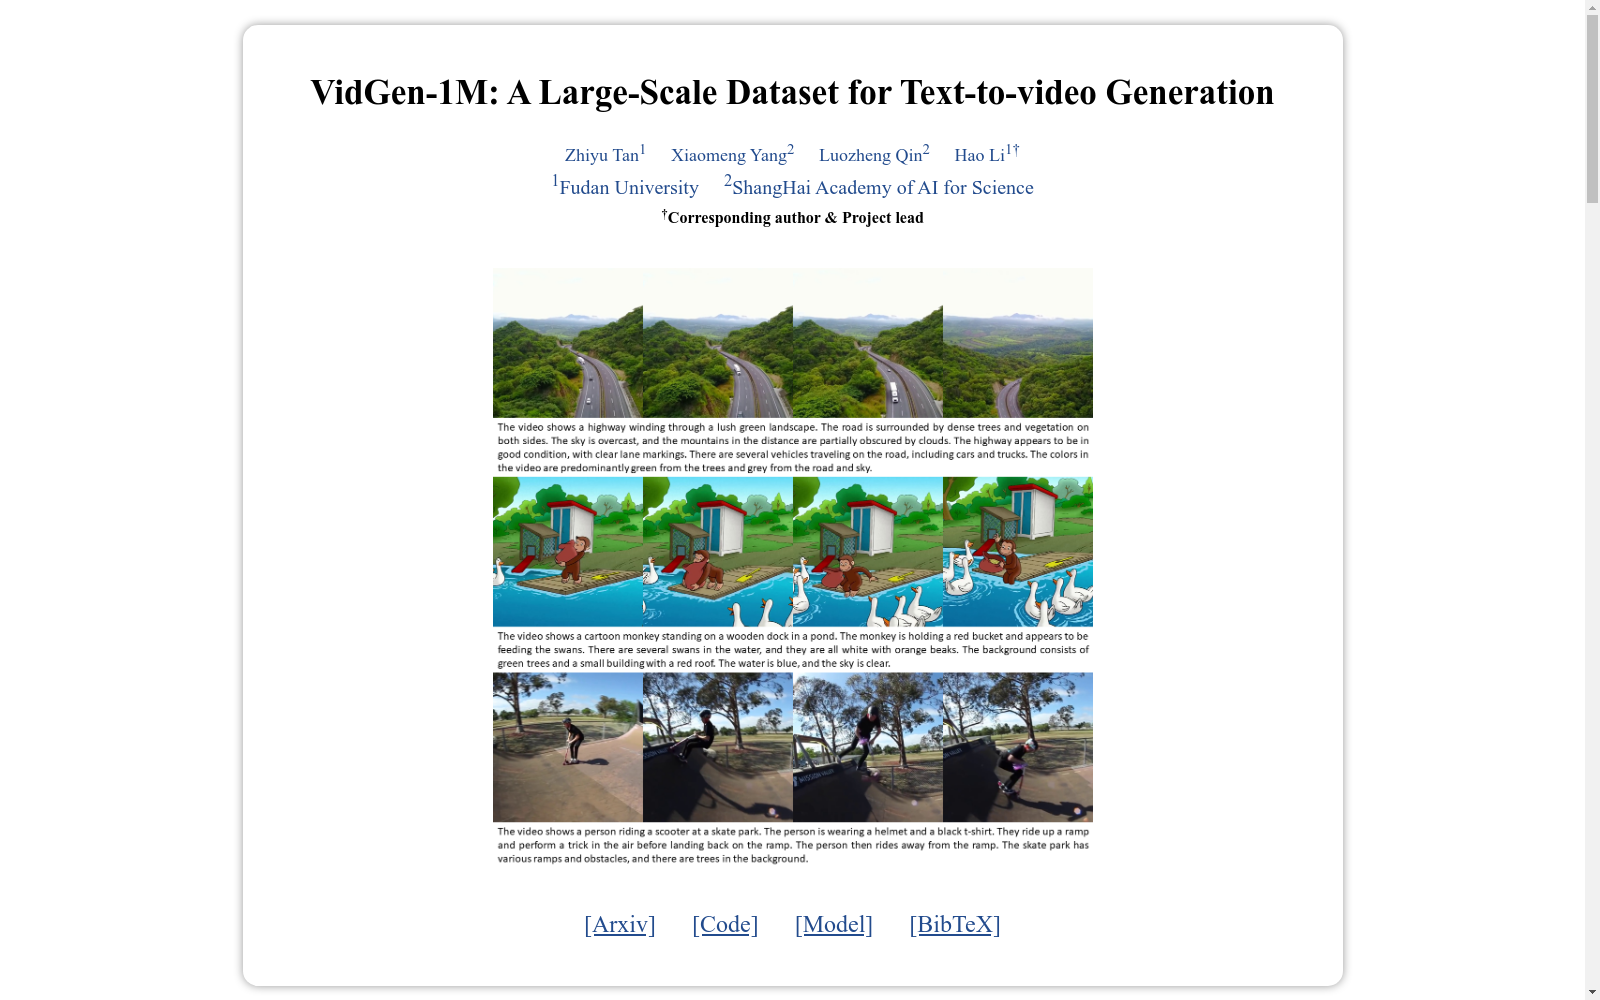
VIDGEN-1M是由复旦大学和上海人工智能科学院联合创建的大型视频文本生成数据集,包含100万个高质量视频片段及其详细描述性合成字幕。该数据集通过多阶段精细筛选流程创建,确保了视频与字幕间的高时空一致性。数据集内容涵盖广泛,字幕平均长度为89.3字,能准确捕捉视频中的动态元素。VIDGEN-1M主要用于训练和评估文本到视频生成模型,旨在提高模型生成视频的质量和准确性。
VIDGEN-1M is a large-scale video-text generation dataset jointly created by Fudan University and Shanghai AI Laboratory. It contains 1 million high-quality video clips and their detailed descriptive synthetic subtitles. Constructed through a multi-stage meticulous screening pipeline, this dataset ensures high spatiotemporal consistency between the videos and their corresponding subtitles. The dataset covers a wide range of content, with an average subtitle length of 89.3 words, which can accurately capture the dynamic elements in the videos. VIDGEN-1M is primarily used for training and evaluating text-to-video generation models, aiming to improve the quality and accuracy of model-generated videos.
- 1VidGen-1M: A Large-Scale Dataset for Text-to-video Generation复旦大学 上海人工智能科学院 · 2024年


