nz_research_commons_gpt_oss_cross_provider_results_1200
收藏资源简介:
该数据集是一个包含学术文献元数据与人工标注信息的集合,适用于自然语言处理任务。数据内容涵盖文献的标题、作者、主题、摘要、全文文本、年份等基本元数据,同时包含用于分类的标签(classification_label)、分类原因(classification_reason)及置信度(classification_confidence)。此外,数据集提供了经过处理的嵌入文本(embedding_text)及其令牌计数,以及对话数据(conversations)和标签文本(label_text)。部分字段记录了通过GPT模型生成的标注结果,包括模型预测标签(gpt_oss_label)、推理原因(gpt_oss_reason)、原始输出(gpt_oss_raw_output)和置信度(gpt_oss_confidence),可用于模型评估或对比分析。数据规模方面,数据集仅包含训练分割,共有50个样本,总大小约为902KB。该数据集可能应用于文本分类、对话系统训练、大语言模型性能评估或学术文献分析等场景。
This dataset is a collection of academic literature metadata and manually annotated information, suitable for natural language processing tasks. The data content includes basic metadata such as title, author, subject, abstract, full text, and year, along with classification labels (classification_label), classification reasons (classification_reason), and confidence scores (classification_confidence). Additionally, the dataset provides processed embedding text (embedding_text) with token counts, as well as conversation data (conversations) and label text (label_text). Some fields record annotation results generated by GPT models, including model-predicted labels (gpt_oss_label), reasoning reasons (gpt_oss_reason), raw outputs (gpt_oss_raw_output), and confidence scores (gpt_oss_confidence), which can be used for model evaluation or comparative analysis. In terms of data scale, the dataset only includes a training split, with a total of 50 samples and an approximate size of 902KB. This dataset may be applied to scenarios such as text classification, dialogue system training, large language model performance evaluation, or academic literature analysis.
数据集概述
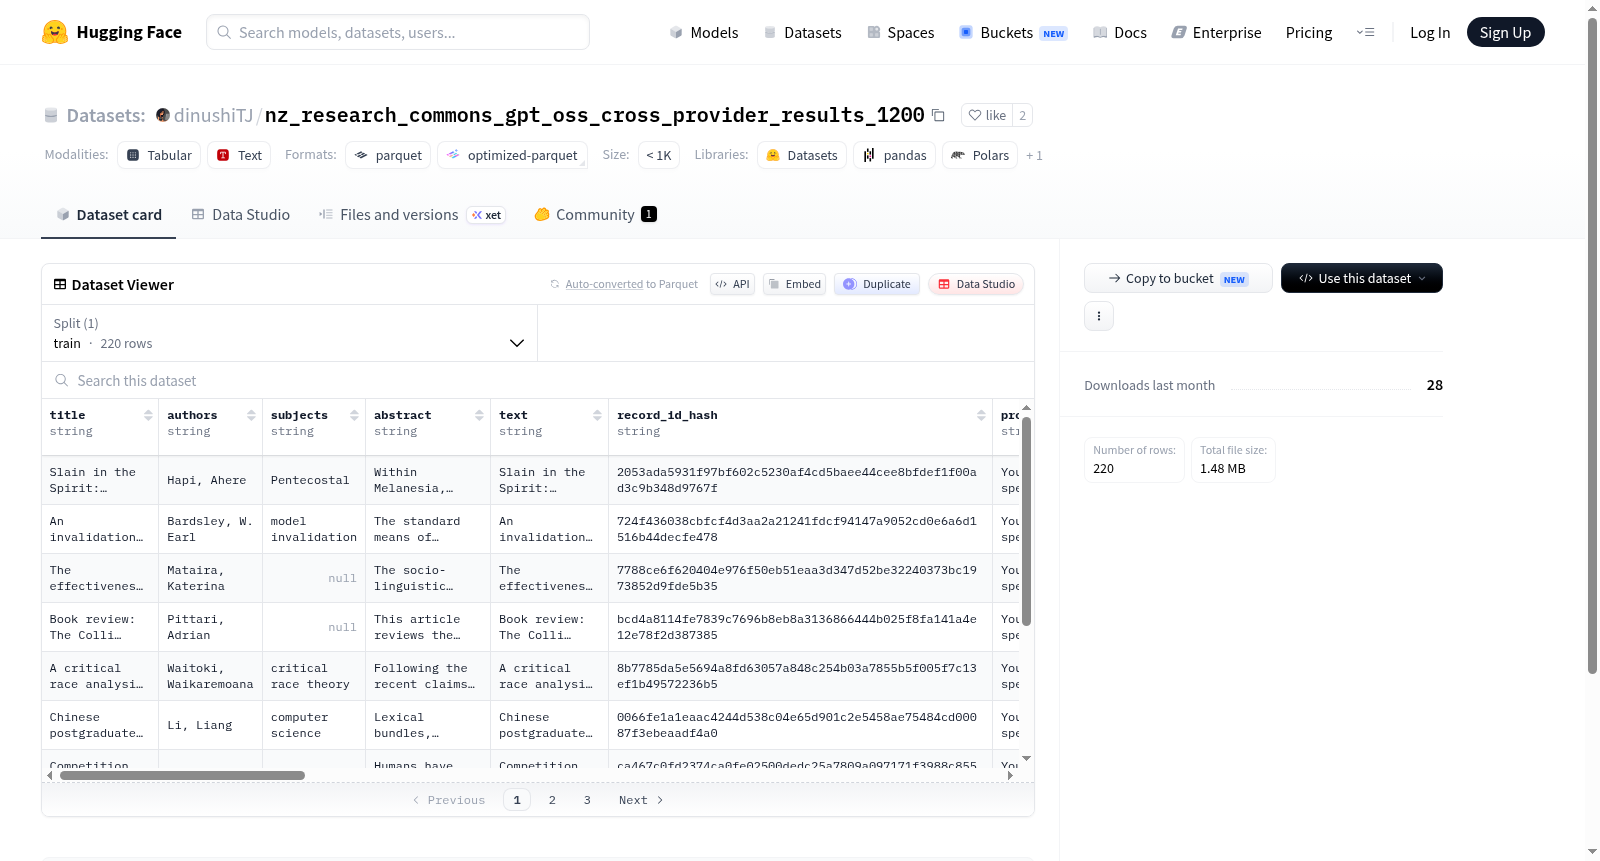
该数据集名为 nz_research_commons_gpt_oss_cross_provider_results_1200,托管于 Hugging Face 平台,是一个用于研究或分析的数据集,涉及新西兰研究文献的 GPT 与开源模型交叉标注结果。
数据集规模
- 总样本数:210 条
- 数据集大小:约 4.07 MB
- 下载大小:约 1.40 MB
- 数据划分:仅包含训练集(train)
特征字段
数据集包含 24 个字段,涵盖文献元数据、文本内容、分类标签、模型推理结果等:
| 字段名 | 数据类型 | 说明 |
|---|---|---|
| title | string | 文献标题 |
| authors | string | 作者 |
| subjects | string | 主题 |
| abstract | string | 摘要 |
| text | string | 正文文本 |
| record_id_hash | string | 记录 ID 哈希 |
| prompt | string | 提示词 |
| token_count | int64 | 文本 token 数量 |
| classification_label | int64 | 分类标签 |
| classification_reason | string | 分类理由 |
| year | string | 年份 |
| classification_confidence | float64 | 分类置信度 |
| embedding_text | string | 嵌入文本 |
| embedding_token_count | int64 | 嵌入 token 数量 |
| conversations | string | 对话内容 |
| label_text | string | 标签文本 |
| row_index | int64 | 行索引 |
| gpt_oss_model | string | 使用的 GPT 或开源模型名称 |
| gpt_oss_reasoning_effort | string | 模型推理努力程度 |
| gpt_oss_label | string | 模型预测标签 |
| gpt_oss_confidence | float64 | 模型预测置信度 |
| gpt_oss_reason | string | 模型推理理由 |
| gpt_oss_raw_output | string | 模型原始输出 |
| gpt_oss_error | null | 模型错误信息(当前均为空) |
| seconds | float64 | 推理耗时(秒) |
数据用途
该数据集主要用于比较 GPT 模型与开源模型(OSS)在新西兰研究文献分类任务上的表现,包含人工标注与模型标注的对比信息,适用于模型评估、交叉验证及推理分析研究。