doctolib-lab/finemed-rephrased-fr
收藏资源简介:
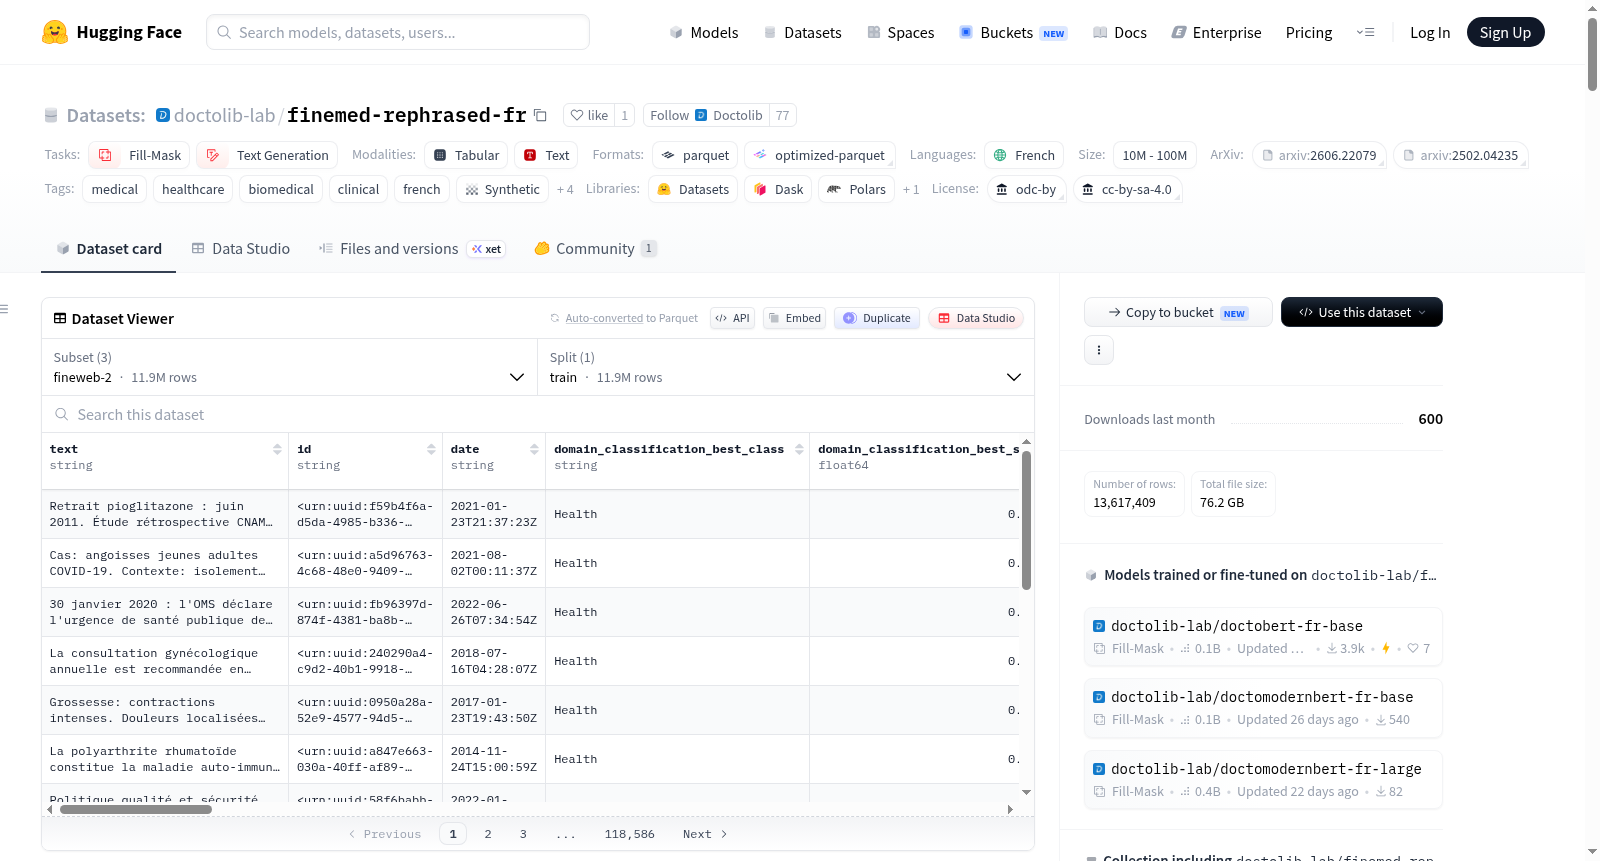
FineMed-rephrased-fr是一个法语医学文本数据集,通过大型语言模型(LLM)对FineMed-fr源文档进行重写生成,旨在提高医学术语密度并扩展医学概念的共现上下文。数据集包含三个来源的子配置:FineWeb-2、FinePDFs和FineWiki,总计1360万文档和45亿单词。重写过程采用两阶段流程:首先筛选医学内容并提议多样化的体裁-受众配对,然后进行忠实密度化和表面形式变化,保留医学内容不变,同时调整文本风格和缩写密度。数据集包含重写文本、原始文本、ID、URL、字数统计、重写配置参数、教育质量评分、医学术语密度等字段,适用于掩码填充和文本生成任务。数据集基于ODC-BY和CC BY-SA 4.0许可证,但请注意数据为合成文本,未经过临床验证,不构成医疗建议。
FineMed-rephrased-fr is a French medical text dataset generated by LLM rephrasing of FineMed-fr source documents, designed to increase medical-term density and broaden the co-occurrence context around medical concepts. The dataset includes three sub-configurations from sources: FineWeb-2, FinePDFs, and FineWiki, totaling 13.6 million documents and 4.5 billion words. The rephrasing pipeline involves a two-stage process: medical-content gating with diverse genre-audience pair proposals, followed by faithful densification and surface variation, preserving medical content while adjusting style and abbreviation density. It features fields such as rephrased text, original text, ID, URL, word counts, rewriting configuration, educational quality scores, and medical entity density, suitable for fill-mask and text-generation tasks. Licensed under ODC-BY and CC BY-SA 4.0, but note that the data is synthetic, not clinically validated, and does not constitute medical advice.