yangwang825/vox2-veri-full
收藏资源简介:
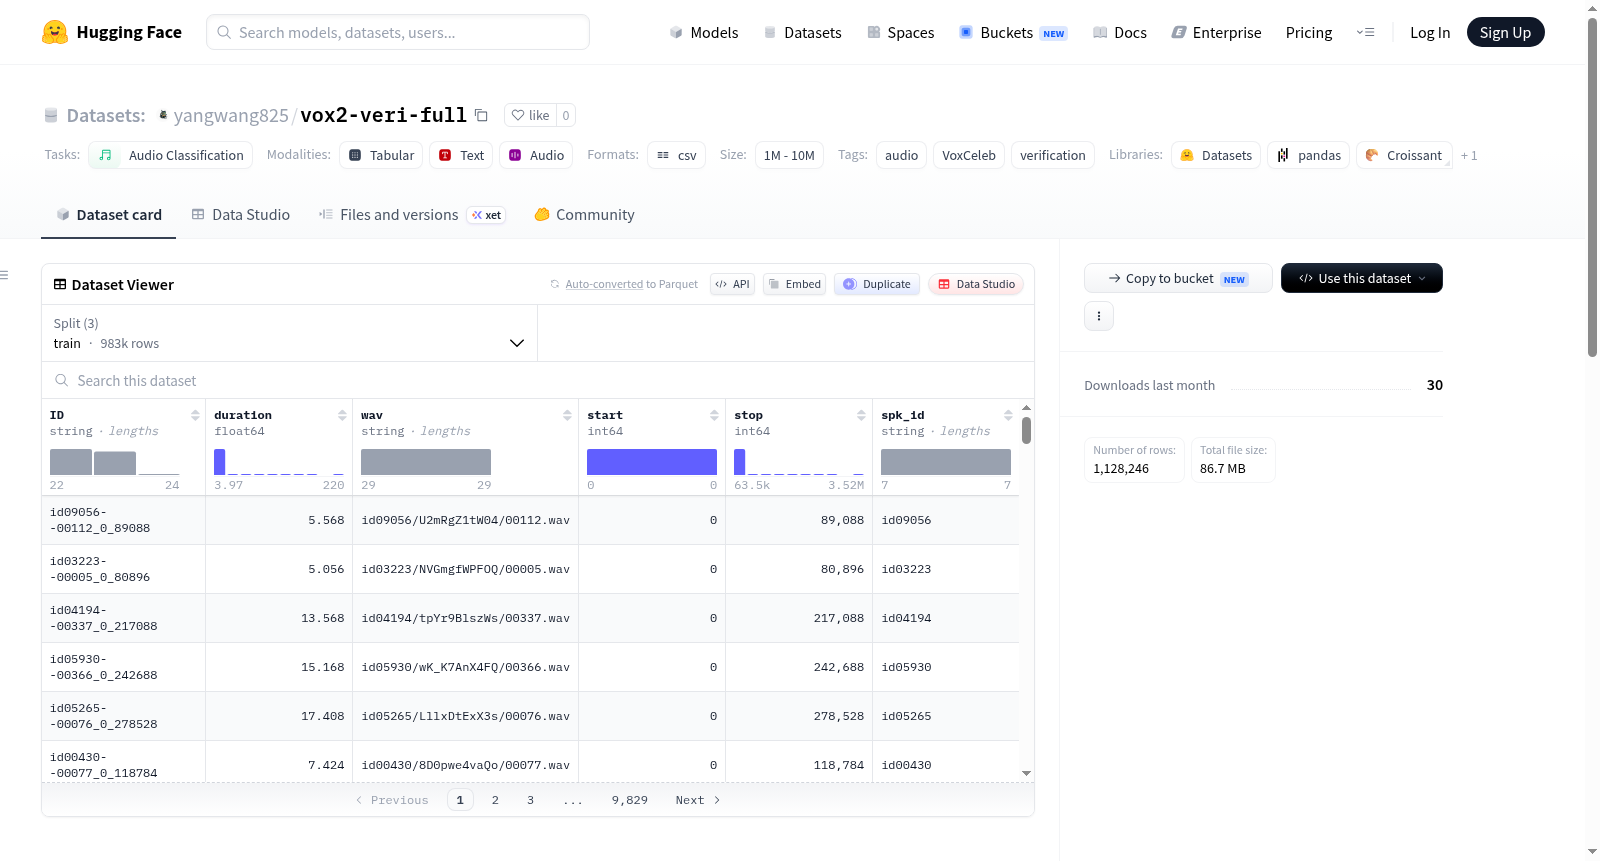
VoxCeleb2数据集包含超过100万条来自6,112位名人的语音片段,这些片段是从YouTube视频中提取的。数据集分为训练集、验证集和测试集,分别包含5,994位说话者的982,808个样本、5,994位说话者的109,201个样本和118位说话者的36,237个样本。每个样本包含ID、持续时间、波形文件路径、起始和停止索引以及说话者ID等信息。
The VoxCeleb2 dataset contains over 1 million speech segments from 6,112 celebrities, which are extracted from YouTube videos. The dataset is split into training, validation, and test sets, with 982,808 samples from 5,994 speakers, 109,201 samples from 5,994 speakers, and 36,237 samples from 118 speakers respectively. Each sample contains information such as ID, duration, waveform file path, start and stop indices, and speaker ID.
数据集概述
数据集名称
VoxCeleb 2
数据集描述
VoxCeleb2 包含超过100万条来自6,112位名人的语音样本,这些样本是从YouTube上传的视频中提取的。
数据集划分
| 划分 | 训练集 | 验证集 | 测试集 |
|---|---|---|---|
| 说话人数 | 5,994 | 5,994 | 118 |
| 样本数 | 982,808 | 109,201 | 36,237 |
数据字段
- ID (字符串): 样本ID,格式为
<spk_id--utt_id_start_stop>。 - duration (浮点数): 片段持续时间,单位为秒。
- wav (字符串): 波形文件路径。
- start (整数): 片段起始索引,等于 (起始秒数) × (采样率)。
- stop (整数): 片段结束索引,等于 (结束秒数) × (采样率)。
- spk_id (字符串): 说话人ID。
示例
json { ID: id09056--00112_0_89088, duration: 5.568, wav: id09056/U2mRgZ1tW04/00112.wav, start: 0, stop: 89088, spk_id: id09056 }