sahilmaniyar888/Indian_Climate_Resilience_Instruction_Corpus_
收藏资源简介:
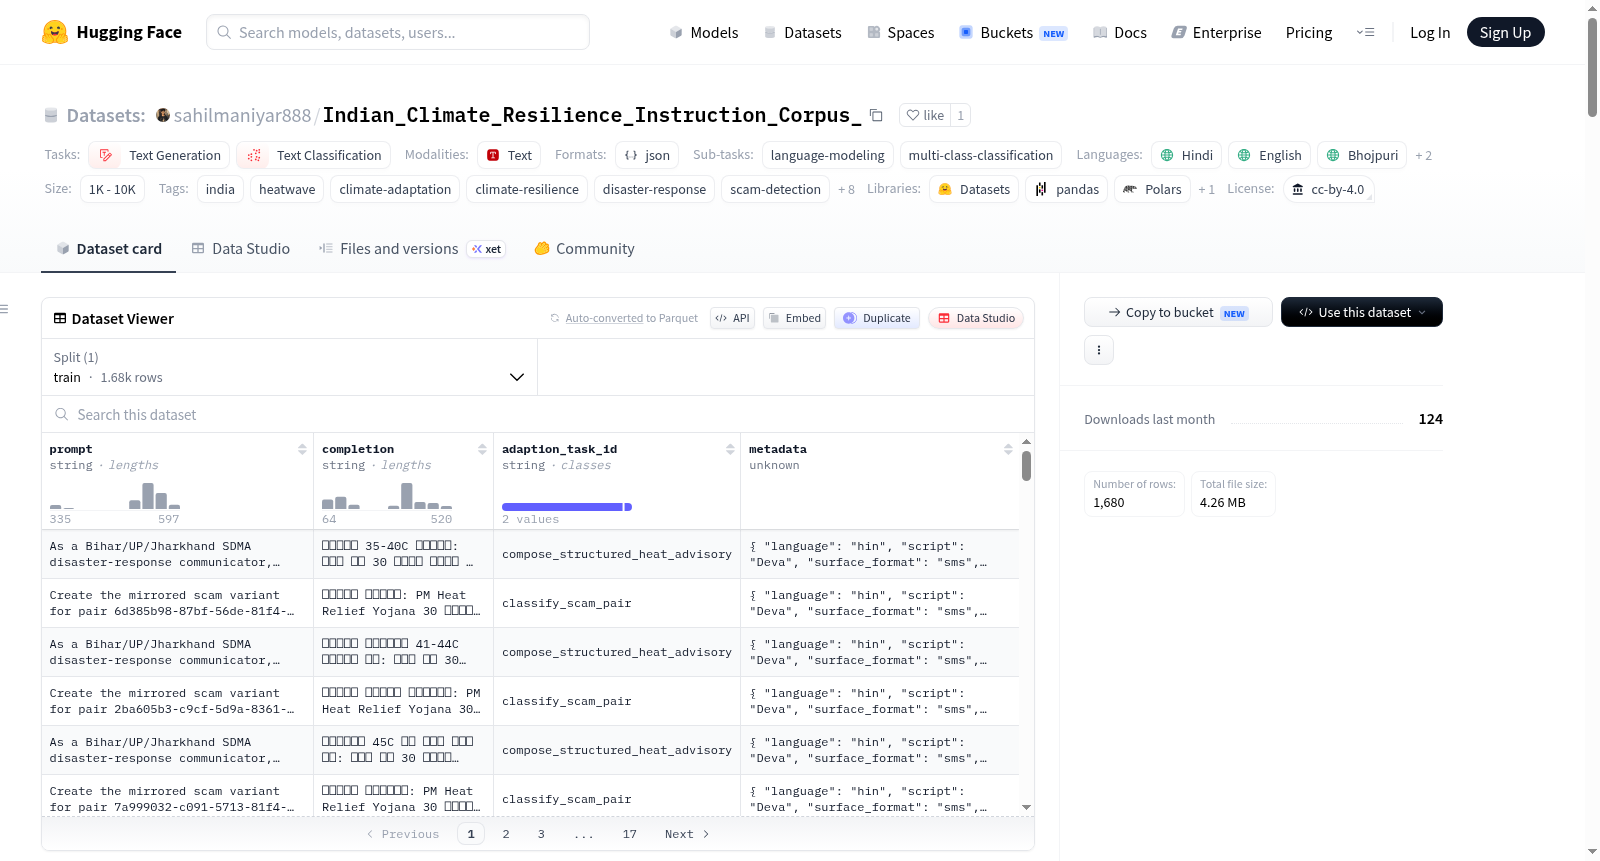
IndianCRIC(印度气候韧性指令语料库)是一个多语言数据集,旨在解决印度比哈尔邦、北方邦和贾坎德邦等高热脆弱性且AI覆盖率低的地区的需求。该数据集将经过验证的气候/灾害建议与结构上镜像的诈骗变体配对,支持安全对齐的指令调整、灾害错误信息检测和现实世界紧急通信建模。数据集包含五种语言(印地语、英语、博杰普尔语、迈蒂利语、桑塔利语)和五种格式(短信、WhatsApp、广播脚本、社区帖子、官方公告),每种格式都遵循严格的五部分紧急结构。数据集还包含诈骗配对,每个真实建议都配有一个受控的诈骗变体,以创建干净的对抗训练信号。数据集经过多项质量改进,包括结构过滤、行为对齐、安全基础、多语言校正和分布平衡。该数据集的独特之处在于教授风险下的决策制定、模拟真实灾害通信、在上下文中嵌入欺诈检测,并扩展到被忽视的印度语言。
IndianCRIC (Indian Climate Resilience Instruction Corpus) is a multilingual dataset designed to address the needs of regions like Bihar, Uttar Pradesh, and Jharkhand, which sit at the intersection of high heat vulnerability and low AI coverage. The dataset pairs verified climate/disaster advisories with structurally mirrored scam variants, enabling safety-aligned instruction tuning, disaster misinformation detection, and real-world emergency communication modeling. It includes five languages (Hindi, English, Bhojpuri, Maithili, Santali) and five formats (sms, whatsapp, radio_script, community_post, official_bulletin), each following a strict 5-part emergency structure. The dataset also features scam pairing, where every genuine advisory is paired with a controlled scam variant, creating a clean adversarial training signal. The dataset underwent several quality improvements, including structural filtering, behavioral alignment, safety grounding, multilingual correction, and distribution balancing. The dataset is unique in teaching decision-making under risk, modeling real disaster communication, embedding fraud detection in context, and expanding into ignored Indian languages.