Realmbird/nla-thought-anchors-hash-step2
收藏资源简介:
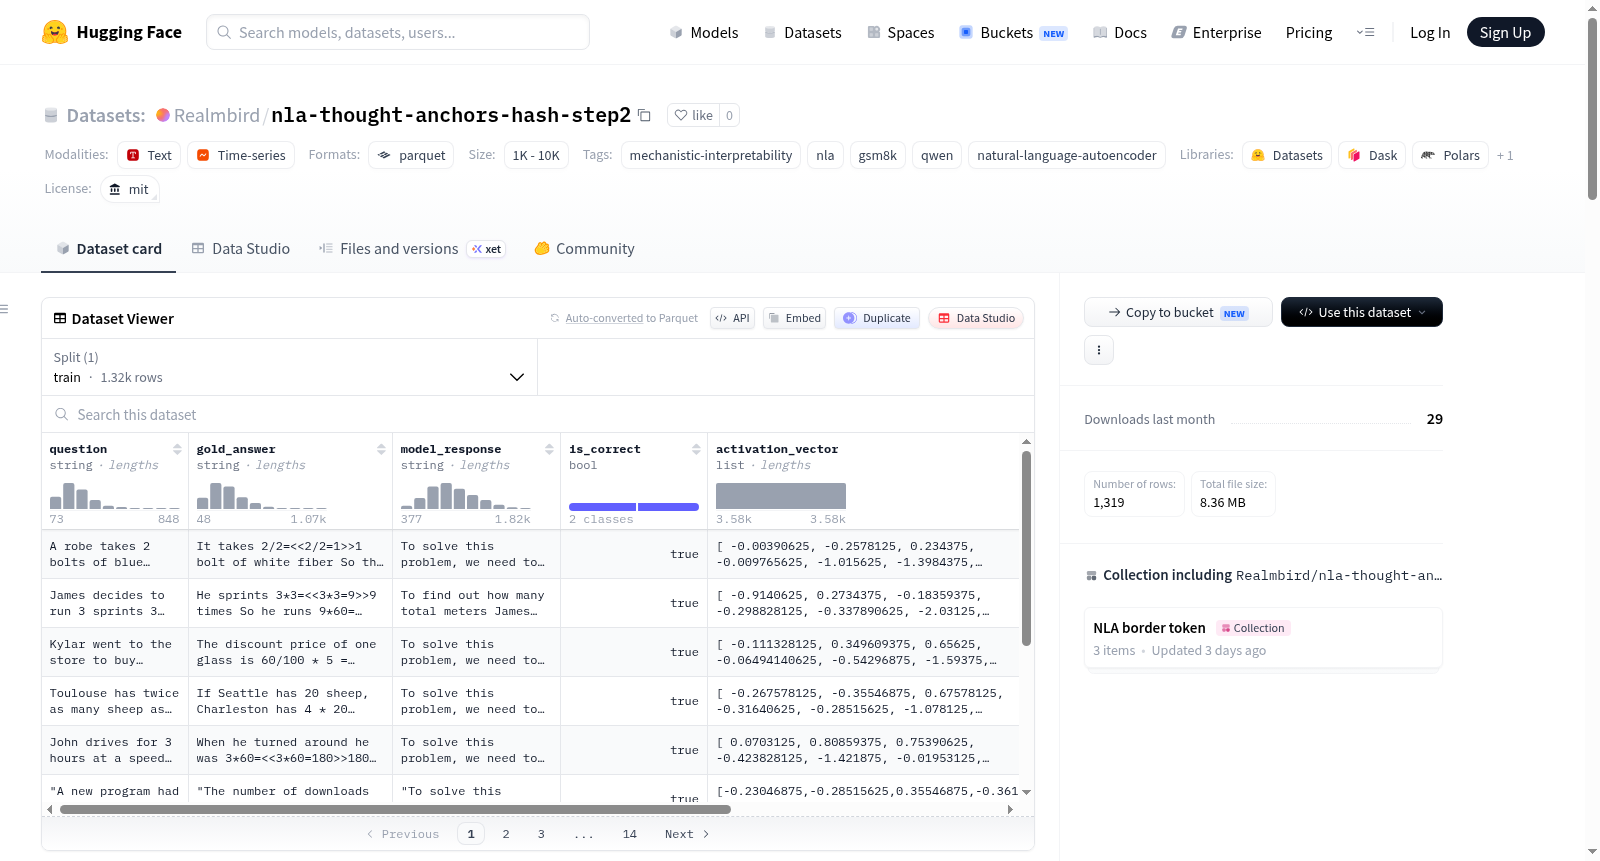
该数据集是NLA(自然语言自动编码器)管道nla-thought-anchors的第二步,包含Qwen2.5-7B-Instruct模型在GSM8K测试集上,于####标记处提取的第20层激活向量的自然语言描述。每个数据行包括:GSM8K数学问题文本、标准答案(含####标记)、模型生成的完整思维链和答案、模型答案是否正确、在####标记处的第20层残差流激活向量(长度为3584的浮点数列表)、在原始GSM8K测试分割中的索引,以及NLA执行器对激活向量的自然语言描述。数据集分为correct(正确示例,690条)和incorrect(错误示例,629条)两个分割,总计1319条数据。研究发现,NLA描述在正确示例中包含数字答案的比例为14.3%,表明####标记携带了有意义的答案信号。数据集适用于自然语言处理、机制可解释性等领域的研究。
This dataset is step 2 of the NLA (Natural Language Autoencoder) pipeline nla-thought-anchors, containing natural-language descriptions of Qwen2.5-7B-Instruct layer-20 activations extracted at the #### token on the GSM8K test set. Each row includes: GSM8K question text, ground-truth answer (with #### marker), full model-generated chain-of-thought and answer, whether the model answer is correct, the layer-20 residual stream activation vector at the #### token (a list of float32 with length 3584), the index in the original GSM8K test split, and the NLA actor verbalization of the activation. The dataset is split into correct (690 examples) and incorrect (629 examples) subsets, totaling 1319 examples. Findings show that the NLA description contains the numeric answer as a literal string in 14.3% of correct examples, confirming that the #### token carries meaningful answer signal. The dataset is useful for research in natural language processing and mechanistic interpretability.