UniRef90
收藏资源简介:
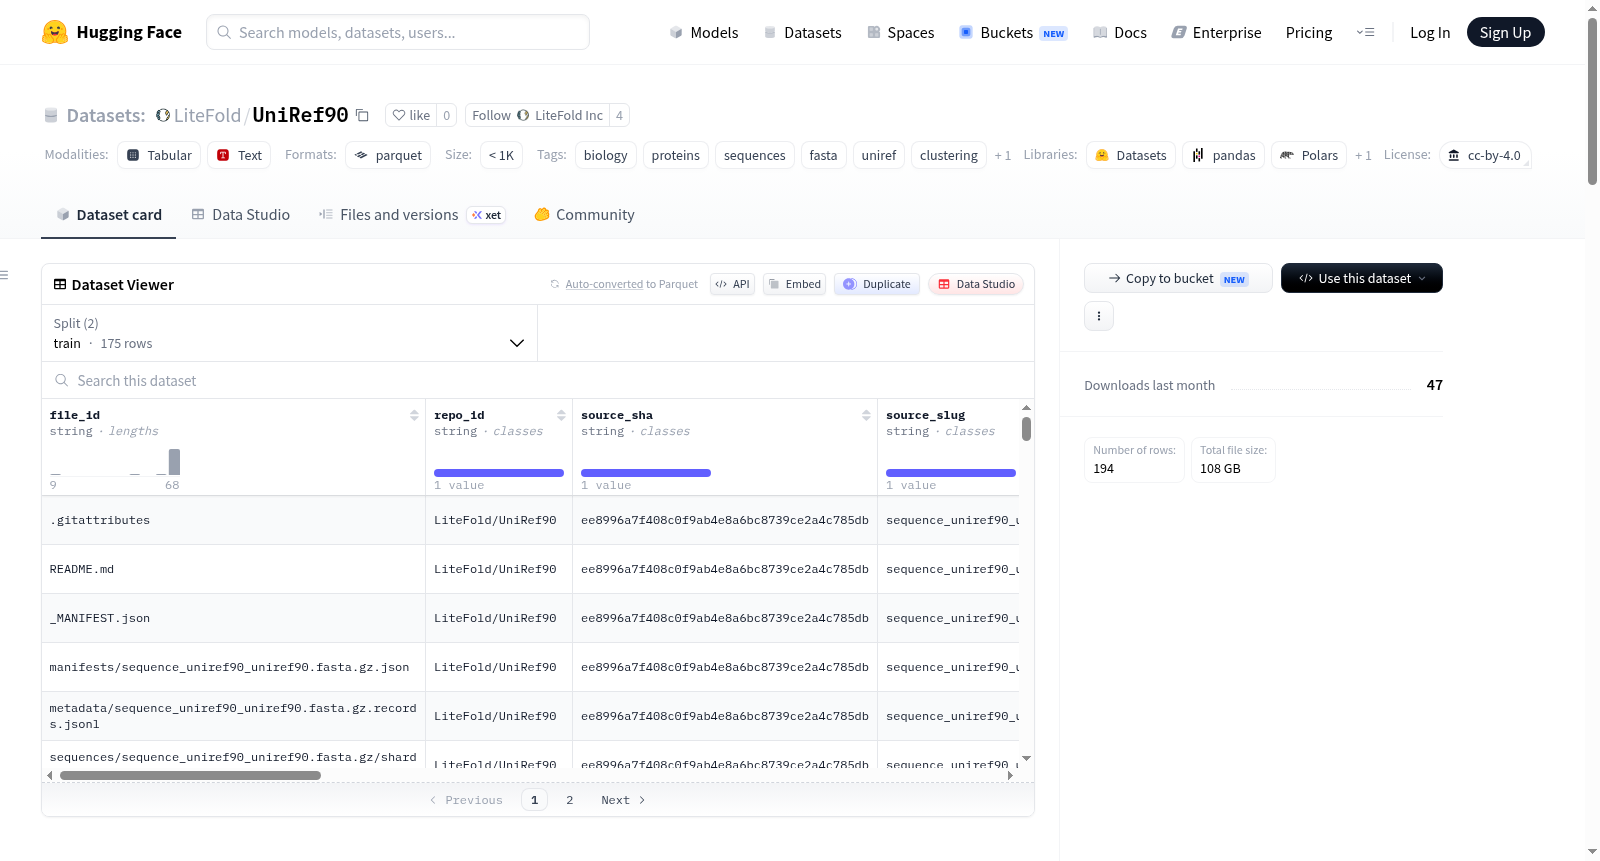
UniRef90 Shard Index 数据集提供了原始 UniRef90 FASTA 分片及其对应的文件/分片索引。UniRef90 是一个蛋白质序列聚类数据库,将相似性超过 90% 的序列聚类为代表性条目以降低冗余。由于完整序列数据规模庞大(包含 188,848,220 条记录,存储为 189 个压缩的 `.fasta.zst` 分片,且每记录元数据 JSONL 文件非常大),本数据集默认的 Parquet 格式表格主要用于在 Hugging Face Dataset Viewer 中进行预览、源发现、查看文件大小和下载模式,而不是展开所有序列记录。数据集包含两个划分:训练集(train)和测试集(test),基于文件 ID 的确定性哈希进行划分(`sha256(file_id) % 10`,结果为 0 的桶为测试集,1-9 为训练集)。数据表格包含 15 个字段,详细描述了每个文件(如序列分片、元数据文件等)的路径、角色、大小、压缩信息、是否序列分片标志以及下载建议模式等元信息。该数据集适用于需要高效浏览、定位和下载大规模 UniRef90 蛋白质序列分片及其元数据的生物信息学任务,例如蛋白质序列分析、数据库构建或机器学习数据管道的前期处理。
The UniRef90 Shard Index dataset provides raw UniRef90 FASTA shards and their corresponding file/shard indices. UniRef90 is a protein sequence clustering database that groups sequences with over 90% similarity into representative entries to reduce redundancy. Due to the large scale of the complete sequence data (containing 188,848,220 records, stored as 189 compressed `.fasta.zst` shards, and with very large per-record metadata JSONL files), the default Parquet format table in this dataset is primarily used for previewing, source discovery, viewing file sizes, and download modes in the Hugging Face Dataset Viewer, rather than expanding all sequence records. The dataset includes two splits: training set (train) and test set (test), based on deterministic hashing of file IDs (`sha256(file_id) % 10`, where buckets with result 0 are test set, and 1-9 are training set). The data table contains 15 fields that detail metadata for each file (such as sequence shards, metadata files, etc.), including path, role, size, compression information, whether it is a sequence shard flag, and download recommendation mode. This dataset is suitable for bioinformatics tasks that require efficient browsing, locating, and downloading of large-scale UniRef90 protein sequence shards and their metadata, such as protein sequence analysis, database construction, or preprocessing for machine learning data pipelines.
数据集概述:UniRef90 Shard Index
- 数据集名称:UniRef90 Shard Index
- 许可证:CC-BY-4.0
- 标签:生物学、蛋白质、序列、FASTA、UniRef、聚类、Parquet
- 数据集地址:https://huggingface.co/datasets/LiteFold/UniRef90
数据内容
- 包含原始UniRef90 FASTA分片(shards)及一个便于查看的文件/分片索引。
- 完整序列数据存储为189个
.fasta.zst分片文件。 - 每条记录的元数据JSONL文件体积巨大,因此默认数据集查看器表格索引仓库文件,而非展开全部188,848,220条序列记录。
- 使用原始
sequences/.../shard-*.fasta.zst文件获取完整的FASTA记录。 - 使用默认的Parquet表格进行数据集查看器预览、源发现、文件大小及下载模式查询。
数据划分(Splits)
划分方式基于文件ID的SHA256哈希值模10确定:桶0为测试集,桶1至9为训练集。
| 划分 | 行数 |
|---|---|
| train | 175 |
| test | 19 |
| 总计 | 194 |
源统计信息(Source Statistics)
| 字段 | 值 |
|---|---|
| UniRef90记录数 | 188,848,220 |
| 残基数 | 66,359,825,357 |
| 序列分片数 | 189 |
| 压缩后序列分片字节数 | 41,498,595,315 |
| 元数据JSONL字节数 | 66,419,395,026 |
数据集列(Columns)
| 列名 | 描述 |
|---|---|
file_id |
稳定的行ID,等于仓库路径。 |
repo_id |
Hugging Face数据集仓库名。 |
source_sha |
用于构建索引的源仓库提交哈希。 |
source_slug |
原始流水线清单中的源标识符。 |
path |
仓库中的文件路径。 |
role |
文件角色,如 sequence_shard、metadata_records 或 source_manifest。 |
shard_index |
序列分片的数字索引。 |
size_bytes |
文件大小(字节)。 |
compression |
压缩格式(如果适用)。 |
records_total |
清单中的UniRef90记录总数。 |
residues_total |
清单中的残基总数。 |
total_shards |
序列分片总数。 |
is_sequence_shard |
该行是否指向FASTA分片。 |
is_metadata_records |
该行是否指向每条记录的元数据JSONL文件。 |
download_pattern |
推荐的下载路径或通配符。 |
access_note |
描述索引范围的注释。 |
split_bucket |
通过 sha256(file_id) % 10 确定的划分桶。 |
准备脚本
用于创建Parquet文件的标准化脚本包含在 scripts/prepare_uniref90_dataset.py 中。