ghananlpcommunity/ghanaian-research-english
收藏资源简介:
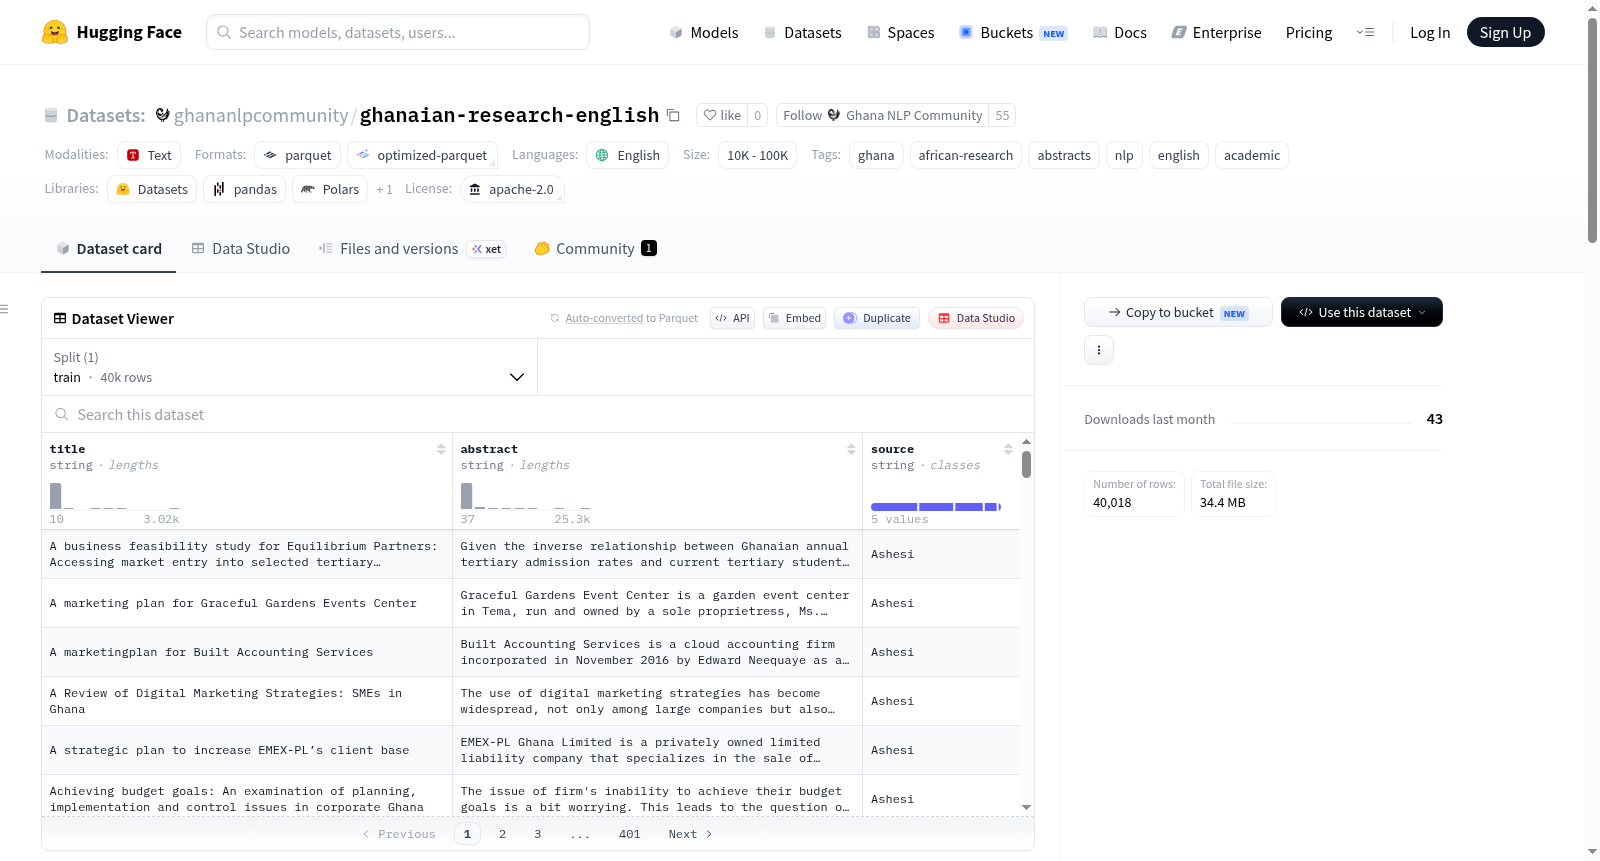
这是一个加纳研究英文数据集,是一个精选的集合,包含来自加纳五所大学仓库的40,018个研究标题和摘要。数据集旨在支持自然语言处理研究、信息检索、主题建模以及针对加纳学术文本的文本挖掘。数据源包括加纳大学(14,638项)、夸梅·恩克鲁玛科技大学(10,902项)、海岸角大学(8,951项)、温尼巴教育大学(4,208项)和阿什西大学(1,319项)。数据集结构包含标题、摘要和来源字段,经过去重处理,语言为英文,最小标题长度为10字符,最小摘要长度为30字符。用途包括训练或微调加纳学术英语的语言模型、加纳研究的主题建模和趋势分析、构建学术搜索引擎或推荐系统,以及研究论文的语义相似性和聚类。数据集通过爬取公共机构仓库并提取标题-摘要对创建,仅保留包含标题和有意义的摘要的项。
A curated collection of 40,018 research titles and abstracts from Ghanaian university repositories. The dataset brings together academic metadata from five Ghanaian universities to support NLP research, information retrieval, topic modeling, and academic text mining focused on Ghanaian scholarship. Sources include University of Ghana (14,638 items), Kwame Nkrumah University of Science and Technology (10,902 items), University of Cape Coast (8,951 items), University of Education, Winneba (4,208 items), and Ashesi University (1,319 items). Dataset structure includes title, abstract, and source fields, with deduplication applied. Language is English, with minimum title length of 10 characters and minimum abstract length of 30 characters. Use cases include training or fine-tuning language models on Ghanaian academic English, topic modeling and trend analysis of Ghanaian research, building academic search engines or recommender systems, and semantic similarity and clustering of research papers. The dataset was created by scraping public institutional repositories and extracting title-abstract pairs, retaining only items with both a title and meaningful abstract.