swebench_verified_random_100_folders_a3_rl_DCAgent_code_contests_noblock_5_8B_2026378395da
收藏资源简介:
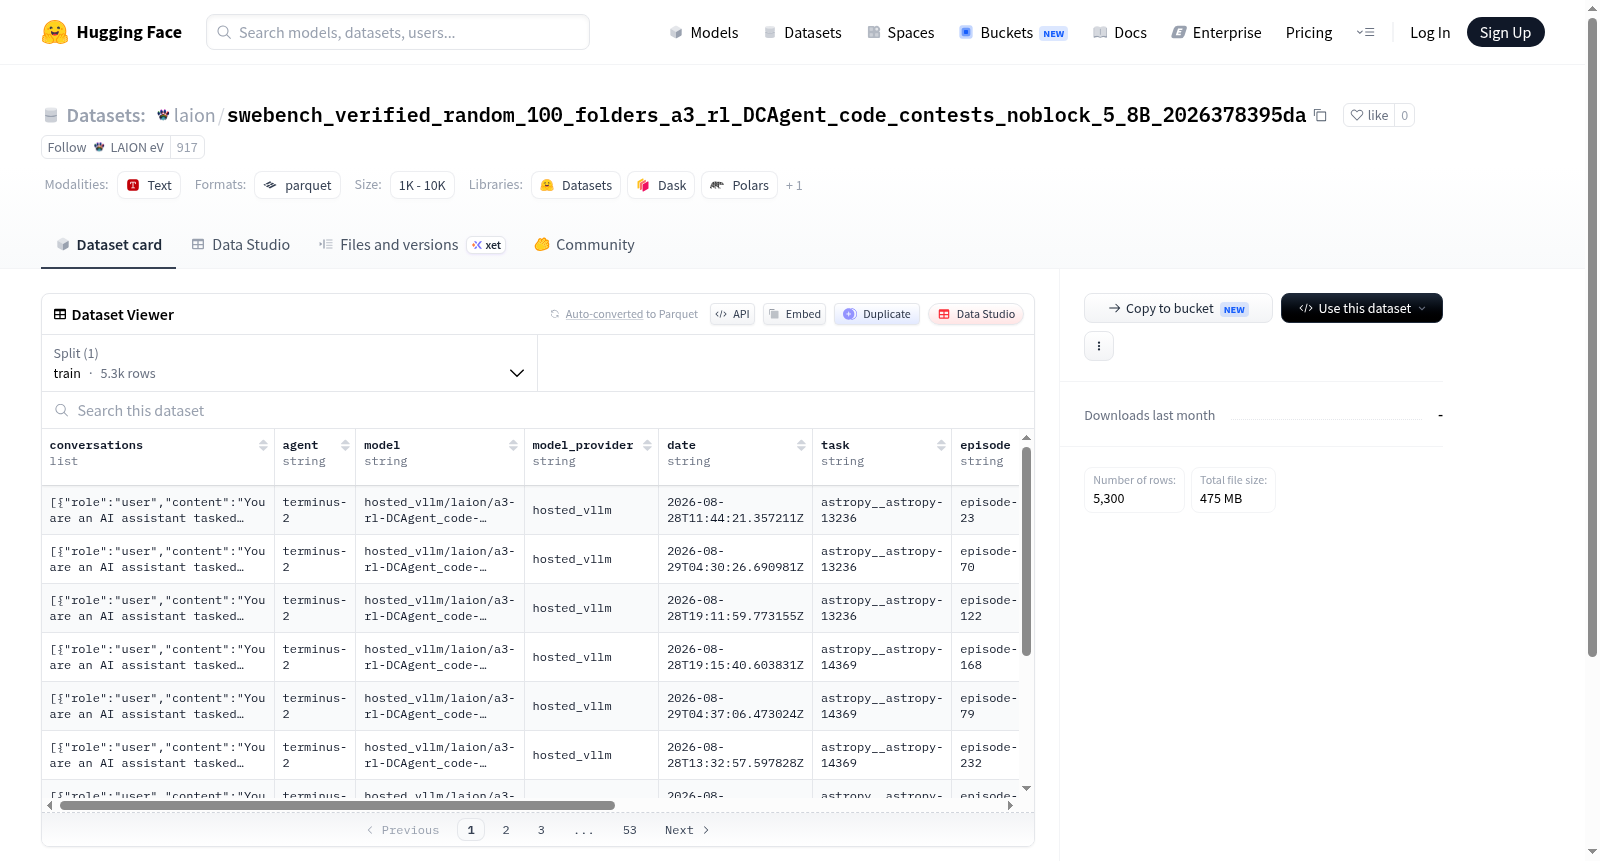
该数据集包含多轮对话记录,每条样本包含 conversations 字段,由 role(角色)和 content(内容)组成,表示对话中的用户和助手轮次。此外,还记录使用的 agent(智能体)、model(模型)、model_provider(模型提供商)、date(日期)、task(任务)、episode(轮次)、run_id(运行 ID)、trial_name(试验名称)、result(结果)、verifier_output(验证器输出)和 trace_source(追踪来源)等元数据。数据集共包含 5300 个训练样本,总大小约 890MB。适用于对话系统评估、agent 行为分析、任务完成情况研究等场景。
This dataset contains multi-turn conversation records. Each sample includes a conversations field, consisting of role and content, representing the user and assistant turns. Additionally, it records metadata such as agent, model, model_provider, date, task, episode, run_id, trial_name, result, verifier_output, and trace_source. The dataset comprises 5300 training samples with a total size of approximately 890MB. It is suitable for dialogue system evaluation, agent behavior analysis, and task completion research.
数据集概述
该数据集来自 Hugging Face,主要包含与代码竞赛(Code Contests)相关的智能体(Agent)交互会话数据,具体为 laion/swebench_verified_random_100_folders_a3_rl_DCAgent_code_contests_noblock_5_8B_2026378395da。
数据内容与结构
- 主要特征:每条数据包含
conversations(对话列表,内含角色role和内容content)、agent(智能体名称)、model(使用的模型)、model_provider(模型提供方)、date(日期)、task(任务描述)、episode、run_id、trial_name、result(结果)、verifier_output(验证器输出)以及trace_source(追踪来源)等字段。 - 数据划分:仅包含一个
train划分,共 5300 条样本。 - 数据规模:数据集总大小约为 890 MB(890,237,441 字节),下载大小约为 475 MB(474,762,118 字节)。
数据用途
该数据集适用于研究智能体在代码竞赛任务中的行为,特别是基于强化学习(RL)的智能体交互过程分析、模型性能评估、以及对话轨迹的挖掘等场景。