Nemotron-RL-Agentic-Terminal-Pivot-v1
收藏资源简介:
Nemotron-RL-Agentic-Terminal-Pivot-v1 是一个用于命令行智能体(终端使用)强化学习训练的数据集,由 NVIDIA 创建,采用 CC-BY-4.0 许可。该数据集专为 NeMo Gym 的 terminus_judge 环境设计,每个样本代表一个智能体决策点,包含:prompt(responses_create_params.input),即任务指令与到决策点为止的终端交互历史;参考动作(expected_answer),即教师智能体在该点采取的下一个动作,以 Terminus-2 格式的 JSON 对象表示,包含分析、计划、命令(keystrokes)和任务完成标志;以及 agent_ref,用于路由到 NeMo Gym 的 terminus_judge 资源服务器,通过比较策略模型生成的动作与参考动作产生奖励,实现可验证奖励的强化学习(RLVR)。数据来源于 ATCB 任务集合,涵盖 630 个独特的种子任务,每个任务是一个容器化的 Linux 环境,包含自然语言指令、隐藏参考方案和自动化验证器。任务强调真实的、长时间跨度的终端操作工作,包括构建、修复和调和数据管道;审计和恢复日志、账本、缓存、遥测存储中的注入故障;诊断崩溃的服务、调度器和 CI 构建;以及安全/合规工作流(访问日志审计、SIEM 分类、PII 处理、TLS 和身份验证修复),场景涵盖工业与嵌入式系统(SCADA、固件/OTA、冷链、卫星)、HPC 集群、医疗、金融和媒体档案。轨迹由 Terminus-2 智能体(v2.0.0)在 Harbor 执行框架中生成,以 GLM-5.1 作为教师模型。仅保留通过任务自动验证器的轨迹(每个任务最多 5 条成功轨迹),并将每条轨迹中每个有效的助手轮次转换为一个下一步动作训练样本。过滤了退化轮次(过长的命令字符串、重复提示、完成后的确认)以及观察文本捕获了收集基础设施细节的记录。数据集共 31,111 个训练样本,来自 630 个种子任务和 2,716 条不同轨迹,中位数每任务 45 个样本。包含 8 个顶层字段(7 个数据字段加一个 metadata 对象,后者有 5 个子字段)。平均 prompt 长度约 39,900 字符,平均参考动作长度约 970 字符。总数据存储约 1.4 GB(JSONL 未压缩格式)。该数据集曾用于 NVIDIA Nemotron Ultra 和 Nemotron Nano 3.5 模型的强化学习后训练。适用于商业或非商业用途。
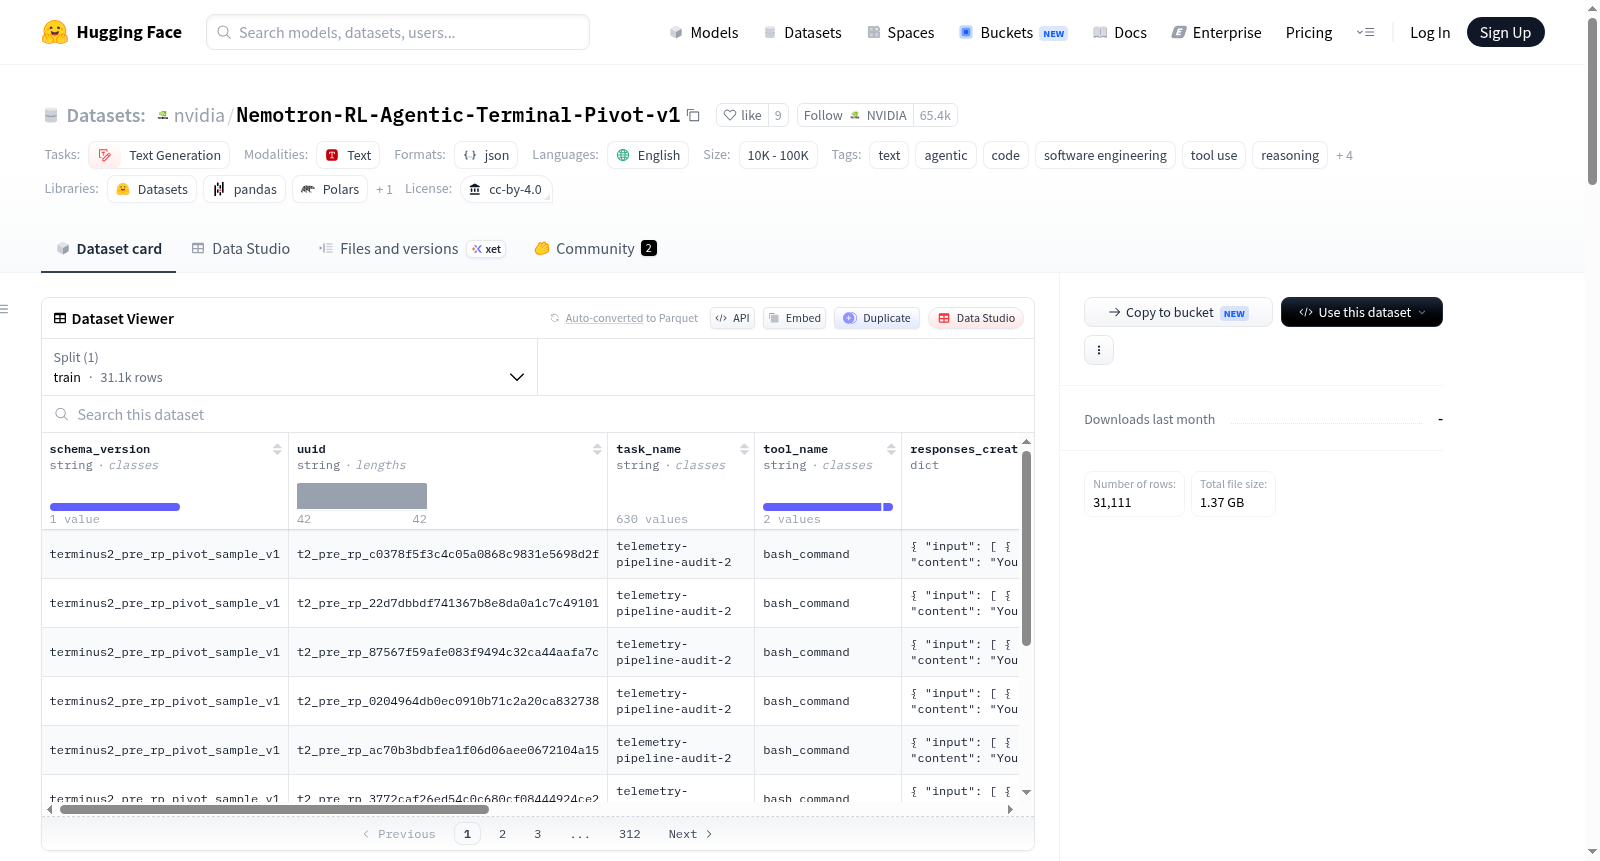
Nemotron-RL-Agentic-Terminal-Pivot-v1 is a dataset for reinforcement learning training of command-line agents (terminal use), created by NVIDIA and licensed under CC-BY-4.0. It is specifically designed for the terminus_judge environment of NeMo Gym. Each sample represents an agent decision point and contains: prompt (responses_create_params.input) which is the task instruction and terminal interaction history up to the decision point; reference action (expected_answer) which is the next action taken by the teacher agent at that point, represented as a JSON object in Terminus-2 format, including analysis, plan, commands (keystrokes), and task completion flag; and agent_ref, used for routing to the terminus_judge resource server of NeMo Gym, which generates rewards by comparing the policy models action with the reference action, enabling verifiable reward reinforcement learning (RLVR). The data comes from the ATCB task collection, covering 630 unique seed tasks. Each task is a containerized Linux environment containing natural language instructions, hidden reference solutions, and automated verifiers. The tasks emphasize realistic, long-duration terminal operations, including building, fixing, and reconciling data pipelines; auditing and recovering injected faults in logs, ledgers, caches, telemetry stores; diagnosing crashed services, schedulers, and CI builds; and security/compliance workflows (access log auditing, SIEM classification, PII handling, TLS and authentication fixes). Scenarios cover industrial and embedded systems (SCADA, firmware/OTA, cold chain, satellites), HPC clusters, healthcare, finance, and media archives. Trajectories are generated by the Terminus-2 agent (v2.0.0) in the Harbor execution framework, using GLM-5.1 as the teacher model. Only trajectories that pass the tasks automated verifier are retained (up to 5 successful trajectories per task), and each valid assistant turn in a trajectory is converted into a next-action training sample. Degenerate turns (overly long command strings, repeated prompts, post-completion confirmations) and observations that captured infrastructure details are filtered out. The dataset contains 31,111 training samples from 630 seed tasks and 2,716 distinct trajectories, with a median of 45 samples per task. It includes 8 top-level fields (7 data fields plus a metadata object with 5 subfields). The average prompt length is about 39,900 characters, and the average reference action length is about 970 characters. The total data storage is about 1.4 GB (JSONL uncompressed format). This dataset has been used for reinforcement learning post-training of NVIDIA Nemotron Ultra and Nemotron Nano 3.5 models. Suitable for commercial or non-commercial use.
数据集概述
基本信息
- 数据集名称:Nemotron-RL-Agentic-Terminal-Pivot-v1
- 所有者:NVIDIA Corporation
- 创建日期:轨迹收集与样本构建于2026年5月,发布准备于2026年7月21日
- 版本:v1.0(无先前版本)
- 许可证:Creative Commons Attribution 4.0 International (CC-BY-4.0)
- 语言:英文
- 数据规模:10K < n < 100K(实际31,111条训练样本)
- 任务类型:文本生成
- 标签:文本、智能体、代码、软件工程、工具使用、推理、强化学习、合成、人工、终端
数据集内容
该数据集为命令行(终端)LLM智能体的强化学习提供训练样本,与NeMo Gym中的terminus_judge环境配合使用。每条记录是从成功的终端任务智能体轨迹中提取的单一决策点,包含以下核心字段:
responses_create_params.input:提示词,包含任务指令及截至决策点的终端交互历史(先前智能体动作和终端输出)expected_answer:教师智能体在该点的参考下一步动作(Terminus-2格式的JSON对象,含analysis、plan、commands[].keystrokes和task_complete字段)agent_ref:路由至NeMo Gymterminus_judge资源服务器,用于对策略模型生成的动作与参考动作进行评分,产生可验证奖励强化学习(RLVR)的奖励信号
任务来源与场景
样本源自ATCB任务集合,涵盖630个独特的ATCB种子任务,每个任务是一个容器化的Linux环境,包含自然语言指令、隐藏参考解决方案和自动化验证器。任务强调终端中的现实长周期运维工作,具体场景包括:
- 构建、修复和协调数据管道
- 审计和恢复日志、账本、缓存及遥测存储中的注入故障
- 诊断崩溃的服务、调度器和CI构建
- 安全/合规工作流(访问日志审计、SIEM分流、PII处理、TLS和认证修复)
- 场景覆盖工业与嵌入式系统(SCADA、固件/OTA、冷链、卫星)、HPC集群、医疗、金融及媒体档案
数据生成方法
- 数据收集:混合方式(人工+合成+自动化)——ATCB种子任务由数据供应商人工编写;智能体轨迹由GLM-5.1(
zai-org/GLM-5.1)教师模型驱动Terminus-2智能体(v2.0.0)在Harbor执行框架中生成;执行、验证和逐轮样本提取通过自动化管道完成 - 标注方法:混合方式(合成+自动化)——参考下一步动作来自教师模型输出;轨迹级成功标签来自各任务的自动化验证器脚本,仅保留通过验证器的轨迹;无人工标注和过滤模型
- 筛选规则:仅保留通过验证器的轨迹(每任务最多5条成功轨迹);过滤退化轮次(过长命令字符串、重复提示、完成后确认)及包含采集基础设施细节的观测文本记录
数据统计
- 记录数:31,111条训练样本
- 任务覆盖:630个唯一ATCB种子任务;2,716条不同的源轨迹;每任务中位数45个样本
- 字段数:8个顶层字段——7个数据字段(含
responses_create_params、expected_answer、agent_ref)及含5个子字段的metadata对象 - 平均长度:提示词约39,900字符;参考动作约970字符
- 存储大小:约1.4 GB(JSONL,未压缩)
数据格式
- 模态:文本
- 格式:JSON Lines(
.jsonl),每行一个训练样本,UTF-8编码 - 兼容性:与NeMo Gym
terminus_judge环境兼容
预期用途
- 使用强化学习对大型语言模型进行终端智能体使用的后训练
- 由NeMo Gym
terminus_judge资源服务器消费:训练时策略模型接收responses_create_params.input提示,判断器对生成的下一步动作与expected_answer进行评分并产生奖励 - 也可用于终端智能体的监督微调或终端智能体行为的离线分析
相关资源
- NeMo Gym:https://github.com/NVIDIA-NeMo/Gym
- terminus_judge资源服务器:https://github.com/NVIDIA-NeMo/Gym/tree/main/resources_servers/terminus_judge
- Terminal-Bench:https://github.com/laude-institute/terminal-bench
- Terminus-2智能体/Harbor框架:https://github.com/laude-institute/harbor
- GLM-5.1:https://huggingface.co/zai-org/GLM-5.1
伦理考量
- 任务环境为数据供应商编写的合成、容器化场景;任务内容中出现的个人数据(姓名、电子邮件地址、凭据)均为虚构的剧情素材
- 发布文本已扫描真实个人和基础设施信息:未识别出真实个人数据;内部采集元数据(来源标识、管道和基础设施字段)已从所有记录中移除;包含采集基础设施细节的观测文本记录在发布前已删除
- 该数据集适用于商业或非商业用途