lwaekfjlk/social-world-model-v5
收藏资源简介:
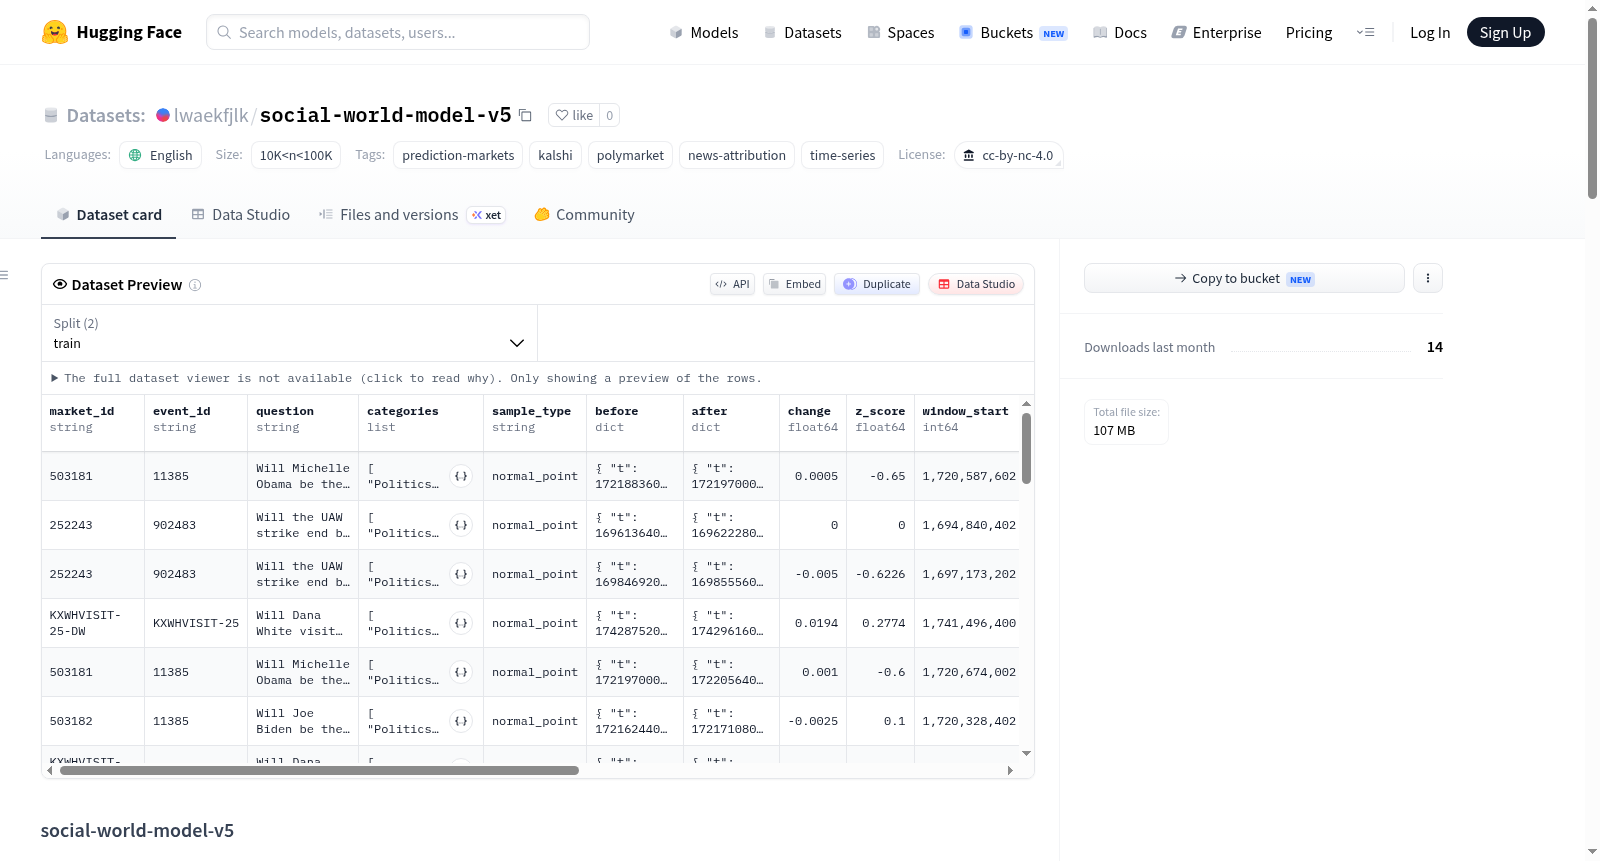
social-world-model-v5是一个精心策划的预测市场数据集,用于训练attributor(归因器)和forecaster(预测器)模型。该数据集基于Kalshi和Polymarket市场,通过GNews爬取新闻,并使用Qwen3-32B模型(基于v3 attribution prompt)对每篇新闻进行因果归因评分,再通过GPT-4o-mini提取的实体关键词进行过滤。v5版本的主要更新包括:更清洁的新闻(仅保留attribution_score > 0或与问题关键词匹配的新闻,去除了约35%的v3噪声新闻)、严格的无泄漏时间窗口(新闻发布时间必须在市场事件发生前3天内)、每个候选事件的独立爬取(避免密集市场数据被稀释)、使用Qwen3-32B重新评分(基于包含直接因果、错误方向、仅主题相关、多跳政治和多跳竞争案例的6个上下文示例)、统一的z-score计算(使用中位数变化和MAD标准化,并设置标准差下限为0.01),以及过滤后无新闻的记录被丢弃(确保每条记录至少有一条新闻)。数据集包含训练集(8,214条记录)和测试集(分为Kalshi和Polymarket子集,分别有954条和3,345条记录),按时间分割(after.t < 2025-11-01为训练集,其余为测试集)。数据模式包括事件ID、市场ID、问题、类别、样本类型、z-score(带符号)、价格变化、时间窗口、价格时间序列、前后价格点、新闻列表(含标题、描述、URL等)以及对应的归因评分(0到1)。构建管道涵盖候选采样、新闻爬取、实体关键词查询、归因评分、过滤和时间分割去重等步骤。预期用途包括:训练归因模型(学习为新闻分配因果权重)、训练预测模型(基于问题和历史数据预测未来价格),以及因果新闻检索(筛选高评分新闻)。注意事项包括:Polymarket测试集可能包含连续价格市场、高z-score记录可能归因评分为零(表示市场噪声而非新闻驱动)、多跳示例可能导致弱相关新闻评分偏高,以及许可证为CC-BY-NC-4.0(仅限研究使用)。数据集语言为英语,规模在10K到100K之间。
social-world-model-v5 is a curated prediction-market dataset with per-news causal-attribution scores for training attributor and forecaster models. Built on top of Kalshi and Polymarket markets, with GNews-crawled news scored by Qwen3-32B (using v3 attribution prompt) and filtered by GPT-4o-mini-extracted entity keywords. Key updates in v5 include: cleaner news (only items with attribution_score > 0 or question-keyword matches are kept, dropping ~35% of v3 noise), strict no-leak time window (news must be published within 3 days before the market event), per-candidate crawl (each candidate has its own 3-day window query to avoid dilution in dense markets), re-attribution with Qwen3-32B and v3 prompt (per-news independent scoring with 6 in-context examples covering direct causal, wrong-direction, topical-only, multi-hop political, and multi-hop competitive cases), unified z-score with a sigma floor (z = (|Δp| − median_change) / max(MAD × 1.4826, 0.01)), and dropping records with zero news after filtering (ensuring each record has ≥1 news). The dataset consists of train.jsonl (8,214 records), test_kalshi.jsonl (954 records), and test_polymarket.jsonl (3,345 records), split by time (after.t < 2025-11-01 for train, else for test). The schema includes event_id, market_id, question, categories, sample_type, z_score (signed), change, window timestamps, price time series (17 points), before/after price points, news list (with title, description, URL, etc.), attributions (aligned scores from 0 to 1), and source provenance. The construction pipeline involves candidate sampling, news crawling via GNews API, entity-keyword query extraction with GPT-4o-mini, attribution scoring with Qwen3-32B, filtering, and time-based splitting with deduplication. Intended uses include: attributor training (to assign causal weights to news given question and price changes), forecaster training (to predict after.p from question, historical prices, and news), and causal-news retrieval (filtering for high-score news). Caveats note that Polymarket test sets may include continuous-price markets, high-|z| records can have all-zero attributions (indicating market noise), multi-hop examples may leak into weakly-related news, and the license is CC-BY-NC-4.0 for research only. The dataset is in English, with a size category of 10K<n<100K.