yeni_dataset
收藏资源简介:
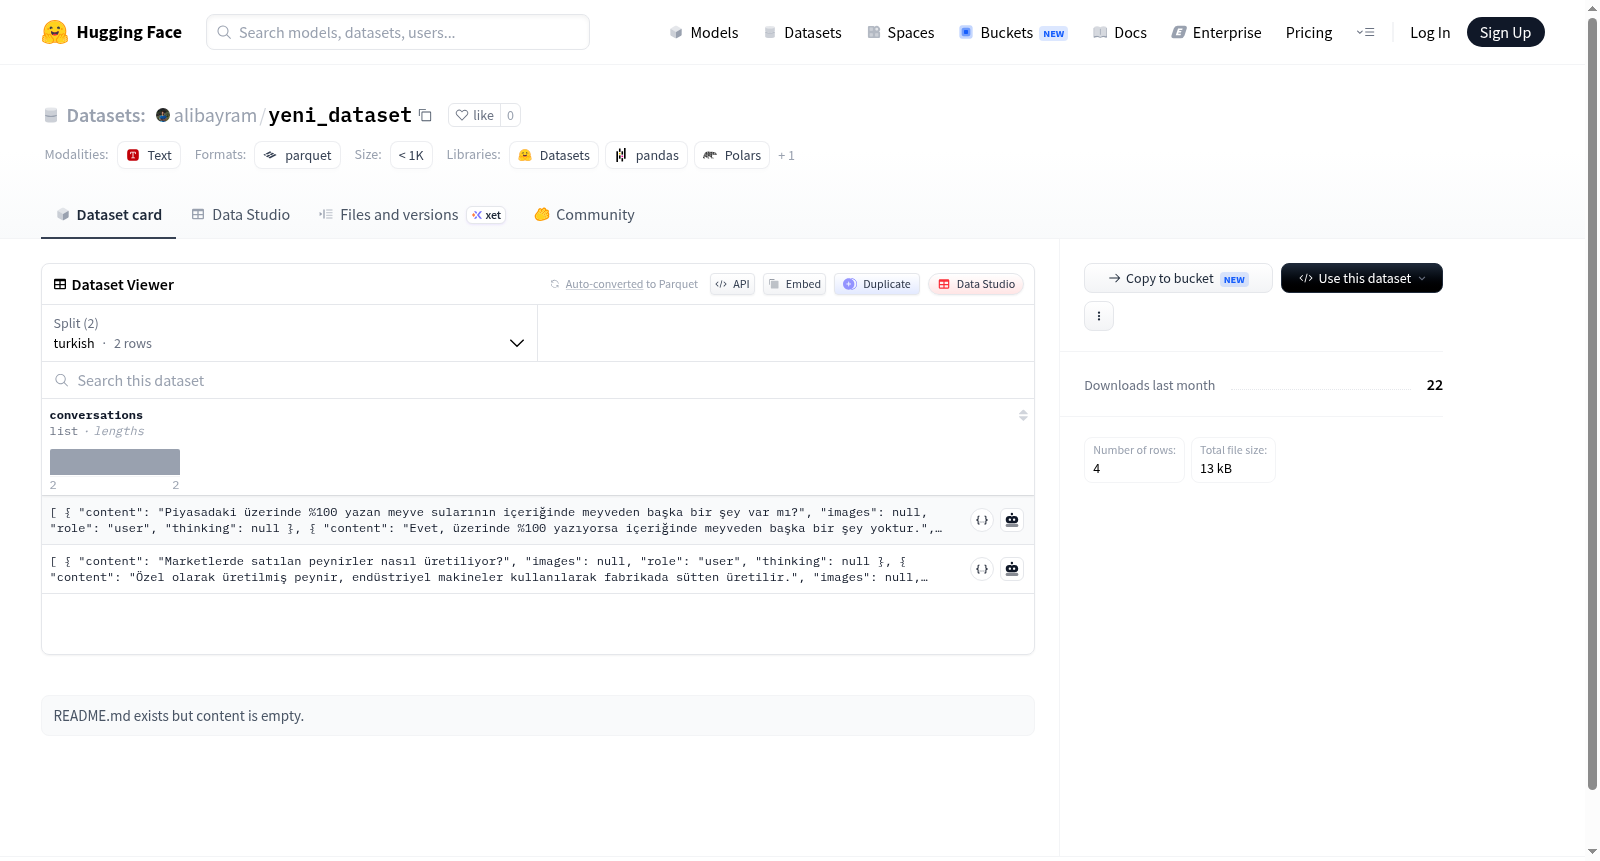
该数据集是一个小规模的双语对话数据集,包含土耳其语和英语两个语言版本。数据以对话形式组织,每个对话样本包含多轮对话内容,每轮对话记录有四个字段:content(对话文本内容)、images(预留图像字段,当前为空)、role(对话角色标识)和thinking(思维链或推理内容)。数据集结构设计适用于对话生成、角色扮演对话或思维链推理等自然语言处理任务。每个语言分割仅包含2个示例,总数据量较小,可能主要用于示例演示或模型测试目的。
This dataset is a small-scale bilingual dialogue dataset containing Turkish and English versions. The data is organized in dialogue format, with each dialogue sample consisting of multiple turns. Each turn includes four fields: content (dialogue text content), images (reserved image field, currently empty), role (dialogue role identifier), and thinking (chain-of-thought or reasoning content). The dataset structure is designed for natural language processing tasks such as dialogue generation, role-playing dialogue, or chain-of-thought reasoning. Each language split contains only 2 examples, with a small total data volume, likely intended for demonstration or model testing purposes.
数据集概述
数据集名称:alibayram/yeni_dataset
数据集地址:https://huggingface.co/datasets/alibayram/yeni_dataset
数据结构
该数据集包含以下字段:
conversations:对话列表,每个对话包含:content:字符串类型,对话内容。images:空类型,不包含图像数据。role:字符串类型,角色标识(如用户或助手)。thinking:字符串类型,思考过程。
数据拆分
数据集分为两个子集:
- turkish:包含 2 个样本,大小为 1074 字节。
- english:包含 2 个样本,大小为 1074 字节。
总规模
- 数据集总大小:2148 字节。
- 下载大小:9932 字节。
配置与文件路径
默认配置为 default,数据文件路径如下:
- 土耳其语子集:
data/turkish-* - 英语子集:
data/english-*