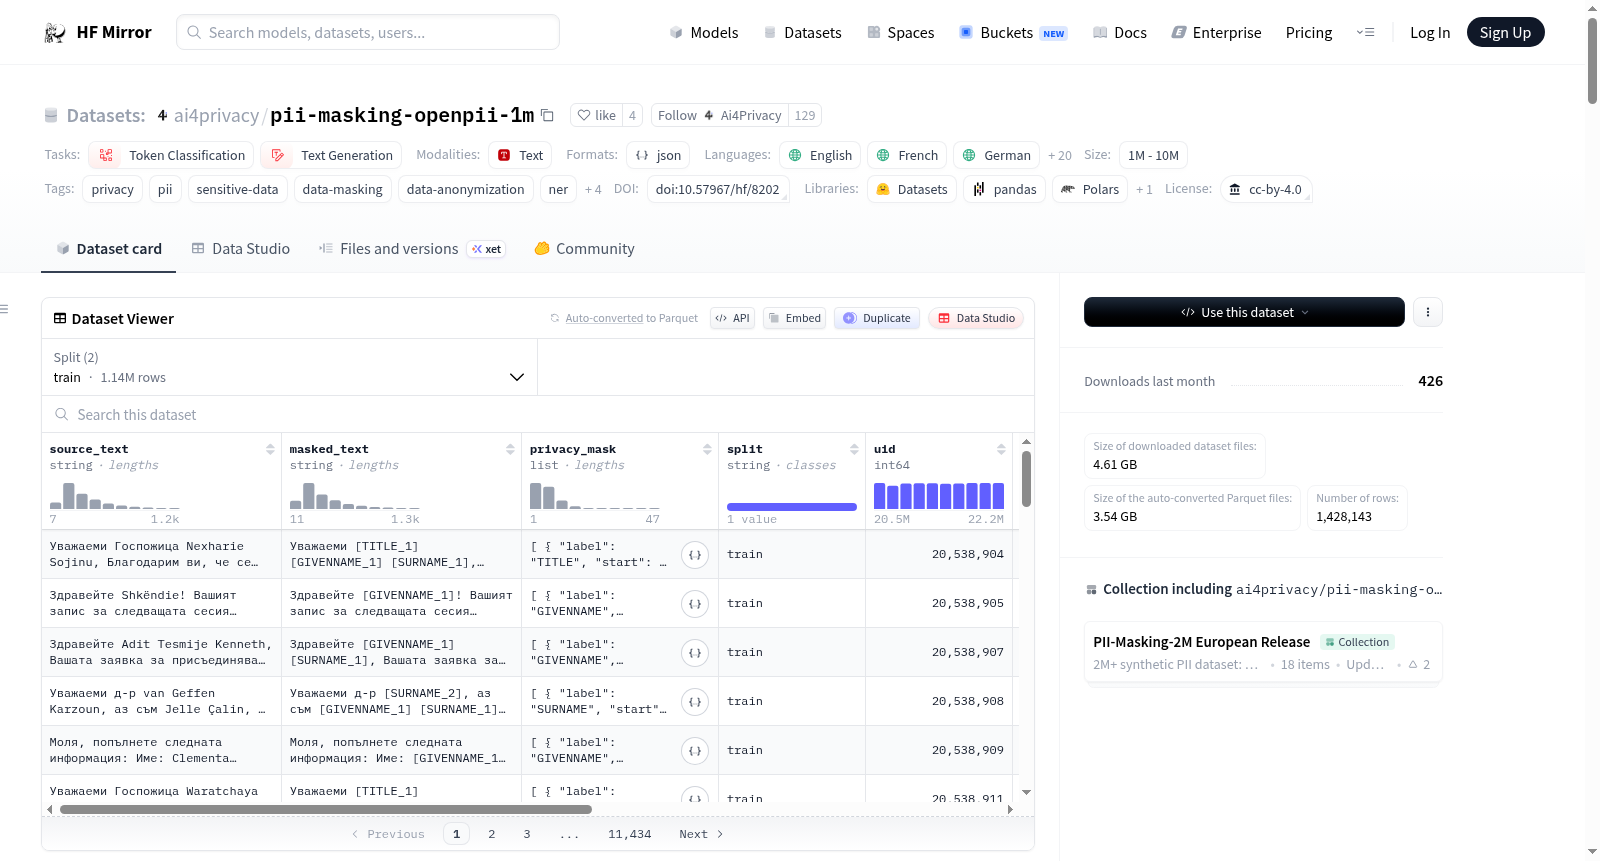
ai4privacy/pii-masking-openpii-1m
收藏资源简介:
--- license: other license_name: cc-by-4.0 language: - en - fr - de - es - it - nl - bg - cs - da - el - et - fi - hr - hu - lt - lv - pl - pt - ro - sk - sl - sr - sv task_categories: - token-classification - text-generation tags: - privacy - pii - sensitive-data - data-masking - data-anonymization - ner - synthetic - multilingual - ai4privacy - openpii pretty_name: "OpenPII 1M — Multilingual PII Masking Dataset (19 Labels, 23 Languages)" size_categories: - 1M<n<10M source_datasets: - original configs: - config_name: default data_files: - split: train path: data/train.jsonl - split: validation path: data/validation.jsonl --- # OpenPII 1M — Multilingual PII Masking Dataset <p align="center"> <img src="assets/logo.png" alt="Ai4Privacy" width="200"/> </p> ## Overview The **OpenPII 1M** dataset is a large-scale, multilingual collection of **1,428,143 synthetic text examples** with fine-grained PII (Personally Identifiable Information) annotations, spanning **23 European languages** and **19 entity types**. Built to advance open research in privacy-preserving NLP, this dataset enables the development and benchmarking of **Named Entity Recognition (NER)** models, **token classification** pipelines, and **data masking** systems that work across languages and borders. Each example contains the original text, a masked version with labeled placeholders, span-level annotations, and pre-computed BIO token labels compatible with transformer-based models (mBERT, XLM-R, ModernBERT, etc.). ## Dataset Details | Property | Value | |:---|:---| | **Total Examples** | 1,428,143 | | **Train Split** | 1,143,397 | | **Validation Split** | 284,746 | | **Unique Labels** | 19 | | **Languages** | 23 | | **Total Annotations** | 10,328,208 | | **Format** | JSON Lines (.jsonl) | | **License** | CC-BY-4.0 | | **Contact** | `enterprise@ai4privacy.com` | ## Language Coverage <p align="center"> <img src="assets/europe_language_map.png" alt="Language Coverage Map — Europe" width="800"/> </p> The dataset spans **29 regions** — 25 European countries plus Canada (CA), United States (US), Mexico (MX), and India (IN). <p align="center"> <img src="assets/language_distribution.png" alt="Language Distribution" width="800"/> </p> ## Label Taxonomy (19 Labels) <p align="center"> <img src="assets/label_distribution.png" alt="Label Distribution" width="800"/> </p> | Label | Count | Description | |:---|---:|:---| | `DATE` | 1,218,939 | Dates and temporal references | | `GIVENNAME` | 1,205,300 | First / given names | | `SURNAME` | 1,056,355 | Last / family names | | `EMAIL` | 769,479 | Email addresses | | `CITY` | 721,890 | City names | | `TITLE` | 670,650 | Personal titles (Mr, Dr, etc.) | | `TELEPHONENUM` | 574,865 | Phone numbers | | `AGE` | 512,150 | Age values | | `STREET` | 484,891 | Street names | | `BUILDINGNUM` | 476,224 | Building / house numbers | | `ZIPCODE` | 443,413 | Postal / ZIP codes | | `IDCARDNUM` | 333,065 | National ID card numbers | | `CREDITCARDNUMBER` | 320,504 | Credit card numbers | | `DRIVERLICENSENUM` | 286,935 | Driver's license numbers | | `GENDER` | 277,496 | Gender identifiers | | `TAXNUM` | 266,967 | Tax identification numbers | | `SEX` | 256,019 | Biological sex | | `SOCIALNUM` | 246,414 | Social security numbers | | `PASSPORTNUM` | 206,652 | Passport numbers | ## Data Structure Each line in the JSONL files is a JSON object: ```json { "source_text": "John Smith lives at 42 Rue de Rivoli, 75001 Paris.", "masked_text": "[GIVENNAME_1] [SURNAME_1] lives at [BUILDINGNUM_1] [STREET_1], [ZIPCODE_1] [CITY_1].", "privacy_mask": [ {"value": "John", "start": 0, "end": 4, "label": "GIVENNAME"}, {"value": "Smith", "start": 5, "end": 10, "label": "SURNAME"}, {"value": "42", "start": 20, "end": 22, "label": "BUILDINGNUM"}, {"value": "Rue de Rivoli", "start": 23, "end": 36, "label": "STREET"}, {"value": "75001", "start": 38, "end": 43, "label": "ZIPCODE"}, {"value": "Paris", "start": 44, "end": 49, "label": "CITY"} ], "split": "train", "uid": "openpii-abc123", "language": "fr", "region": "FR", "script": "Latn", "mbert_tokens": ["[CLS]", "John", "Smith", "lives", "..."], "mbert_token_classes": ["O", "B-GIVENNAME", "B-SURNAME", "O", "..."] } ``` ## Use Cases * **NER Research**: Train and evaluate multilingual token classification models for PII detection * **Privacy-Preserving NLP**: Build data anonymization and masking pipelines across 23 languages * **Multilingual Benchmarking**: Compare PII detection models across language families (Germanic, Romance, Slavic, Finno-Ugric, Baltic, Hellenic) * **Compliance Tools**: Develop systems for GDPR, CCPA, and other data protection regulations * **AI Safety**: Prevent language models from memorizing or exposing sensitive personal information ## Extended Taxonomies This dataset covers the **19 core identity labels**. For research or enterprise applications requiring extended label taxonomies — including **82+ labels** across health (PHI), financial (PFI), digital (PDI), work (PWI), and location (PLI) categories — contact our team: 📧 **Email:** [`enterprise@ai4privacy.com`](mailto:enterprise@ai4privacy.com) 🌐 **Website:** [www.Ai4Privacy.com](https://www.ai4privacy.com) 🔗 **Contact Form:** [https://forms.gle/oDDYqQkyoTB93otHA](https://forms.gle/oDDYqQkyoTB93otHA) ## Related Datasets | Dataset | Labels | Languages | Size | Category | |:---|:---|:---|:---|:---| | **pii-masking-2m** | 82+ | 24 | 2M+ | Full EPII taxonomy | | **phi-masking-100k** | 20 | 8 | 100K+ | Personal Health Information | | **pfi-masking-100k** | 20 | 8 | 100K+ | Personal Financial Information | | **pdi-masking-100k** | 20 | 8 | 100K+ | Personal Digital Information | | **pwi-masking-100k** | 20 | 8 | 100K+ | Personal Work Information | | **pli-masking-100k** | 20 | 8 | 100K+ | Personal Location Information | --- ## p5y Data Analytics This dataset is built on the [p5y](https://p5y.org) framework - think of it as i18n but for privacy. Just as i18n (internationalization) translates content into different locales, p5y translates sensitive data into privacy-safe formats through a standardized 3-step approach: 1. **Awareness** - Scan and markup private entities in unstructured text, producing a structured privacy mask with entity types, distribution, density, and risk assessment. 2. **Protection** - Control identified personal data through masking, pseudonymization, or k-anonymization, tailored to the specific use case and regulatory requirements. 3. **Quality Assurance** - Measure remaining privacy risk after anonymization, evaluating de-anonymization risks through expert annotation and automated assessment. Learn more at [p5y.org](https://p5y.org) --- ## About Ai4Privacy At Ai4Privacy, we are building the global seatbelt for Artificial Intelligence — enabling innovation while safeguarding personal information. We develop state-of-the-art datasets and tools for privacy-preserving AI. * **Newsletter & Updates:** [www.Ai4Privacy.com](https://www.ai4privacy.com) * **Join our Community:** [Discord](https://discord.gg/kxSbJrUQZF) * **Contribute/Feedback:** [Open Data Access Form](https://forms.gle/iU5BvMPGkvvxnHBa7) --- ## Licensing and Terms of Use * **License:** [CC-BY-4.0](https://creativecommons.org/licenses/by/4.0/). Copyright © 2026 Ai Suisse SA. * **Permitted Use:** Research, commercial use, redistribution, and modification — subject to attribution requirements under CC-BY-4.0. * **Attribution:** When using this dataset, please credit "Ai4Privacy / Ai Suisse SA" and link to this repository. * **Responsible Use:** Use must comply with all applicable data privacy laws and regulations. This dataset contains **synthetic PII only** — no real personal data is included. * **Citation:** ```bibtex @dataset{ai4privacy_openpii_1m_2026, author = {Ai4Privacy}, title = {OpenPII 1M — Multilingual PII Masking Dataset (19 Labels, 23 Languages)}, year = 2026, publisher = {Hugging Face}, url = {https://huggingface.co/datasets/ai4privacy/pii-masking-openpii-1m} } ``` ## Legal Disclaimer **No Warranty & Use at Your Own Risk:** This dataset is provided **"as is"** without warranties of any kind. Ai4Privacy and Ai Suisse SA make **no representations** regarding accuracy, completeness, or suitability. Use is **at your own risk**. **No Liability:** Ai4Privacy, Ai Suisse SA, and affiliates **shall not be liable** for any damages (direct, indirect, consequential, etc.) arising from the use or inability to use this dataset. **Compliance & Responsibility:** Users are solely responsible for ensuring their use complies with **all applicable laws, regulations, and ethical guidelines**, including data privacy laws (e.g., GDPR, CCPA) and AI regulations. **This dataset contains synthetic PII only — no real personal data is included.** Ai4Privacy is a project affiliated with [Ai Suisse SA](https://www.aisuisse.com/).