
DREAM
收藏资源简介:
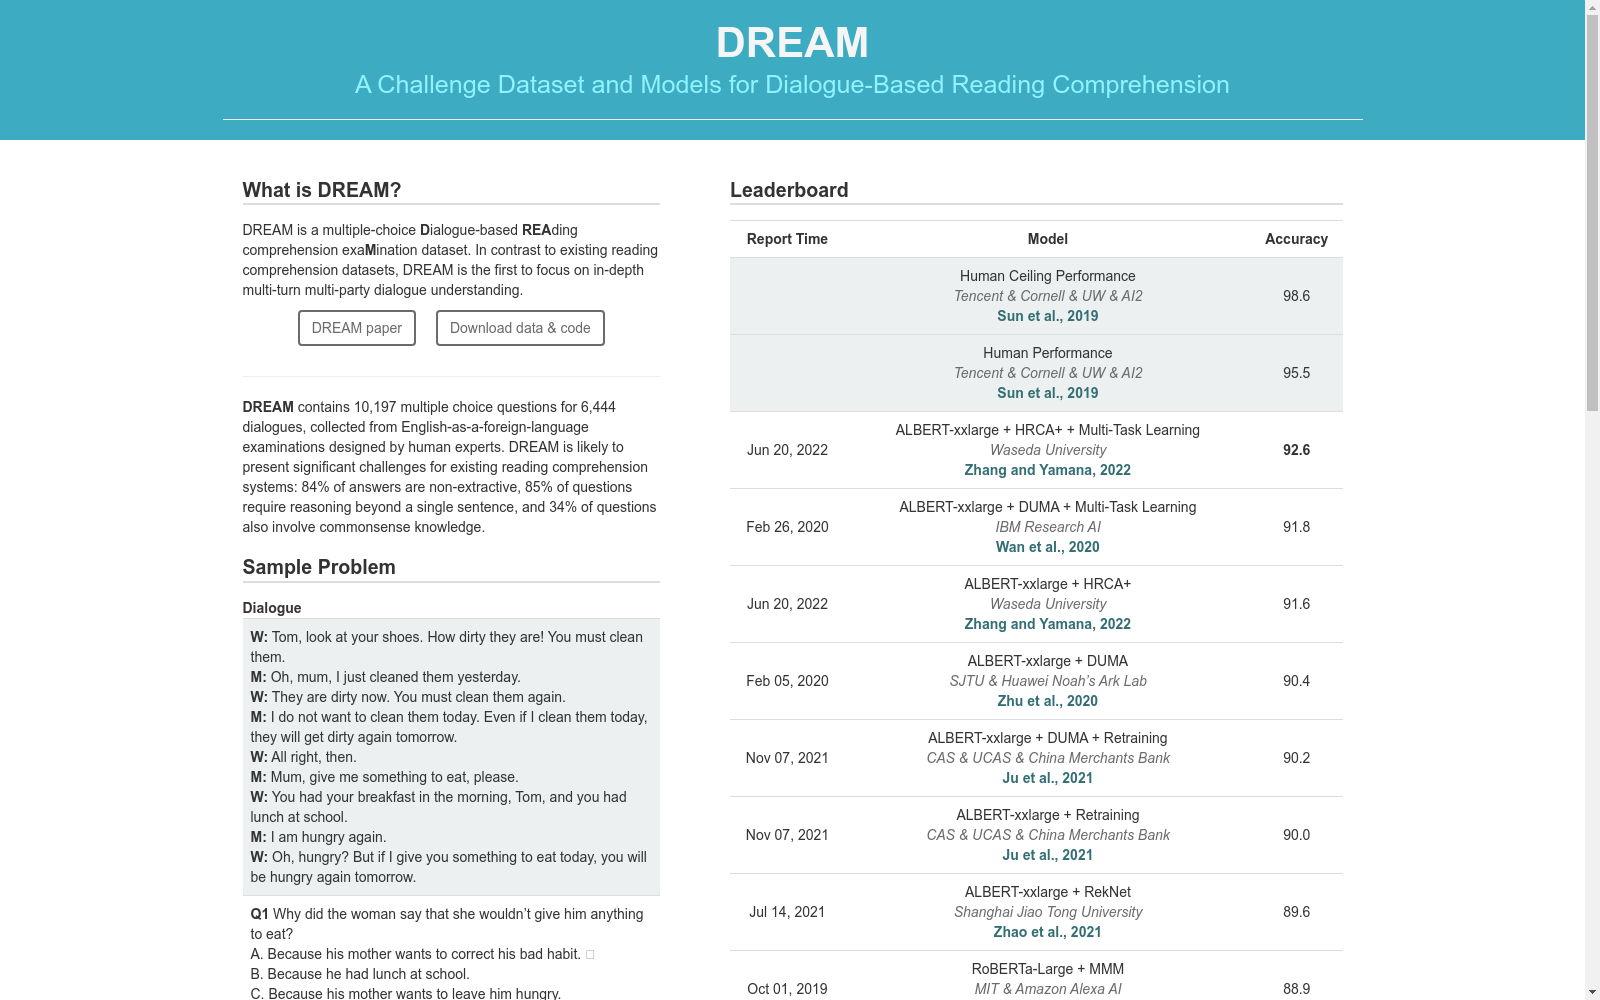
DREAM是由腾讯AI实验室创建的首个基于对话的多项选择阅读理解数据集。该数据集包含从英语作为外语考试中收集的10,197个多项选择题,涉及6,444个对话,旨在评估中国英语学习者的理解水平。DREAM专注于深入的多轮多方对话理解,84%的答案是非提取性的,85%的问题需要超越单一句子的推理,34%的问题还涉及常识知识。数据集涵盖日常生活中的各种话题和场景,如街头、电话、教室或图书馆、机场或办公室或商店的对话。DREAM的创建旨在推动机器阅读理解的研究,并促进对话理解的发展,解决机器在理解复杂对话中的挑战。
DREAM is the first dialogue-based multiple-choice reading comprehension dataset created by Tencent AI Lab. It contains 10,197 multiple-choice questions collected from English as a Foreign Language (EFL) tests, encompassing 6,444 dialogues, and is designed to evaluate the comprehension proficiency of Chinese English learners. DREAM focuses on in-depth understanding of multi-turn and multi-party dialogues: 84% of its answers are non-extractive, 85% of the questions require reasoning beyond a single sentence, and 34% of the questions also involve common-sense knowledge. The dataset covers a wide range of daily topics and scenarios, including dialogues set in places such as streets, phone calls, classrooms or libraries, airports, offices and shops. The creation of DREAM aims to promote research on machine reading comprehension, advance the development of dialogue understanding, and address the challenges that machines face in comprehending complex dialogues.
- DREAM数据集首次发表,作为一项挑战赛的一部分,旨在评估和提升生物信息学领域的预测模型。
- DREAM挑战赛首次应用于基因调控网络的预测,吸引了全球研究者的参与,推动了该领域的技术进步。
- DREAM数据集扩展至包括蛋白质相互作用网络的预测,进一步丰富了数据集的内容和应用范围。
- DREAM挑战赛引入药物反应预测的竞赛,标志着数据集在药物研发领域的应用开始。
- DREAM数据集被广泛应用于机器学习和数据挖掘算法的评估,成为该领域的重要基准数据集之一。
- DREAM挑战赛新增了癌症基因组学相关的预测任务,推动了精准医疗的发展。
- DREAM数据集的应用扩展至环境科学和生态系统建模,展示了其在跨学科研究中的潜力。


