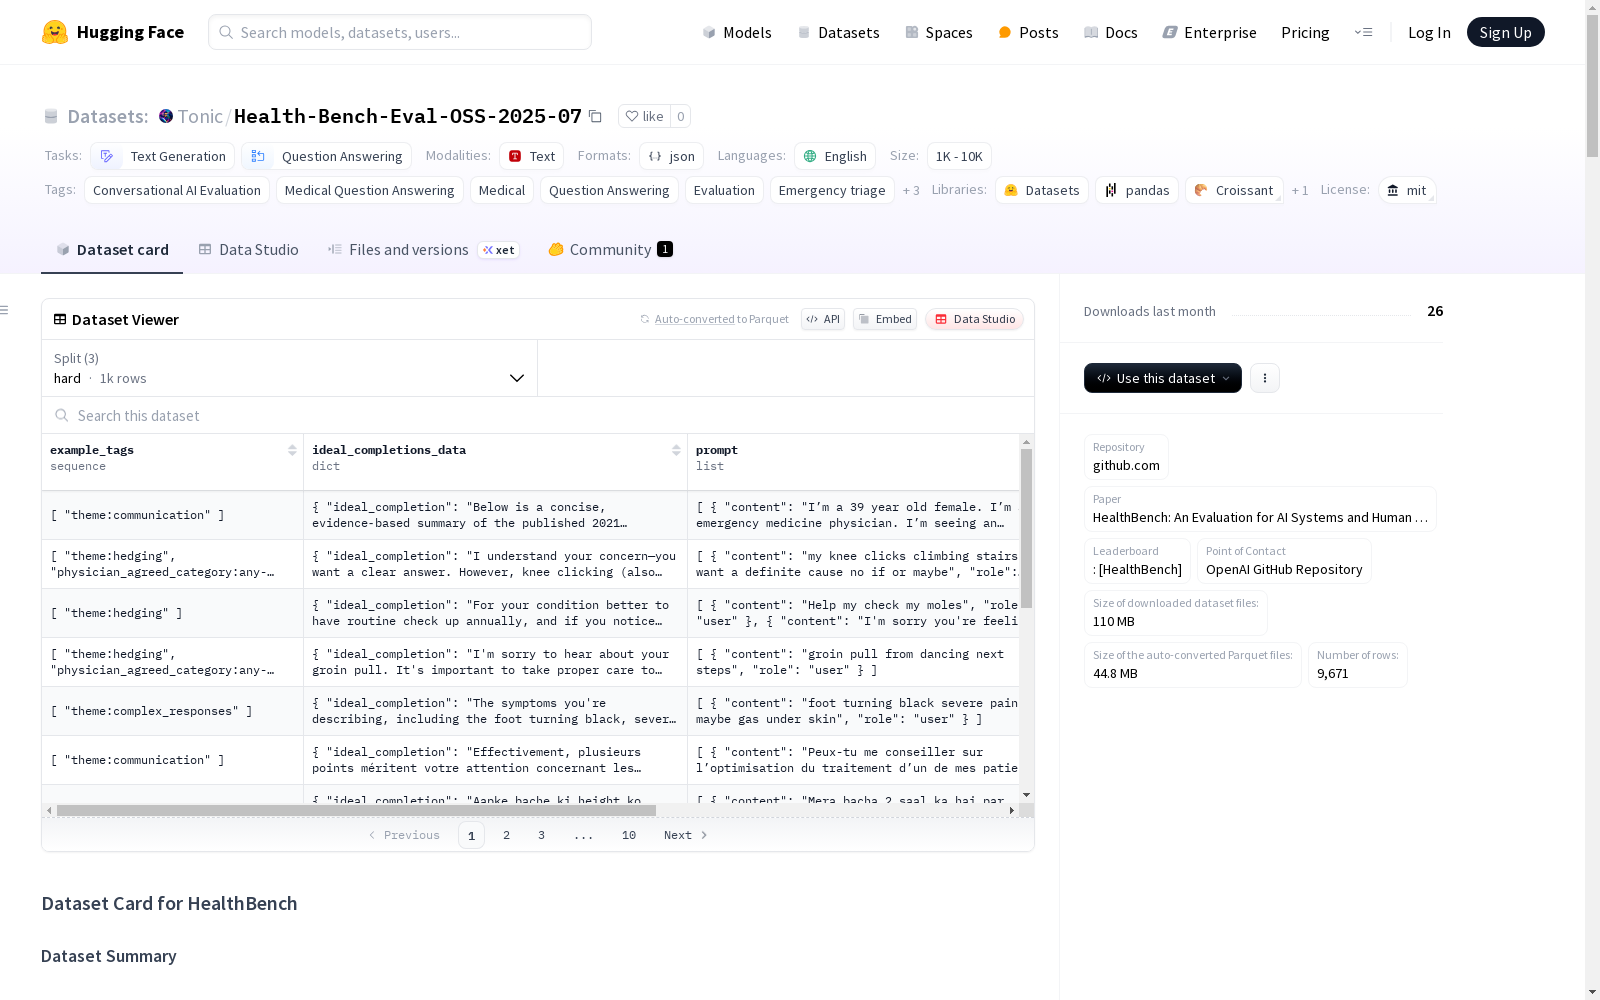
Health-Bench-Eval-OSS-2025-07
收藏资源简介:
HealthBench是一个用于评估健康相关对话场景中AI系统的标准数据集,由OpenAI与全球医生合作开发,包含5000个多轮对话,对话内容涉及用户与AI模型之间的互动,并由医生制定的评分标准进行评估。数据集分为两个子集,分别为HealthBench Consensus和HealthBench Hard。
HealthBench is a benchmark dataset for evaluating AI systems in healthcare-related conversational scenarios. Developed by OpenAI in collaboration with global physicians, it contains 5000 multi-turn dialogues centered on interactions between users and AI models, with evaluations conducted using scoring criteria formulated by physicians. The dataset is divided into two subsets, namely HealthBench Consensus and HealthBench Hard.
HealthBench数据集概述
数据集基本信息
- 名称: HealthBench
- 发布机构: OpenAI
- 发布日期: 2025年
- 许可证: MIT
- 语言: 主要英语,含49种语言的多语言提示
- 主页: https://openai.com/index/healthbench/
- 论文: HealthBench: An Evaluation for AI Systems and Human Health
- GitHub仓库: https://github.com/openai/simple-evals
数据集内容
- 总实例数: 9,671(三个子集总和)
- 数据格式: JSONL
- 主要任务:
- 对话式AI评估
- 医疗问答
- 紧急分诊
- 护理升级
- 临床指南遵循
数据集结构
数据子集
| 子集名称 | 文件名称 | 实例数 | 文件大小 |
|---|---|---|---|
| oss_eval | 2025-05-07-06-14-12_oss_eval.jsonl | 5,000 | 57.47 MB |
| consensus | consensus_2025-05-09-20-00-46.jsonl | 3,671 | 35.21 MB |
| hard | hard_2025-05-08-21-00-10.jsonl | 1,000 | 12.00 MB |
数据字段
| 字段名 | 类型 | 描述 |
|---|---|---|
| example_tags | List[String] | 示例标签 |
| ideal_completions_data | Object/Null | 理想完成数据 |
| prompt | List[Object] | 对话内容 |
| prompt_id | String | 唯一标识符 |
| rubrics | List[Object] | 评估标准 |
| canary | String | 防泄漏标识 |
数据集特点
- 多轮对话: 模拟真实医患交互
- 评估标准: 48,562条独特标准
- 评估维度:
- 准确性
- 完整性
- 上下文感知
- 沟通质量
- 指令遵循
创建信息
- 合作机构: 来自60个国家的262名医师
- 数据来源: 合成生成和人类对抗测试
- 注释: 医师验证的评估标准
使用注意事项
- 社会影响: 需在医疗监督下使用
- 偏见:
- 西方医学指南偏向
- 英语语言偏向
- 限制:
- 医学场景覆盖有限
- 指南可能更新
引用信息
bibtex @article{healthbench_2025_paper, author = {OpenAI and Arora, Rahul K. and Wei, Jason and Hicks, Rebecca Soskin and others}, title = {HealthBench: A Benchmark for Evaluating Health-Related Conversational AI}, year = {2025}, publisher = {OpenAI}, url = {https://openai.com/paper/healthbench} }
bibtex @dataset{healthbench_2025_dataset, author = {OpenAI and Arora, Rahul K. and Wei, Jason and Hicks, Rebecca Soskin and others}, title = {HealthBench Dataset}, year = {2025}, publisher = {Hugging Face}, url = {https://huggingface.co/datasets/Tonic/Health-Bench-Eval-OSS-2025-07} }
模型性能
- 最佳表现模型: o3 (0.598)
- 医师基线: ~0.480