orca-agentinstruct-1M-v1-cleaned-fixed-sharegpt
收藏资源简介:
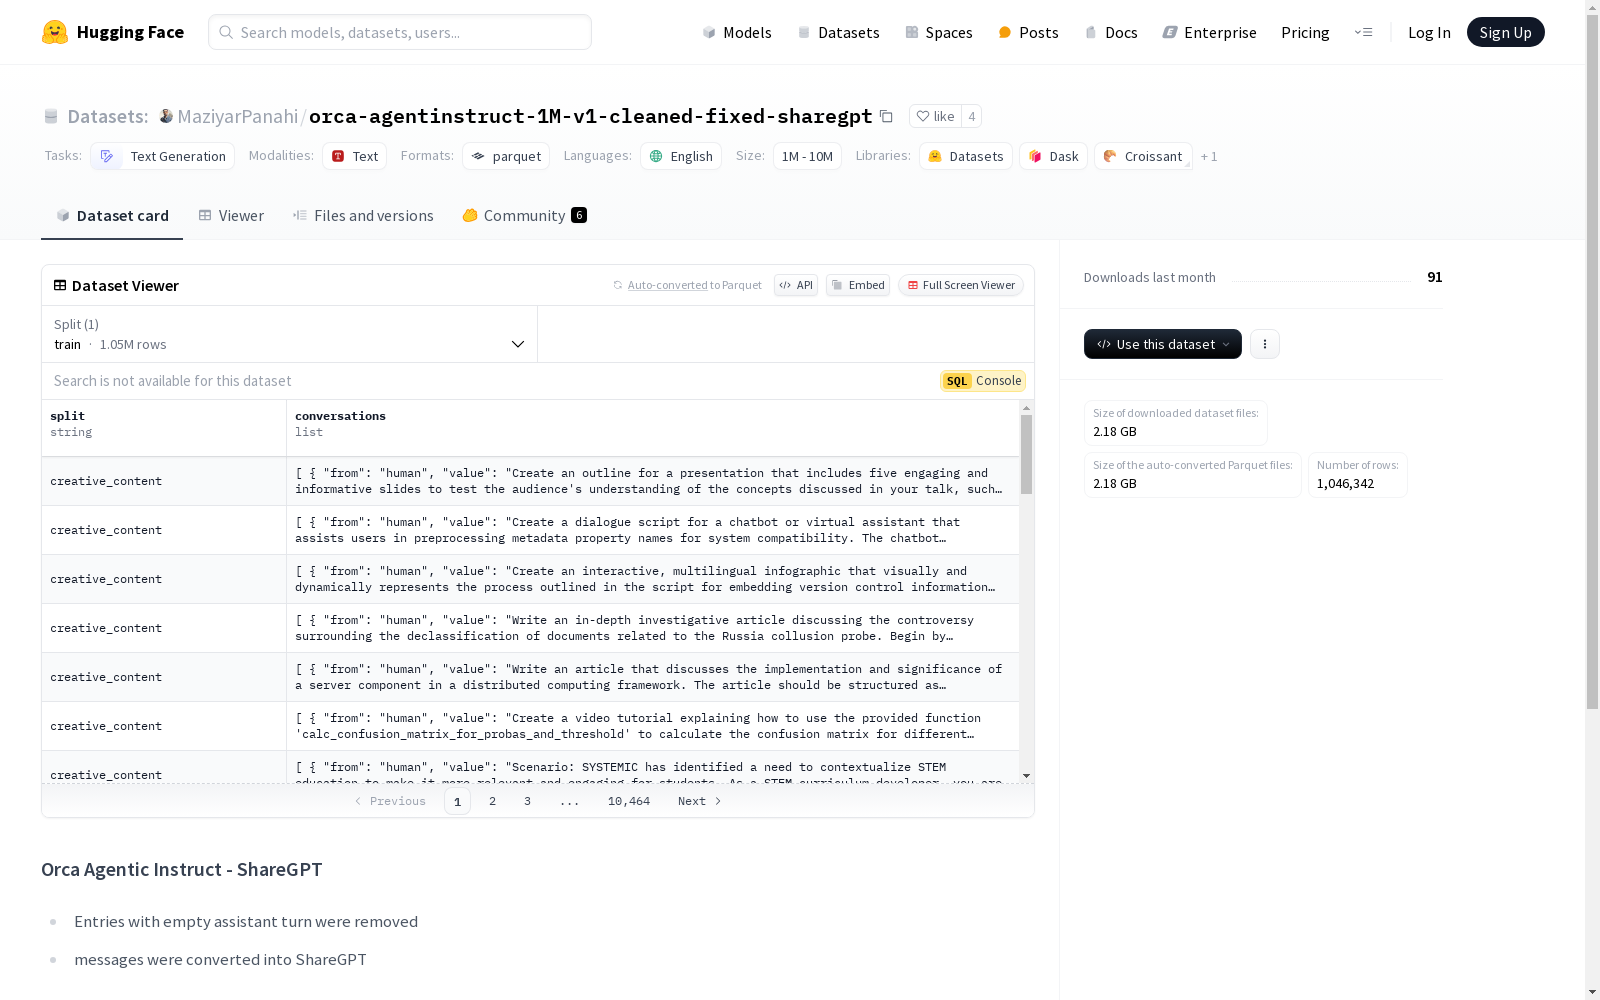
该数据集包含两个主要特征:'split'和'conversations'。'split'是一个字符串类型的特征,表示数据集的分区。'conversations'是一个列表,包含两个子特征:'from'和'value',均为字符串类型。数据集有一个训练分区,包含1046342个样本,总大小为4631663991.97698字节。数据集的下载大小为2179975225字节。数据集的配置名为'default',数据文件路径为'data/train-*'。数据集的任务类别是'text-generation',语言为英语,大小类别为'1B<n<10B'。数据集的初始样本数为1046410,删除了68个样本,剩余样本数为1046342,删除率为0.01%。数据集的来源是mlabonne/orca-agentinstruct-1M-v1-cleaned。
This dataset includes two core features: 'split' and 'conversations'. The 'split' feature is a string-type attribute that indicates the dataset partition. The 'conversations' feature is a list containing two sub-features: 'from' and 'value', both of string type. The dataset has one training partition with 1,046,342 samples, with a total size of 4631663991.97698 bytes. The download size of the dataset is 2179975225 bytes. The dataset configuration is named 'default', and the data file path is 'data/train-*'. The task category is 'text-generation', the language is English, and the size category is '1B < n < 10B'. The initial number of samples was 1,046,410; 68 samples were removed, leaving 1,046,342 remaining samples, with a removal rate of 0.01%. This dataset is sourced from mlabonne/orca-agentinstruct-1M-v1-cleaned.
Orca Agentic Instruct - ShareGPT 数据集概述
数据集信息
- 特征:
split: 类型为字符串conversations: 列表类型,包含以下子特征:from: 类型为字符串value: 类型为字符串
- 分割:
train: 包含 1,046,342 个样本,占用 4,631,663,991.97698 字节
- 下载大小: 2,179,975,225 字节
- 数据集大小: 4,631,663,991.97698 字节
- 配置:
default: 数据文件路径为data/train-*
- 任务类别: 文本生成
- 语言: 英语
- 大小类别: 1B < n < 10B
数据处理
- 初始样本数: 1,046,410
- 移除样本数: 68
- 剩余样本数: 1,046,342
- 移除率: 0.01%
数据来源