softcatala/wikimedia-common-audio-catalan
收藏资源简介:
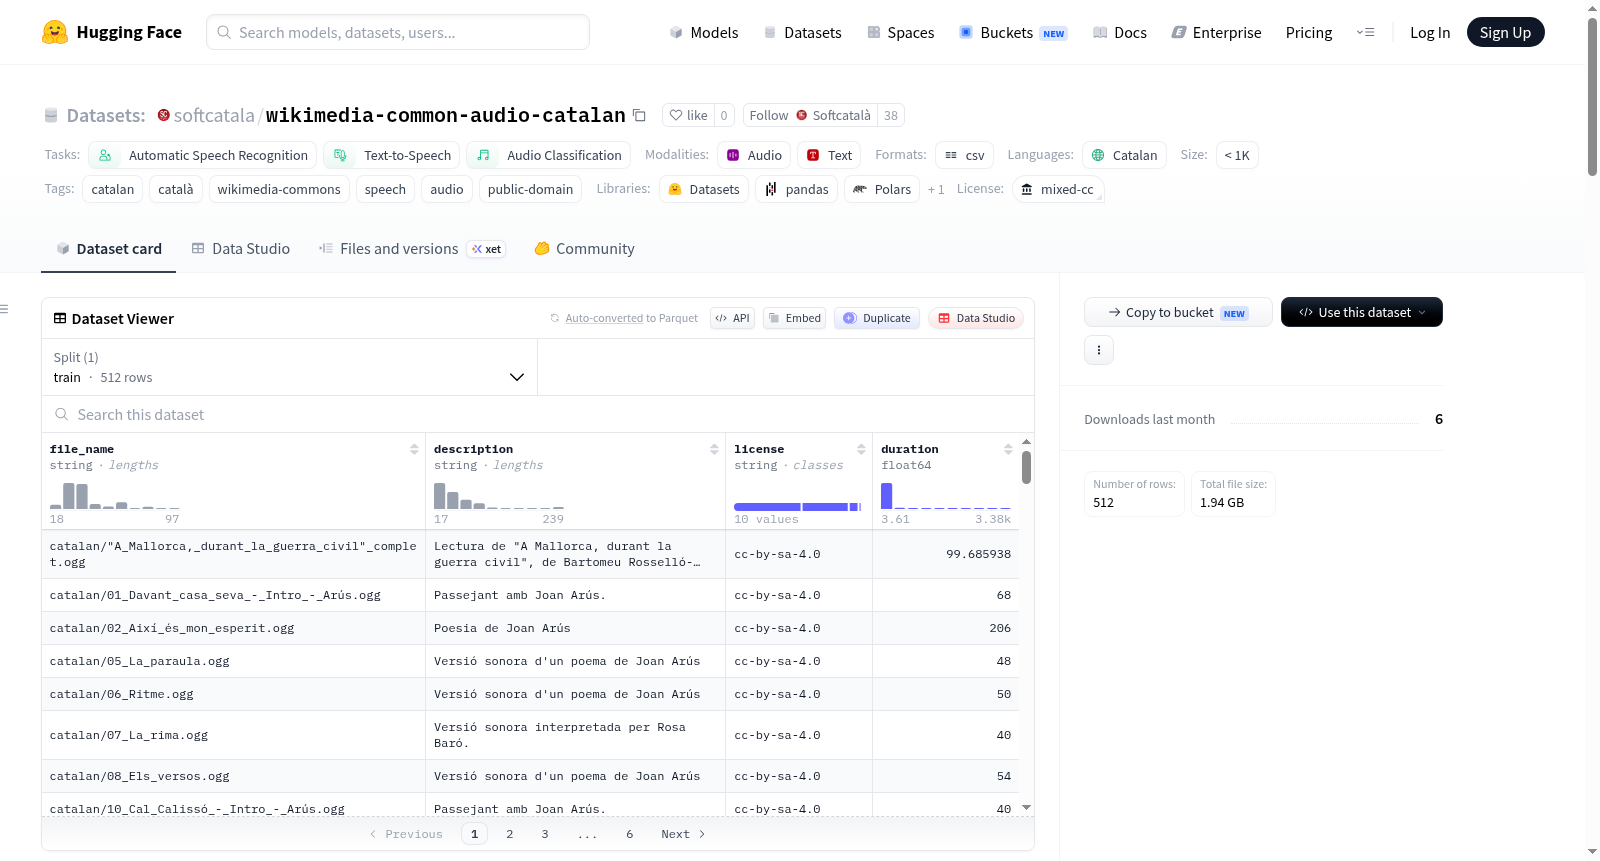
该数据集是一个从Wikimedia Commons收集的加泰罗尼亚语音频文件集合,包含512个音频文件(.ogg和.mp3格式),总时长约30.7小时。音频内容涵盖诗歌朗诵、采访、广播节目片段、语音样本、方言录音、口语文章等口语内容,由Wikimedia Commons社区贡献。数据集采用Hugging Face audiofolder布局,包含metadata.csv文件,其中记录了音频文件的相对路径、描述(来自Wikimedia Commons的加泰罗尼亚语描述)、许可证信息和持续时间(秒)。数据来源为Wikimedia Commons中分类为加泰罗尼亚语音频的文件,模态为音频和文本元数据。许可方面,数据集是多种免费许可证的汇编,包括CC0/公共领域、CC BY-SA 4.0、CC BY-SA 3.0等,每个文件的许可证记录在metadata.csv的license列中,使用时需按文件遵守。数据集无验证转录,描述字段是Commons标题而非对齐的转录文本;录音条件异构,来自不同贡献者和设备;说话人人口统计信息未知。
This dataset is a collection of Catalan audio files sourced from Wikimedia Commons, containing 512 audio files in .ogg and .mp3 formats with a total duration of approximately 30.7 hours. The audio content covers various spoken materials including poetry recitations, interviews, radio program clips, speech samples, dialect recordings, and spoken articles, all contributed by the Wikimedia Commons community. The dataset follows the Hugging Face audiofolder layout, and includes a metadata.csv file that records the relative path of each audio file, its Catalan description from Wikimedia Commons, license information, and duration in seconds. The data originates from files categorized as Catalan audio on Wikimedia Commons, with modalities of audio and textual metadata. Regarding licensing, this dataset compiles multiple free licenses such as CC0/public domain, CC BY-SA 4.0, and CC BY-SA 3.0; the license of each individual file is stored in the "license" column of metadata.csv, and users must comply with the license terms of each file when using the dataset. The dataset has no verified transcriptions, and the description field consists of Commons titles rather than aligned transcription texts. The recording conditions are heterogeneous, originating from different contributors and devices, and speaker demographic information is unknown.